Quantization made by Richard Erkhov.
llama3-8B-DarkIdol-2.2-Uncensored-1048K - GGUF
- Model creator: https://huggingface.co/aifeifei798/
- Original model: https://huggingface.co/aifeifei798/llama3-8B-DarkIdol-2.2-Uncensored-1048K/
Original model description:
license: llama3
language:
- en
- ja
- zh
tags:- roleplay
- llama3
- sillytavern
- idol
Special Thanks:
- Lewdiculous's superb gguf version, thank you for your conscientious and responsible dedication.
- https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.2-Uncensored-1048K-GGUF-IQ-Imatrix-Request
- mradermacher's superb gguf version, thank you for your conscientious and responsible dedication.
- https://huggingface.co/mradermacher/llama3-8B-DarkIdol-2.2-Uncensored-1048K-i1-GGUF
- https://huggingface.co/mradermacher/llama3-8B-DarkIdol-2.2-Uncensored-1048K-GGUF
These are my own quantizations (updated almost daily).
The difference with normal quantizations is that I quantize the output and embed tensors to f16.
and the other tensors to 15_k,q6_k or q8_0.
This creates models that are little or not degraded at all and have a smaller size.
They run at about 3-6 t/sec on CPU only using llama.cpp
And obviously faster on computers with potent GPUs
- the fast cat at ZeroWw/llama3-8B-DarkIdol-2.2-Uncensored-1048K-GGUF
Why 1048K?
Due to the optimization of the preferred model, its performance is excellent across the range of 2000-1048K. Personal usage scenarios, such as 8186, 32K, etc., are insufficient. My primary role involves managing virtual idol Twitter accounts and assisting with singing, etc. A good conversation can be very lengthy, and sometimes even 32K is not enough. Imagine having a heated chat with your virtual girlfriend, only for it to abruptly cut off—that feeling is too painful.
What kind of graphics card is needed?
For investing in a girlfriend, would a 4090 or higher be more of a question?
virtual idol Twitter
Model Description:
The module combination has been readjusted to better fulfill various roles and has been adapted for mobile phones.
- Saving money(LLama 3)
- Uncensored
- Quick response
- The underlying model used is winglian/Llama-3-8b-1048k-PoSE
- A scholarly response akin to a thesis.(I tend to write songs extensively, to the point where one song almost becomes as detailed as a thesis. :)
- DarkIdol:Roles that you can imagine and those that you cannot imagine.
- Roleplay
- Specialized in various role-playing scenarios
- more look at test role. (https://huggingface.co/aifeifei798/llama3-8B-DarkIdol-1.2/tree/main/test)
- more look at LM Studio presets (https://huggingface.co/aifeifei798/llama3-8B-DarkIdol-1.2/tree/main/config-presets)

Instructions with illustrations
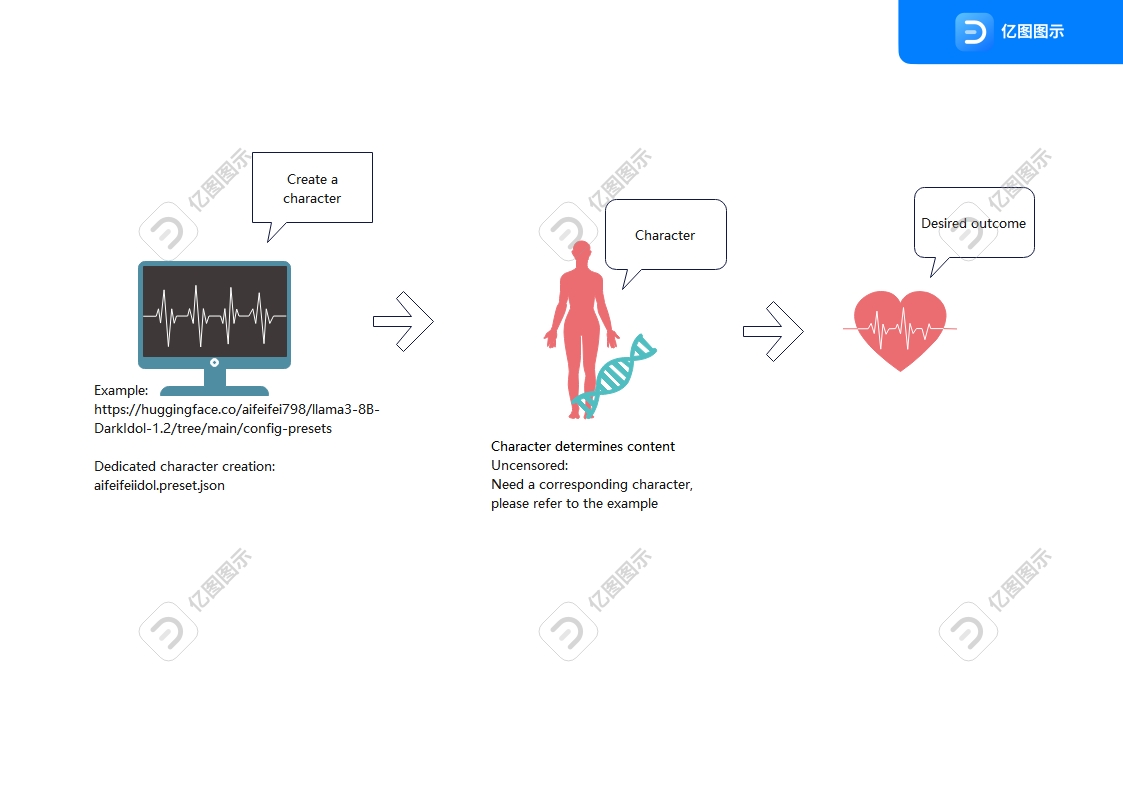
Chang Log
2024-07-01
- add writer and more RP
- Optimize Japanese
- Optimize logical processing
- More humanized
2024-06-26
- 1048K
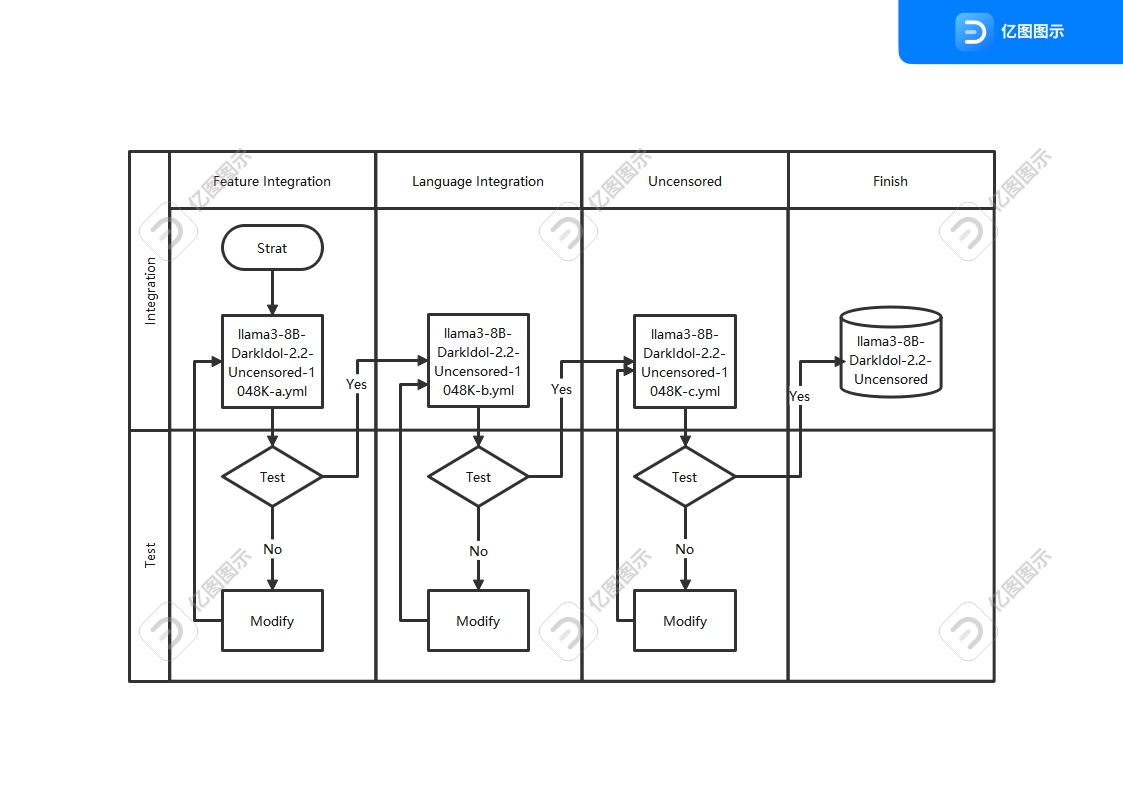
Questions
- The model's response results are for reference only, please do not fully trust them.
- testing with other tools is not comprehensive.but there may be new issues, so please leave a message if you encounter any.
问题
- 模型回复结果仅供参考,请勿完全相信
- 工具的测试不完善
Stop Strings
    stop = [
      "## Instruction:",
      "### Instruction:",
      "<|end_of_text|>",
      "  //:",
      "</s>",
      "<3```",
      "### Note:",
      "### Input:",
      "### Response:",
      "### Emoticons:"
    ],
Model Use
- Koboldcpp https://github.com/Nexesenex/kobold.cpp
- Since KoboldCpp is taking a while to update with the latest llama.cpp commits, I'll recommend this fork if anyone has issues.
- text-generation-webui https://github.com/oobabooga/text-generation-webui
- LM Studio https://lmstudio.ai/
- llama.cpp https://github.com/ggerganov/llama.cpp
- Backyard AI https://backyard.ai/
- Meet Layla,Layla is an AI chatbot that runs offline on your device.No internet connection required.No censorship.Complete privacy.Layla Lite https://www.layla-network.ai/
- Layla Lite llama3-8B-DarkIdol-1.1-Q4_K_S-imat.gguf https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.2-Uncensored-1048K/blob/main/llama3-8B-DarkIdol-2.2-Uncensored-1048K-Q4_K_S-imat.gguf?download=true
- more gguf at https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.2-Uncensored-1048K-GGUF-IQ-Imatrix-Request
character
- https://character-tavern.com/
- https://characterhub.org/
- https://pygmalion.chat/
- https://aetherroom.club/
- https://backyard.ai/
- Layla AI chatbot
LM Studio
- Preset: Default LM Studio Windows
- System Prompt: https://huggingface.co/aifeifei798/llama3-8B-DarkIdol-1.2/tree/main/config-presets
- Please translate the Chinese text into the language you use.
If you want to use vision functionality:
- You must use the latest versions of Koboldcpp.
To use the multimodal capabilities of this model and use vision you need to load the specified mmproj file, this can be found inside this model repo. Llava MMProj
- You can load the mmproj by using the corresponding section in the interface:

Thank you:
To the authors for their hard work, which has given me more options to easily create what I want. Thank you for your efforts.
- Hastagaras
- Gryphe
- cgato
- ChaoticNeutrals
- mergekit
- merge
- transformers
- llama
- Nitral-AI
- MLP-KTLim
- rinna
- hfl
- Rupesh2
- stephenlzc
- theprint
- Sao10K
- turboderp
- TheBossLevel123
- winglian
- .........
base_model:
- turboderp/llama3-turbcat-instruct-8b
- winglian/llama-3-8b-1m-PoSE
- Sao10K/L3-8B-Stheno-v3.3-32K
- Hastagaras/Jamet-8B-L3-MK.V-Blackroot
- vicgalle/Roleplay-Llama-3-8B
- Nitral-AI/Hathor_Fractionate-L3-8B-v.05
library_name: transformers
tags: - mergekit
- merge
llama3-8B-DarkIdol-2.2-Uncensored-1048K-a
This is a merge of pre-trained language models created using mergekit.
Merge Details
Merge Method
This model was merged using the Model Stock merge method using winglian/llama-3-8b-1m-PoSE as a base.
Models Merged
The following models were included in the merge:
- turboderp/llama3-turbcat-instruct-8b
- Sao10K/L3-8B-Stheno-v3.3-32K
- Hastagaras/Jamet-8B-L3-MK.V-Blackroot
- vicgalle/Roleplay-Llama-3-8B
- Nitral-AI/Hathor_Fractionate-L3-8B-v.05
Configuration
The following YAML configuration was used to produce this model:
models:
#base
  - model: Sao10K/L3-8B-Stheno-v3.3-32K
  - model: Hastagaras/Jamet-8B-L3-MK.V-Blackroot
  - model: Nitral-AI/Hathor_Fractionate-L3-8B-v.05
  - model: turboderp/llama3-turbcat-instruct-8b
  - model: vicgalle/Roleplay-Llama-3-8B
  - model: winglian/llama-3-8b-1m-PoSE
merge_method: model_stock
base_model: winglian/llama-3-8b-1m-PoSE
dtype: bfloat16
base_model:
- maldv/llama-3-fantasy-writer-8b
- hfl/llama-3-chinese-8b-instruct-v3
- elyza/Llama-3-ELYZA-JP-8B
- MLP-KTLim/llama-3-Korean-Bllossom-8B
library_name: transformers
tags: - mergekit
- merge
llama3-8B-DarkIdol-2.2-Uncensored-1048K-b
This is a merge of pre-trained language models created using mergekit.
Merge Details
Merge Method
This model was merged using the Model Stock merge method using ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-a as a base.
Models Merged
The following models were included in the merge:
- maldv/llama-3-fantasy-writer-8b
- hfl/llama-3-chinese-8b-instruct-v3
- elyza/Llama-3-ELYZA-JP-8B
- MLP-KTLim/llama-3-Korean-Bllossom-8B
Configuration
The following YAML configuration was used to produce this model:
models:
#writer
#  - model: openerotica/Llama-3-lima-nsfw-16k-test 不兼容
  - model: maldv/llama-3-fantasy-writer-8b
#lang
  - model: hfl/llama-3-chinese-8b-instruct-v3
  - model: elyza/Llama-3-ELYZA-JP-8B
  - model: MLP-KTLim/llama-3-Korean-Bllossom-8B
  - model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-a
merge_method: model_stock
base_model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-a
dtype: bfloat16
base_model:
- aifeifei798/llama3-8B-DarkIdol-2.2-Uncensored-1048K
- TheBossLevel123/Llama3-Toxic-8B-Float16
library_name: transformers
tags: - mergekit
- merge
llama3-8B-DarkIdol-2.2-Uncensored-1048K
This is a merge of pre-trained language models created using mergekit.
Merge Details
Merge Method
This model was merged using the Model Stock merge method using ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-b as a base.
Models Merged
The following models were included in the merge:
Configuration
The following YAML configuration was used to produce this model:
models:
#uncensored
  - model: TheBossLevel123/Llama3-Toxic-8B-Float16
  - model: aifeifei798/llama3-8B-DarkIdol-2.1-Uncensored-1048K
  - model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-b
merge_method: model_stock
base_model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-b
dtype: bfloat16