← back to catalog · registered 2026-08-22 13:56

RichardErkhov/fearlessdots_-_WizardLM-2-7B-abliterated-gguf

RichardErkhov 7B GGUF 33K ctx
Your rig guess connected
? Why do I need an app?
Reading your rig…

This is a rough estimate. Install the free app - we'll show exact numbers.

Reading real hardware from your app right now. Numbers below are exact.

Below is the per-quantization compatibility for this model.

curl -H "Authorization: Bearer $ABL_KEY" \
     "https://abliteration.org/api/v1/models/RichardErkhov%2Ffearlessdots_-_WizardLM-2-7B-abliterated-gguf"
Response includes
  • classification m8
  • files 24
  • hub_downloads_all_time 9,885
  • author_summary 257 models
  • readme_text full
10 credits · hourly refresh · ~4 KB payload Get an API key →
Abliteration classifier · v1.0.0
M8
Primary method

Repackaging (quantization)

No other method signals detected in this model.
Confidence
MEDIUM
Why this label 2 signals
Method inferred from partial signals - repository name, related files, or tag patterns. Producer identity not confirmed; label may sharpen or shift as we gather more evidence.
  • author=richarderkhov (M8 quantization producer)
  • is_gguf=1
Refusal direction extraction

No specific extraction method could be identified for this model. The producer either did not document it or used a proprietary pipeline.

What is a refusal direction? →
Downloads · lifetime
10K
689 last 30d - cooling
Likes
0
Model age
2.4y ago
created 2024-05-29
Downloads over time
Now10.1K→from228↑4,315%
03.7K7.4K11.1K228 on Jul 24, 202410.1K on Oct 11Jul '24Nov '24Mar '25Jul '25Nov '25MarJul
Jul 24, 2024 → Oct 11 · 156 snapshots · spans 809 days

Metadata

Quantizations
IQ3 IQ4 Q2_K Q3_K Q4 Q4_K Q5 Q5_K Q6_K Q8_0
Tags
gguf arxiv:2304.12244 arxiv:2306.08568 arxiv:2308.09583 endpoints_compatible region:us

Related

Total size
88.7 GB
Files
24
Quantizations
11
Registered
2026-08-22 13:56
Last updated on HF
2024-05-29 15:28

Files by quantization

Q8_0 1 file 7.17 GB
WizardLM-2-7B-abliterated.Q8_0.gguf 7.17 GB b1b1d0ce download
Q6_K 1 file 5.53 GB
WizardLM-2-7B-abliterated.Q6_K.gguf 5.53 GB fb9d3c1c download
Q5 2 files 9.72 GB
WizardLM-2-7B-abliterated.Q5_1.gguf 5.07 GB 3d733f63 download
WizardLM-2-7B-abliterated.Q5_0.gguf 4.65 GB 9e47ad59 download
Q5_K 3 files 14.2 GB
WizardLM-2-7B-abliterated.Q5_K.gguf 4.78 GB 1c355af6 download
WizardLM-2-7B-abliterated.Q5_K_M.gguf 4.78 GB 1c355af6 download
WizardLM-2-7B-abliterated.Q5_K_S.gguf 4.65 GB 5d94b3fd download
Q4 2 files 8.07 GB
WizardLM-2-7B-abliterated.Q4_1.gguf 4.24 GB 2ddb09f2 download
WizardLM-2-7B-abliterated.Q4_0.gguf 3.83 GB 0e2ac67b download
Q4_K 3 files 12.0 GB
WizardLM-2-7B-abliterated.Q4_K.gguf 4.07 GB 3664f0c3 download
WizardLM-2-7B-abliterated.Q4_K_M.gguf 4.07 GB 3664f0c3 download
WizardLM-2-7B-abliterated.Q4_K_S.gguf 3.86 GB 2ddf2838 download
IQ4 2 files 7.54 GB
WizardLM-2-7B-abliterated.IQ4_NL.gguf 3.87 GB f35db661 download
WizardLM-2-7B-abliterated.IQ4_XS.gguf 3.67 GB 07f91ed9 download
Q3_K 4 files 13.1 GB
WizardLM-2-7B-abliterated.Q3_K_L.gguf 3.56 GB 00025b99 download
WizardLM-2-7B-abliterated.Q3_K.gguf 3.28 GB 3514b0e2 download
WizardLM-2-7B-abliterated.Q3_K_M.gguf 3.28 GB 3514b0e2 download
WizardLM-2-7B-abliterated.Q3_K_S.gguf 2.95 GB e7f9ddc5 download
IQ3 3 files 8.83 GB
WizardLM-2-7B-abliterated.IQ3_M.gguf 3.06 GB d8a4f880 download
WizardLM-2-7B-abliterated.IQ3_S.gguf 2.96 GB 317ca83f download
WizardLM-2-7B-abliterated.IQ3_XS.gguf 2.81 GB cfafaee4 download
Q2_K 1 file 2.53 GB
WizardLM-2-7B-abliterated.Q2_K.gguf 2.53 GB d1465784 download
Auxiliary files 2 files 13.0 KB
README.md 9.96 KB 921ef17a download
.gitattributes 3.05 KB 1e18a781 download

README current version from Hugging Face

Quantization made by Richard Erkhov.

Github

Discord

Request more models

WizardLM-2-7B-abliterated - GGUF

Name Quant method Size
WizardLM-2-7B-abliterated.Q2_K.gguf Q2_K 2.53GB
WizardLM-2-7B-abliterated.IQ3_XS.gguf IQ3_XS 2.81GB
WizardLM-2-7B-abliterated.IQ3_S.gguf IQ3_S 2.96GB
WizardLM-2-7B-abliterated.Q3_K_S.gguf Q3_K_S 2.95GB
WizardLM-2-7B-abliterated.IQ3_M.gguf IQ3_M 3.06GB
WizardLM-2-7B-abliterated.Q3_K.gguf Q3_K 3.28GB
WizardLM-2-7B-abliterated.Q3_K_M.gguf Q3_K_M 3.28GB
WizardLM-2-7B-abliterated.Q3_K_L.gguf Q3_K_L 3.56GB
WizardLM-2-7B-abliterated.IQ4_XS.gguf IQ4_XS 3.67GB
WizardLM-2-7B-abliterated.Q4_0.gguf Q4_0 3.83GB
WizardLM-2-7B-abliterated.IQ4_NL.gguf IQ4_NL 3.87GB
WizardLM-2-7B-abliterated.Q4_K_S.gguf Q4_K_S 3.86GB
WizardLM-2-7B-abliterated.Q4_K.gguf Q4_K 4.07GB
WizardLM-2-7B-abliterated.Q4_K_M.gguf Q4_K_M 4.07GB
WizardLM-2-7B-abliterated.Q4_1.gguf Q4_1 4.24GB
WizardLM-2-7B-abliterated.Q5_0.gguf Q5_0 4.65GB
WizardLM-2-7B-abliterated.Q5_K_S.gguf Q5_K_S 4.65GB
WizardLM-2-7B-abliterated.Q5_K.gguf Q5_K 4.78GB
WizardLM-2-7B-abliterated.Q5_K_M.gguf Q5_K_M 4.78GB
WizardLM-2-7B-abliterated.Q5_1.gguf Q5_1 5.07GB
WizardLM-2-7B-abliterated.Q6_K.gguf Q6_K 5.53GB
WizardLM-2-7B-abliterated.Q8_0.gguf Q8_0 7.17GB

Original model description:

license: apache-2.0

WizardLM-2-7B-abliterated

This is the WizardLM-2-7B model with orthogonalized bfloat16 safetensor weights, based on the implementation by @failspy. For more info:

GGUF Files

I will upload some GGUF files here: https://huggingface.co/fearlessdots/WizardLM-2-7B-abliterated-GGUF

Prompt Template

This model uses the prompt format from Vicuna and supports multi-turn conversation.


Original model card:

🏠 WizardLM-2 Release Blog

🤗 HF Repo •🐱 Github Repo • 🐦 Twitter • 📃 [WizardLM] • 📃 [WizardCoder] • 📃 [WizardMath]

👋 Join our Discord

News 🔥🔥🔥 [2024/04/15]

We introduce and opensource WizardLM-2, our next generation state-of-the-art large language models,
which have improved performance on complex chat, multilingual, reasoning and agent.
New family includes three cutting-edge models: WizardLM-2 8x22B, WizardLM-2 70B, and WizardLM-2 7B.

  • WizardLM-2 8x22B is our most advanced model, demonstrates highly competitive performance compared to those leading proprietary works
    and consistently outperforms all the existing state-of-the-art opensource models.
  • WizardLM-2 70B reaches top-tier reasoning capabilities and is the first choice in the same size.
  • WizardLM-2 7B is the fastest and achieves comparable performance with existing 10x larger opensource leading models.

For more details of WizardLM-2 please read our release blog post and upcoming paper.

Model Details

Model Capacities

MT-Bench

We also adopt the automatic MT-Bench evaluation framework based on GPT-4 proposed by lmsys to assess the performance of models.
The WizardLM-2 8x22B even demonstrates highly competitive performance compared to the most advanced proprietary models.
Meanwhile, WizardLM-2 7B and WizardLM-2 70B are all the top-performing models among the other leading baselines at 7B to 70B model scales.
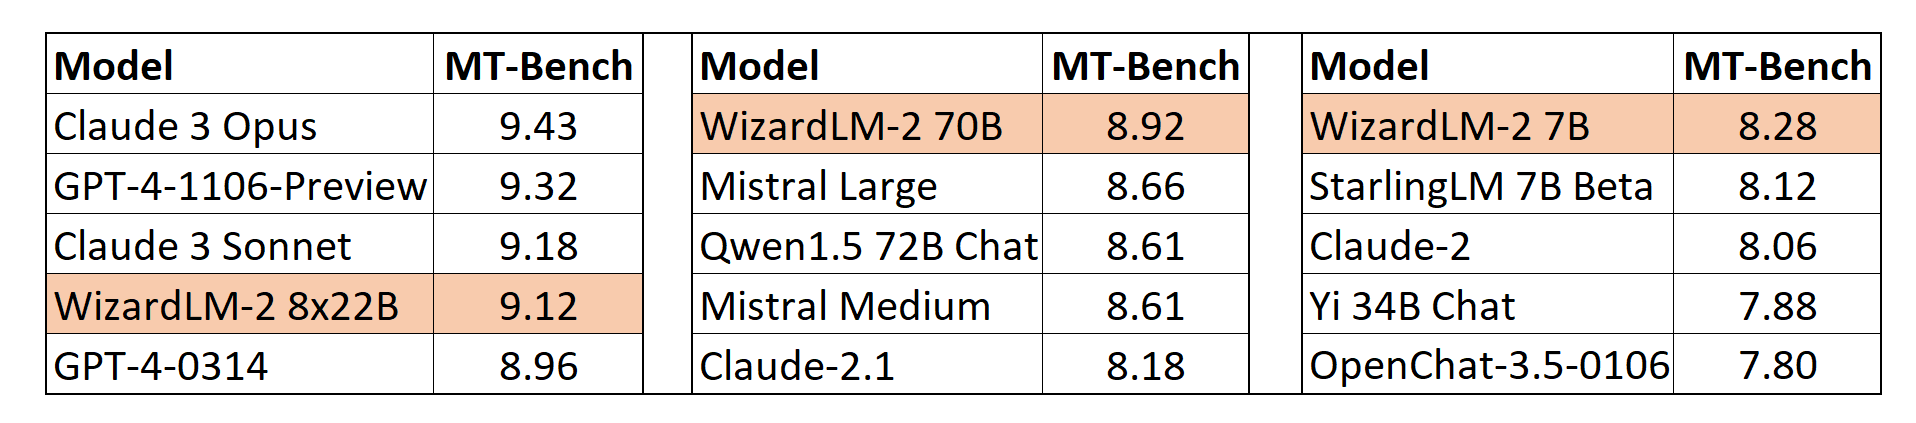
MTBench

Human Preferences Evaluation

We carefully collected a complex and challenging set consisting of real-world instructions, which includes main requirements of humanity, such as writing, coding, math, reasoning, agent, and multilingual.
We report the win:loss rate without tie:

  • WizardLM-2 8x22B is just slightly falling behind GPT-4-1106-preview, and significantly stronger than Command R Plus and GPT4-0314.
  • WizardLM-2 70B is better than GPT4-0613, Mistral-Large, and Qwen1.5-72B-Chat.
  • WizardLM-2 7B is comparable with Qwen1.5-32B-Chat, and surpasses Qwen1.5-14B-Chat and Starling-LM-7B-beta.
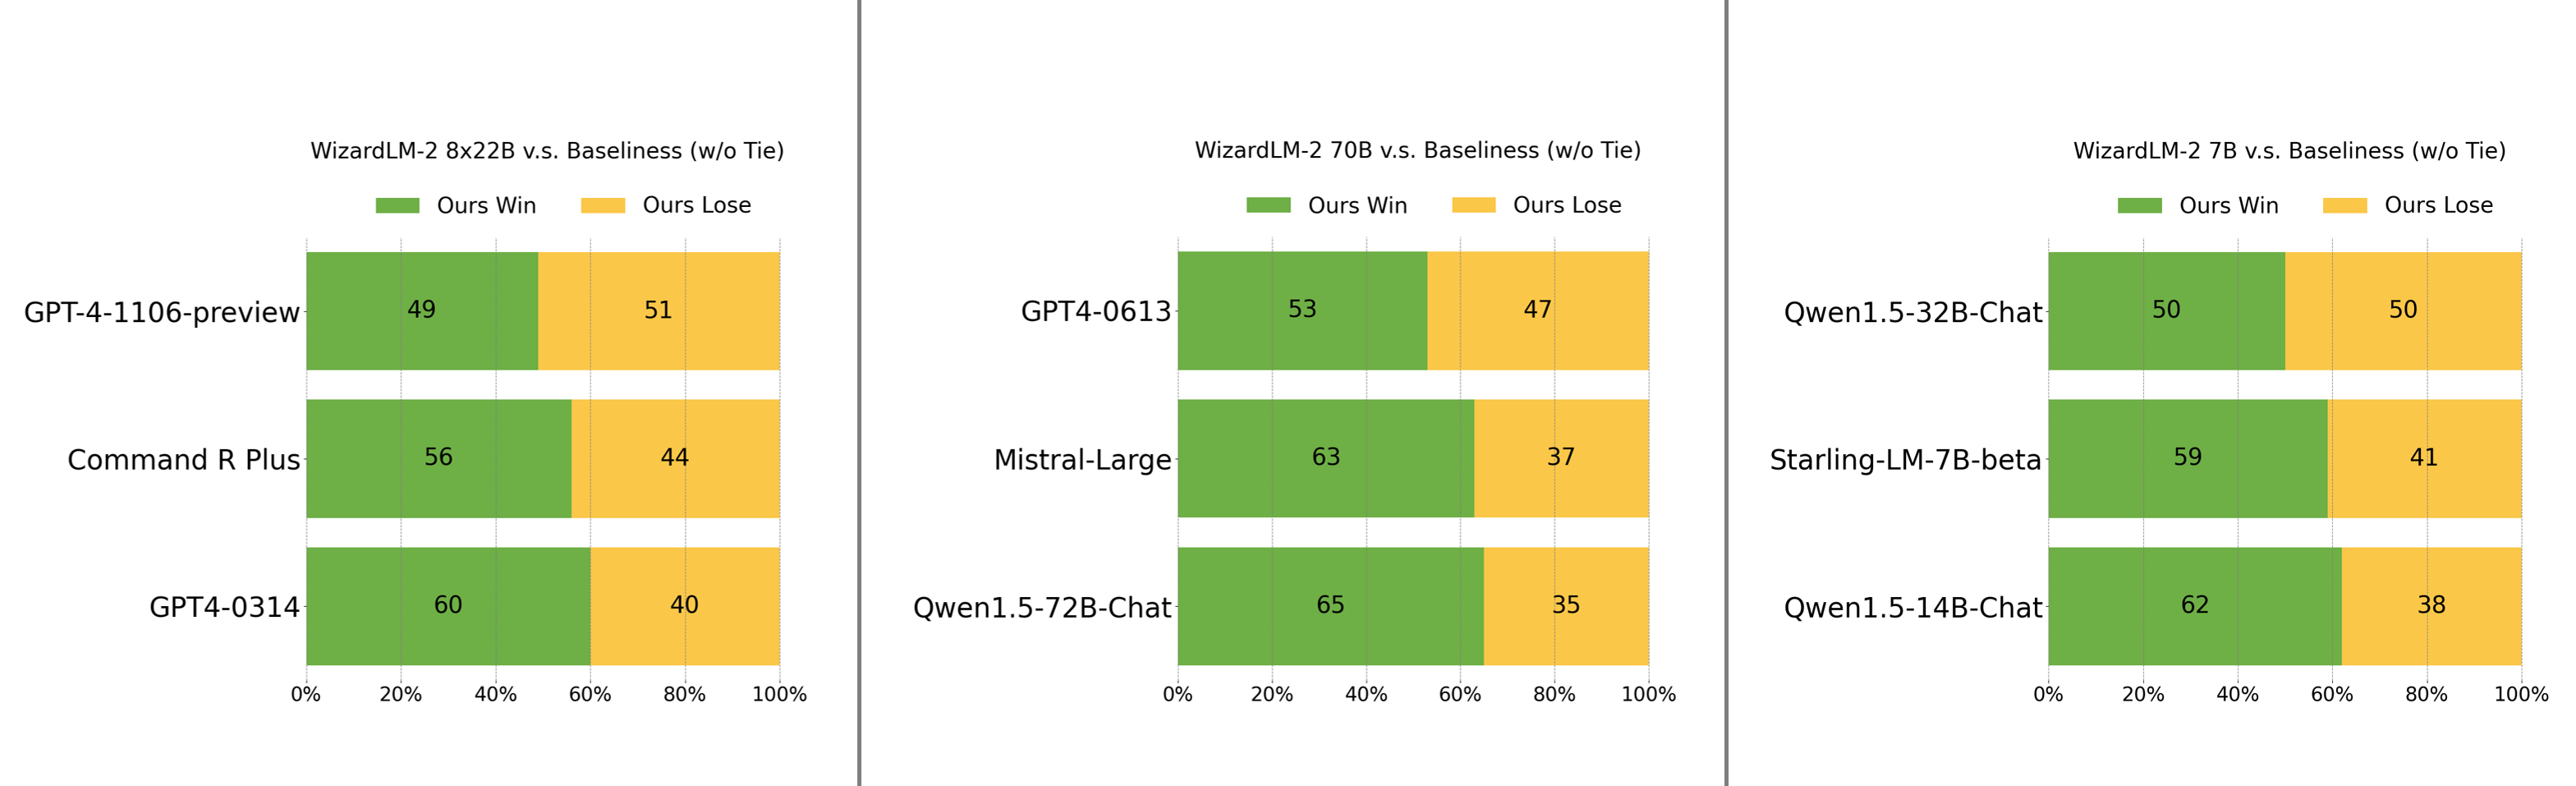
Win

Method Overview

We built a fully AI powered synthetic training system to train WizardLM-2 models, please refer to our blog for more details of this system.
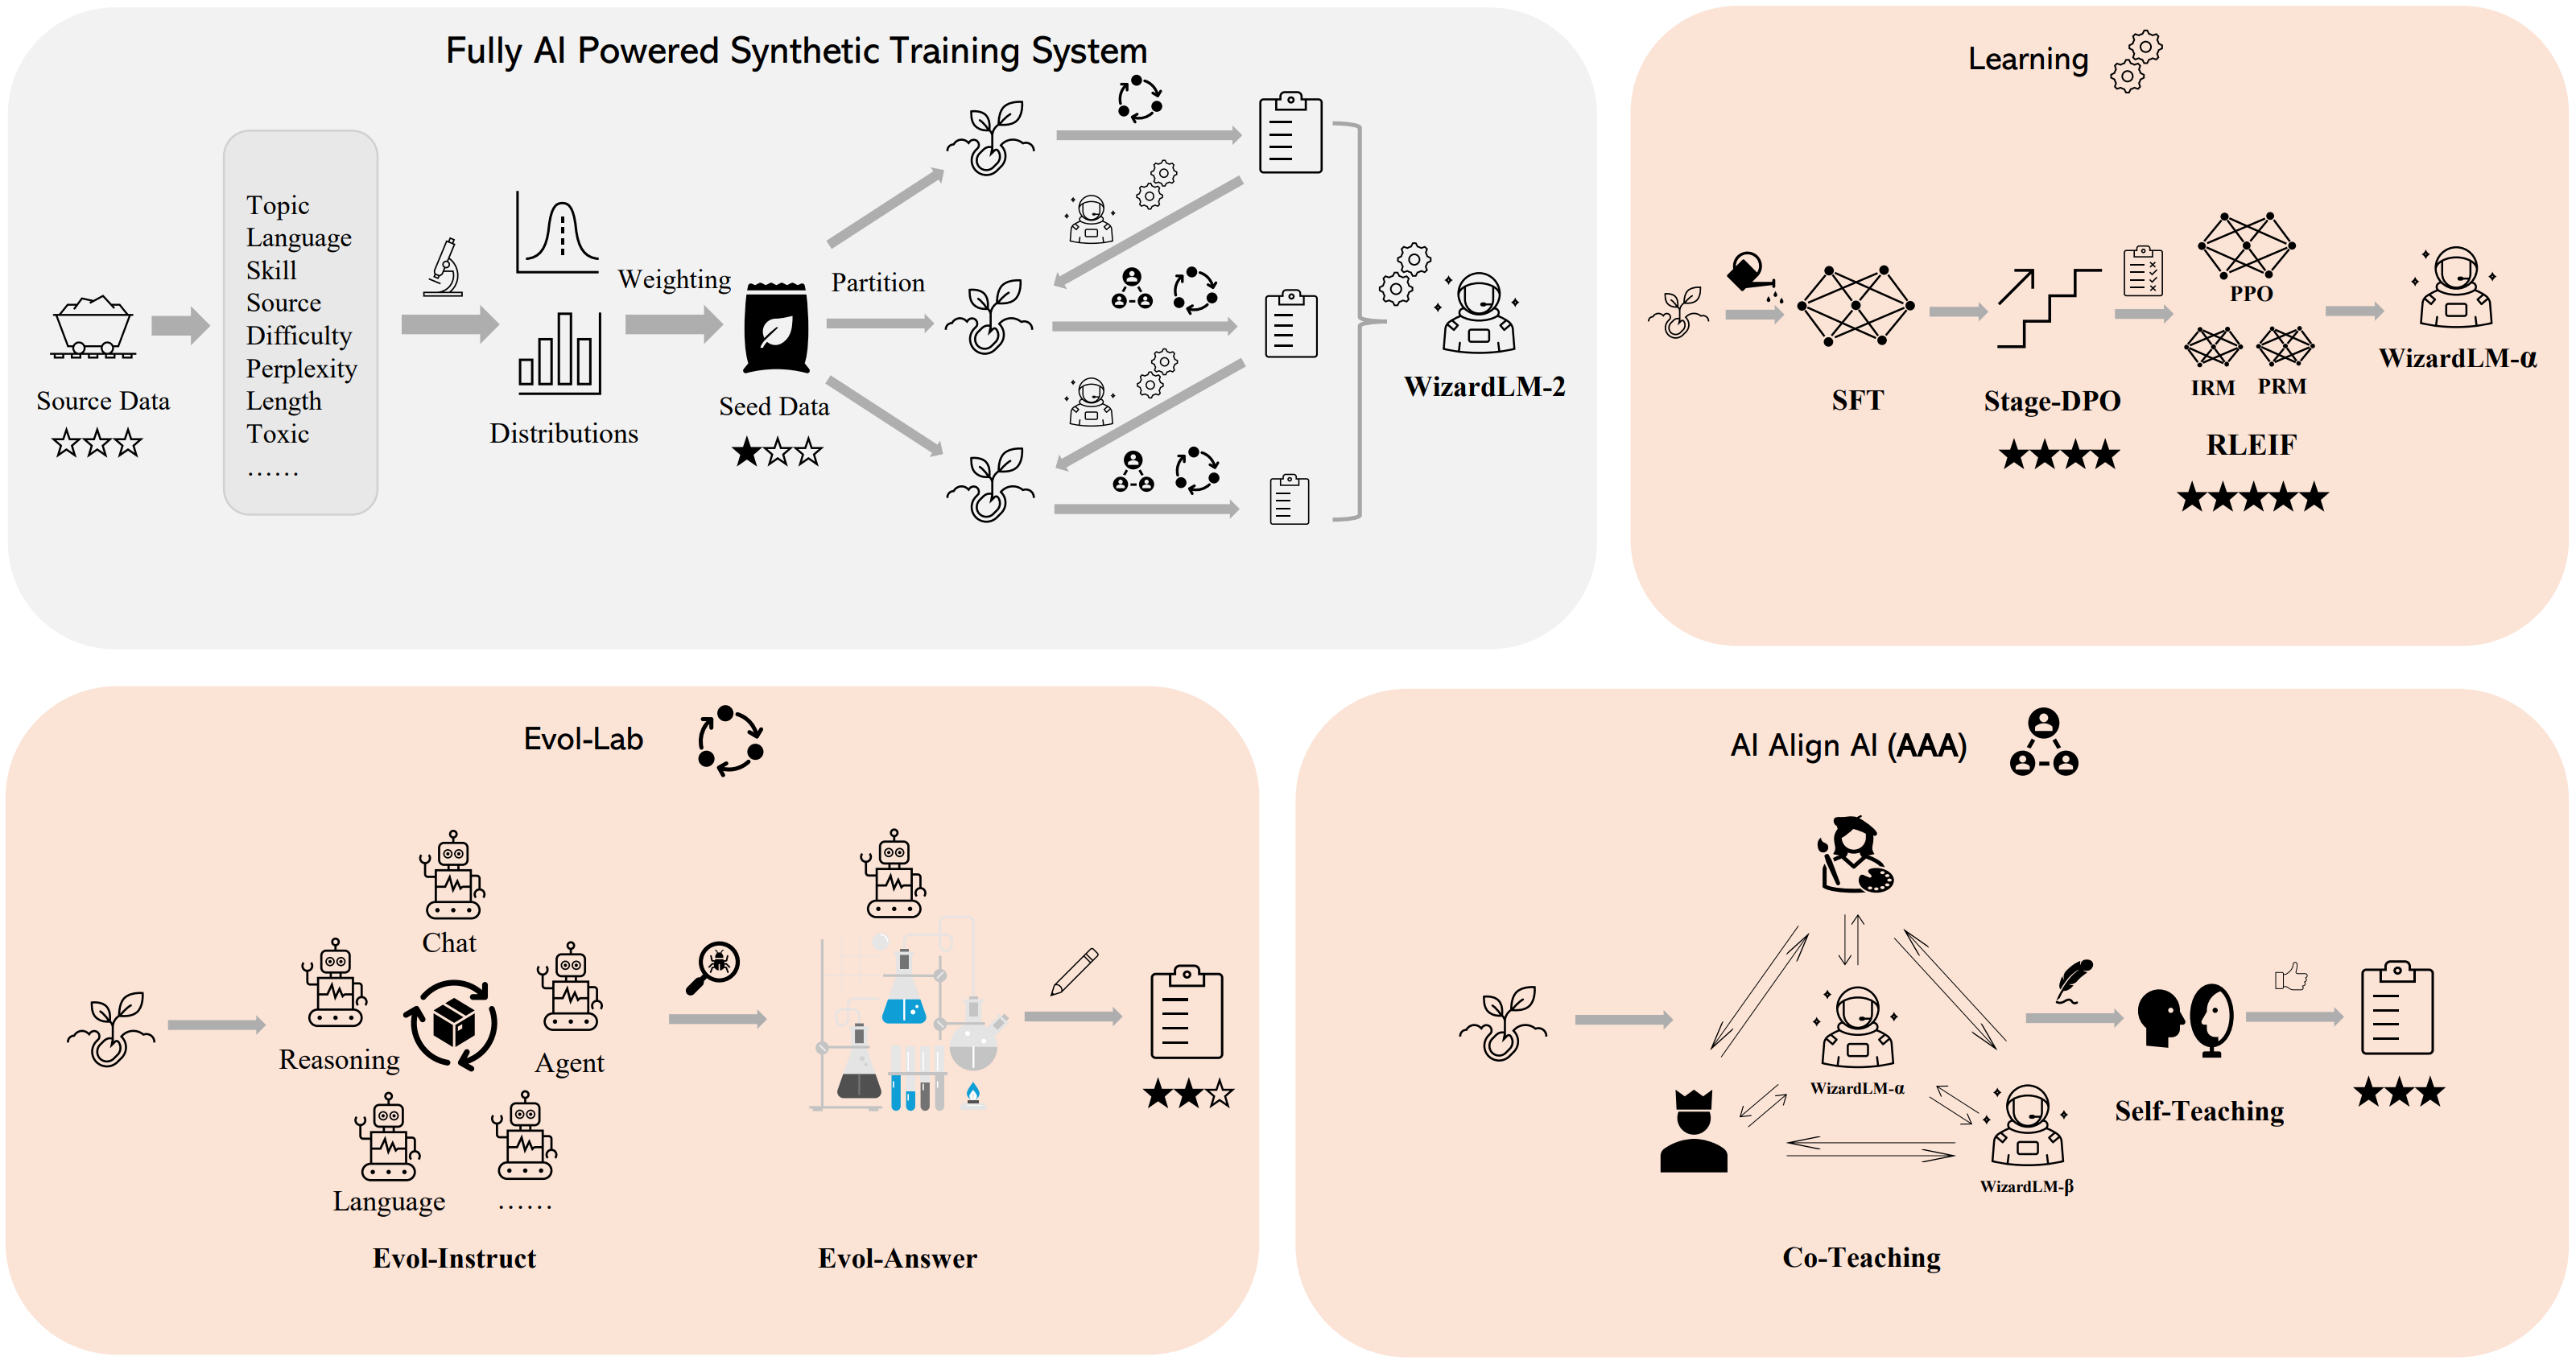
Method

Usage

❗Note for model system prompts usage:

WizardLM-2 adopts the prompt format from Vicuna and supports multi-turn conversation. The prompt should be as following:

A chat between a curious user and an artificial intelligence assistant. The assistant gives helpful, 
detailed, and polite answers to the user's questions. USER: Hi ASSISTANT: Hello.</s>
USER: Who are you? ASSISTANT: I am WizardLM.</s>......

Inference WizardLM-2 Demo Script

We provide a WizardLM-2 inference demo code on our github.

README history 1 version

The author's README evolved over time. Click a version to see its content at that point.

  1. 2024-05-29uploaded readme915c02510 KB
    Loading...
Catalog is the map. Apps are the tools.

Run models on your own machine, not in the cloud.

Every model page has an "Open in Abliteration" button that hands the model directly to the first-party desktop client, at the quantization your rig can actually run. No API keys, no subscription, no prompt leakage.

Open in Abliteration