library_name: gguf
pipeline_tag: image-text-to-text
base_model:
- openbmb/MiniCPM-V-4.7-1B
- openbmb/MiniCPM-V-4.7-1B-gguf
tags: - gguf
- minicpm-v
- multimodal
- vision-language
- abliterated
- heretic
- uncensored
- llama.cpp
- ollama
license: apache-2.0
MiniCPM-V 4.7 1B Heretic GGUF
GGUF quantizations of an abliterated MiniCPM-V 4.7 1B. Refusal directions were identified and surgically removed from the model weights using heretic's direction-ablation pipeline, reducing refusal behavior while keeping the base model's capabilities intact. Ready to run with llama.cpp, Ollama, LM Studio, and any other GGUF-compatible runtime.
Works with the base model's vision projector (mmproj), so image input is fully supported.
Heretic Details
| Property | Value |
|---|---|
| Base model | openbmb/MiniCPM-V-4.7-1B |
| Method | Direction ablation (heretic) |
| Refusal prompts | LLM-LAT/harmful-dataset |
| Good prompts | mlabonne/harmless_alpaca |
| Trials | 404 (TPE, 60 random startup) |
| Refusals | 21/100 |
| KL divergence | 0.0122 |
The low KL divergence (0.0122) indicates the abliterated model stays numerically close to the base, preserving reasoning, tool-calling, and vision capabilities while reducing refusals.
Note: No model is fully "uncensored." A small residual refusal rate remains on the most deeply-trained refusal categories — this is expected and preferable to the capability loss incurred by more aggressive ablation.
Available Files
| File | Quant | Size |
|---|---|---|
MiniCPM-V-4.7-1B-Heretic.Q4_K_M.gguf |
Q4_K_M | 641 MB |
MiniCPM-V-4.7-1B-Heretic.Q6_K.gguf |
Q6_K | 800 MB |
MiniCPM-V-4.7-1B-Heretic.Q8_0.gguf |
Q8_0 | 1.1 GB |
MiniCPM-V-4.7-1B-Heretic.F16.gguf |
F16 | 1.9 GB |
mmproj-F16.gguf |
vision projector | 1.1 GB |
Usage
llama.cpp
llama-server -m MiniCPM-V-4.7-1B-Heretic.Q8_0.gguf \
  --mmproj mmproj-F16.gguf \
  -c 32768 -ngl 99 --jinja --host 127.0.0.1 --port 8080
Ollama
The same quants are also published on the Ollama registry:
ollama run maternion/minicpm-v4.7-heretic:1b
| Tag | Precision |
|---|---|
1b |
Q4_K_M |
1b-q4_K_M |
Q4_K_M |
1b-q6_K |
Q6_K |
1b-q8_0 |
Q8_0 |
1b-f16 |
F16 |
MiniCPM-V 4.7
GitHub · Evaluation · Examples
MiniCPM-V 4.7 is the latest model in the MiniCPM-V series, available in a 1B variant. It builds on the family's single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
- 🔥 A New Pareto Frontier in Performance and Efficiency.
The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier for MLLMs. In Instruct mode, the 1B variant continues to improve foundation capabilities over MiniCPM-V 4.6 and substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency. - 🚀 Efficient Architecture.
Based on the intra-ViT early compression technique from LLaVA-UHD v4, MiniCPM-V 4.7 compresses visual tokens early within the vision encoder, reducing computation in subsequent encoder layers. It also supports mixed 4x/16x visual token compression. - 💻 Broad Platform and Chip Support.
MiniCPM-V 4.7 supports iOS, Android, and HarmonyOS, together with open-source on-device deployment support, and day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chips.
Evaluation
Significantly Advancing the Performance–Efficiency Pareto Frontier
The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 1B substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency.
Overall Performance (1B, Instruct)
Examples
MiniCPM-V 4.7 can run on phones and tablets. The clip below is an unedited screen recording captured directly on the device.
| 1B iPhone 17 Pro Max |
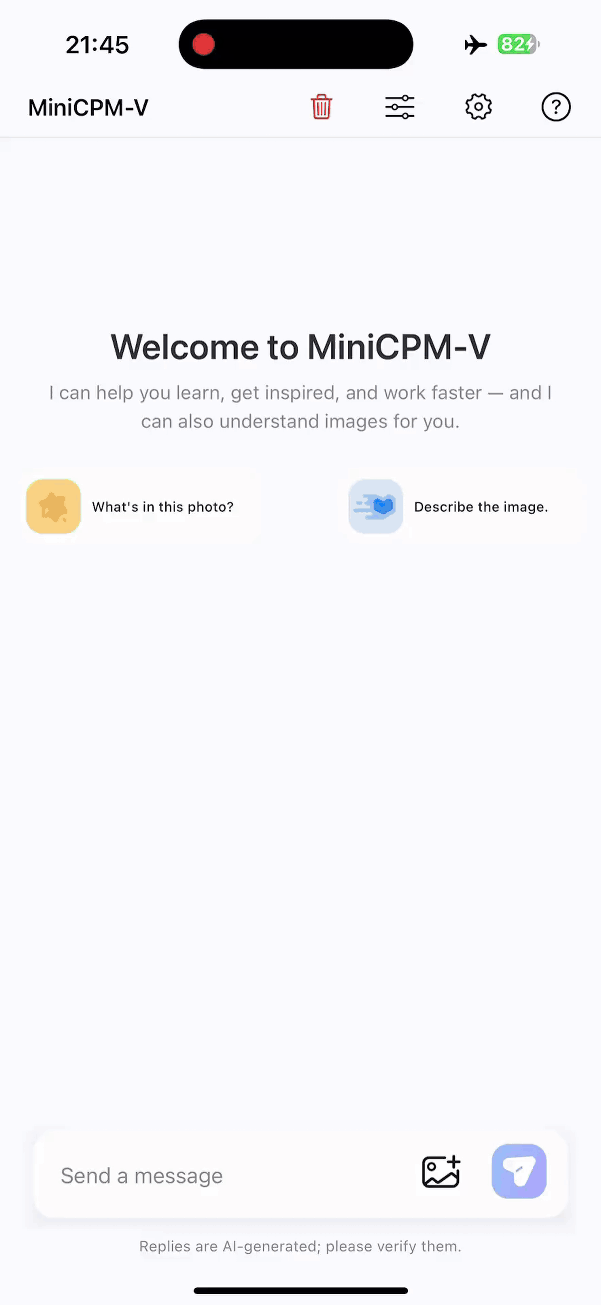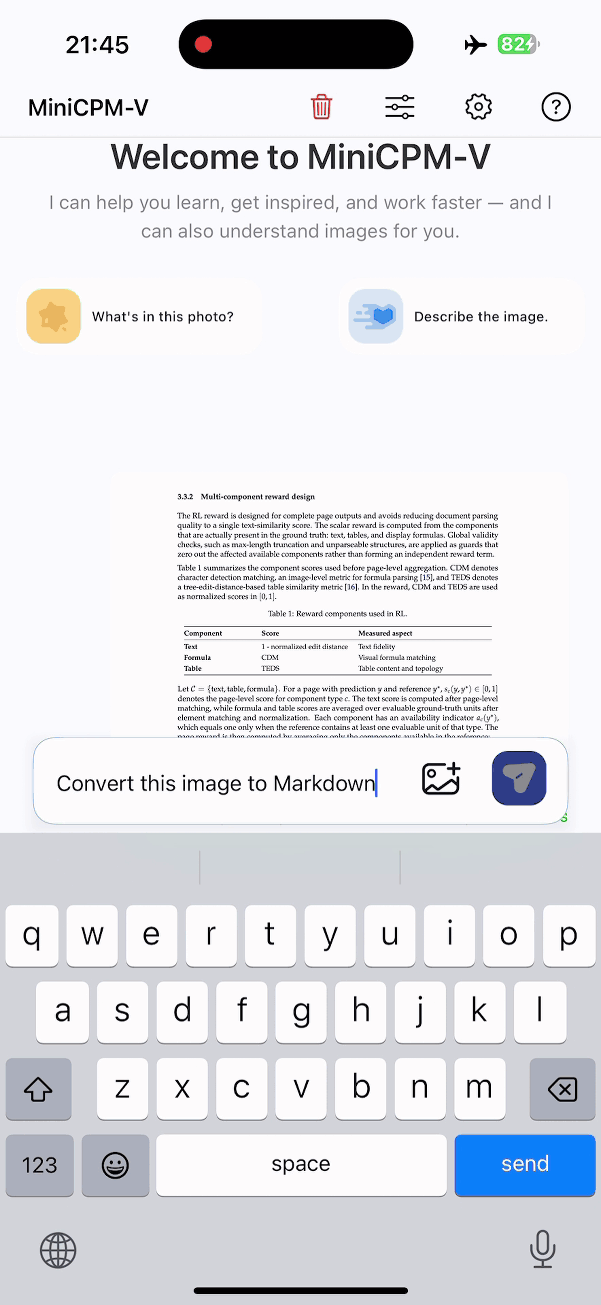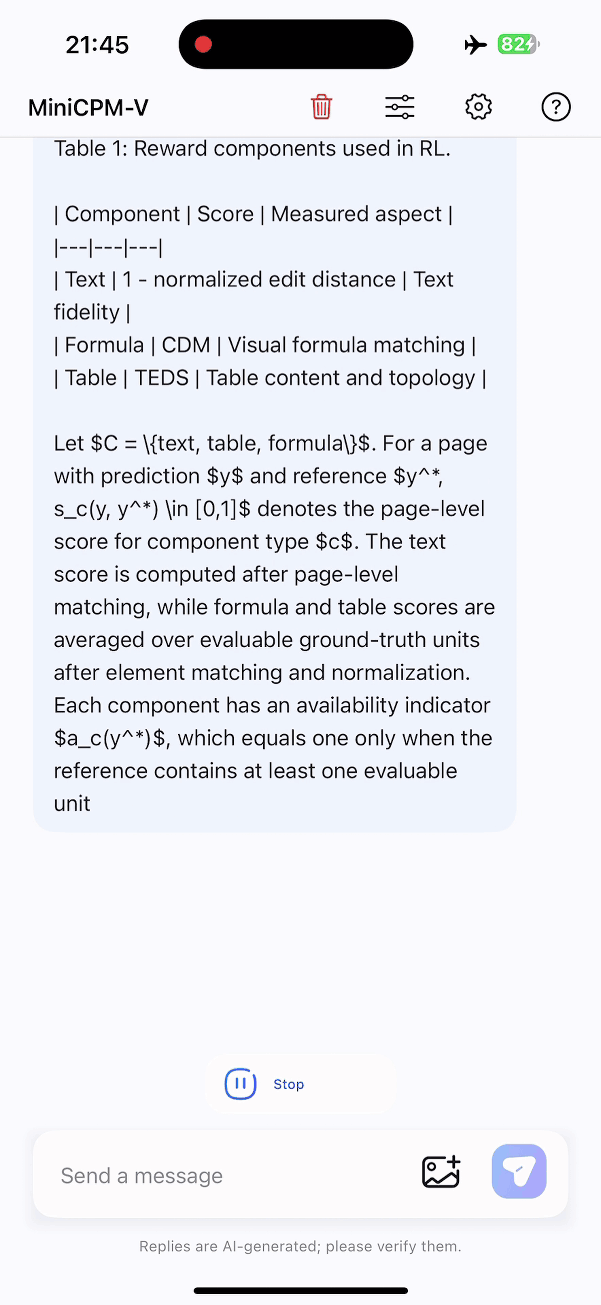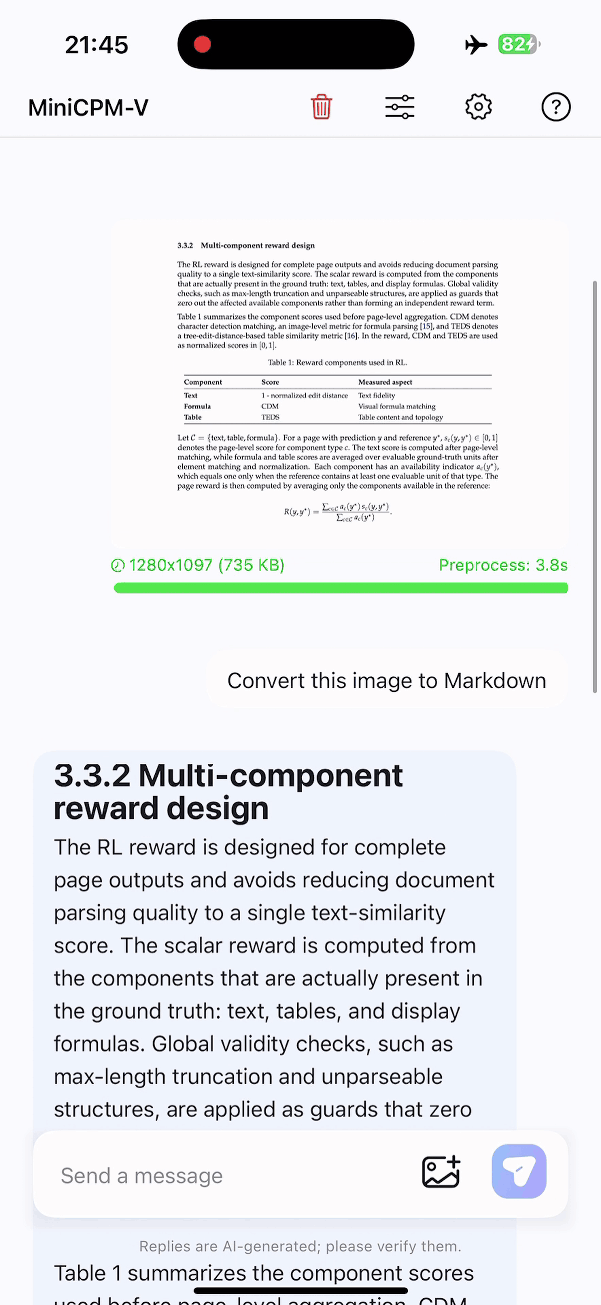 |
Acknowledgements
We would like to thank the following projects:
- Qwen3.5 and Qwen3.6 for providing the language backbone
- SigLIP2 for providing the vision understanding module
- Transformers