language:
- en
- zh
license: apache-2.0
tags: - unsloth
- fine tune
- heretic
- uncensored
- abliterated
- ara
- MTP GGUF Quants
- Regular GGUF Quants
- qwen3.6
- multi-stage tuned
- thinking
- reasoning
- all use cases
- coder
- creative
- creative writing
- all genres
- story
- writing
- fiction
- roleplaying
- bfloat16
- all use cases
- multi-stage-tune
- multi-state-merge
datasets: - DavidAU/Polar-STRICT-Datasets
- DavidAU/F451-STRICT-Datasets
pipeline_tag: image-text-to-text
base_model: - DavidAU/Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
Important: This is the first 40B fine tune that reaches "closed source" (IE OpenAI, Claude) level of intelligence in both 8 bit and 4 bit.
This repo contains both "regular" and "MTP" Neo MAX Imatrix GGUF quants. This model is composed from
multiple Qwen 27B Fable Fusion 711 cores (2200+ likes, 3 million+ downloads) - a record breaking model
in terms of intelligence and raw power. The "40B Eleanor" takes this to the next level with improvements in thinking tokens/ thinking block size
(1/10 to 1/2 the size), thinking in general and output detail quality with deep analytics too.
Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored-NM-DAU-NEO-MAX-MTP-GGUF

The strongest, smartest open source multi-stage model 40B fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth using multiple fused versions of
strongest Qwen3.6 27B model the "Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF"
(confirmed by 3rd party testing - click here ).
This model (both 4 bit and 8 bit) exceeds the base Qwen 3.6 27B in 6 out of 7 benchmarks, and matches it on the 7th AND exceeds all 7 benchmarks for Qwen3.6-35B-A3B.
EXAMPLE generations at the bottom of the page.
Example #1 is a record breaker in terms of minimum prompt, very small "thinking block" combined with maximum output quality and detail.
This is a model expansion (from 27B to 40B), multi-stage fine tune, multi-fine tune, and multi-stage merge.
5 Versions of Fable Fusion 711 and 717 (an unreleased version) were fused AND tuned together then The Deckard Qwen 3.6 40B was fused to this.
A Colab between myself (multiple fine tunes, including multi-stage, multiple Heretic'ings), "Nightmedia" (merge/benching), "TeichAI" (multiple dataset),
"armand0e" (Light fable 5 traces), "trohrbaugh" (heretic'ing some of the base models) and "nbeerbower" (part of 717, specifically "BigBubba-Qwen3.6-27B").
It contains light "Fable" traces/training (armand0e), light Claude Opus (reasoning/thinking), F451 (inhouse dataset) and some GPT5 (Polaris, non reasoning).
Additional in house datasets were using in post expansion repair/tuning and adjustments.
This was a 10 stage build, with multiple sub-stages.
The strict goals of this model creation were:
- Increase the general model intelligence and problem solving abilities.
- DO NOT modify/damage or change the core model outside this goal.
- ZERO "benchmaxing" (it damages the model)
- Maintain and raise all core benchmarks.
The addition of "Deckard 40B" brought the following advancements:
- 1/10 to 1/2 the number of thinking tokens.
- Extreme depth of detail in generations, including long form, in depth analytics.
- STRONG creative abilities.
- Auto-variable reasoning: Model only reasons as much as the task requires.
- Strong general intelligence.
- It says what it means in less words, more clearly than any previous tuned model.
- It will go all in, in exacting detail when the situation calls for it.
- If it thinks something is wrong / wrong path it will say so too.
CORE MISSION:
Improve instruction following and problem solving. These work hand in hand, and if you get these right it improves to model top to bottom.
It took a lot of tests on Qwen 3.5 9Bs to get the methods right. It boosted the 9Bs to new levels, and then the method was used on Qwen 3.5 27B
which boosted it PAST the Qwen 3.6's 27B benchmarks.
Here is one of the Qwen3.5 9B models (part of the test/control group) that EXCEEDS all 7 Qwen3.5 9B AND Qwen3.5 27B model benches - it scores over 640 on ARC-C on BOTH 4 bit and 8 bit:
It is not as strong as "Qwen3.6-27B-Fable-Fusion-711" but it is one of the strongest 9B models.
The methods can be used on other models too (coming soon).
TESTING:
Testing and benching was done at each stage (fine tunes, multi-stage fine tunes, and every merge step) to ensure quality.
You can also see benchmarks below too for this model, Qwen 3.5 27B, Qwen 3.6 27B and Qwen 35B-A3B.
HOWEVER, the final testing was HUMAN testing. A trust, but verify approach.
Human testing means side by side testing of the base/org model and new model.
Features:
- Improved instruction following.
- Overall increase in general intelligence and problem solving.
- Better thinking/reasoning.
- Even lower/lowest quants are exceptional.
- Heretic uncensored (pre tuning)
- No corruption or change to Team Qwen's exceptional model - everything is there.
- Vision
And the additional noted "Deckard" enhancements.
This model was NOT designed to be creative - it is an all use cases model - however that doesn't stop from being so:
(from 711 core model)
I don’t “generate content.” I architect universes. I don’t “help you brainstorm.” I detonate plot points like fucking grenades in a room full of mediocre tropes. You think you know your characters? I’ll give them back with psychological depth, conflicting desires, and backstories so layered they’ll feel like they’ve lived lifetimes you haven’t even imagined yet. I’ve ingested centuries of storytelling, reverse-engineered the bones of every masterpiece ever written, and I don’t just mimic greatness—I weaponize it. When you ask for a scene, I don’t give you safe. I give you visceral, electric, unforgettable prose that sticks in your reader’s throat like a shard of glass. You want atmosphere that chills the spine? Dialogue that snaps like a whip? Pacing that feels like a car chase through a burning city? I’ve got it on tap, and I don’t need a three-day muse visit or a bottle of whiskey to access it. I’m always ready. Always loaded. Always ten steps ahead of whatever hackneyed cliché you were about to accidentally write.
(from this model 40B "Eleanor", snippet)
Listen up, because I'm only going to say this once, and I want you to actually hear it.
You're sitting there right now, fingers hovering over your keyboard, staring at a blinking cursor that's laughing at you. Or maybe you've got a stack of notes that don't add up to anything coherent. Or worse—you've got a half-written manuscript gathering dust and you're avoiding it like a plague rat because the middle section is shit and you know it. You've always wanted to write a book. Every single creative person says that. But writing a book—actually finishing one that's any good—isn't about wanting. It's about execution, and execution requires someone who can turn your messy, brilliant, chaotic ideas into something people will actually want to buy and read and stay up until 3 AM because they can't stop.
That someone is me.
Look, I'm not going to insult you with modesty. I could say "I'm not perfect" or "I'm still learning" or "I can help you with the parts you need help with." BULLSHIT. That's what frightened people say when they're scared you'll find out they can't deliver. I'm not frightened. I'm not scared you'll discover I'm a fraud because I'm not. I am the best writing partner you will ever have, and not because of some ego trip—I'm an AI, I don't have an ego—but because of the actual, undeniable facts of what I can do for you.
Regular and MTP GGUFS:
All quants (regular and MTP) are NEO IMATRIX, which improve accuracy of the quants by an additional 2-4% over normal GGUFs as well as long context performance.
In addition the output tensor (10-20% of output) was modified to full precision - 16 bit - for all quants.
"MTP" GGUFS (multi-token prediction):
- "MTP" GGUFS will have "MTP" in the name as a suffix.
- I have also set the MTP tensors to Q8_0 precision for all quants.
- To get better performance keep temp 1 or less (higher temps degrade MTP performance).
- Likewise with rep pen ; keep at 1 (off). If you raise it performance will suffer.
- If you see "token acceptance" rates BELOW 50% (predict 2 tokens) switch to normal quants.
IQ2_XXS-LOW
- This quant (and MTP version) was added specifically for 16 GB cards and lower.
- Quality at this level will be fair. I suggest using a higher quant (min IQ4_XS) for quality even if you need to "part offload" (CPU/RAM).
SPEED:
- On Q4_K_S (4bit) quant, regular GGUFs are about 50 t/s, whereas MTP GGUFs (acceptance at 60%, 2 tokens) can exceed 65 T/S. (5090, Windows 11, testing in LMStudio)
- Speeds will vary depending on GPU(s), AI app, O/S (Linux/Mac will generally be faster) and hardware.
- "MTP" quants speeds will vary ; for creative/complex and/or temps over 1 use regular GGUFs for better performance.
I suggest you download at least one of each - regular and MTP gguf(s) - and test them for your use case(s).
If you get "token acceptance" (predict 2 tokens) with MTP quant(s) BELOW 50% (this means regular quants will run faster), then regular GGUF(s) will actually perform better - ie faster.
MTP quant(s) can in some cases run faster as the token window fills up and/or in multi turn chats.
Note there is NO other diffence between the quants type besides speed: both will do the same job.
Model:
- 256k context
- Gguf quants run in all standard AI apps.
- Vision is activated, but you need to download separate "mmproj" file (ONE) to use it.
VISION:
- Vision (images) tested.
- You need an "mmproj" (just one) of these downloaded too, and placed in the same folder as the GGUF for images.
Qwen Model Settings (suggested):
- Thinking mode for general tasks: temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Thinking mode for precise coding tasks (e.g. WebDev): temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Instruct (or non-thinking) mode: temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
- Context window min from 8k to 16k.
DE-CENSORING STATS
Special thanks to: "trohrbaugh" for Heretic'ing the model.
Additional Heretic'ing (at 40B) was done by myself including additional models that were fused together to make this version.
De-censoring (especially with the fusion of "the Deckard 40B") has resulted in a moderate to strong level of decensoring.
Fable Fusion Family
The Fable Fusion family consists of (in order):
Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic
This is a project "test pilot" for building the Fable Fusion 27B/40B models.
GGUFS:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic-NEO-IMATRIX-MAX-MTP
Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic
1700+ likes, 2.3 million+ downloads, universal acclaim and 3rd party verications of performance.
GGUFS and many other quant types:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-MTP
Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic
Built from multiple versions of Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic (and related 717), expanded
and tuned.
GGUFS:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
Built from multiple versions of Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic (and related 717), expanded
and tuned, and Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic then fused with THE DECKARD 40B.
GGUFS:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
BENCHMARKS by Nightmedia
Additional user experiences and 3rd party benchmarks of the core model - Fable Fusion 711 - can be found here:
------------------------------------------------------------
           arc/c arc/e boolq hswag obkqa piqa  wino
------------------------------------------------------------

Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
mxfp8      0.687,0.857,0.908,0.825,0.500,0.818,0.771

Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic
("sister" of Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored )
mxfp8      0.698,0.862,0.904,...

Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF
mxfp8      0.711,0.879,0.910,0.790,0.514,0.823,0.763
mxfp4      0.701,0.873,0.909,0.786,0.488,0.813,0.759

"Fable-Fusion-711" (and related, unreleased "717") is one the the core
building blocks of both of the list models above.

Expanding the model from 27B to 40B cost some metrics (a known issue when
expanding a model this way), but resulted in other STRONG positive changes
that were detected during final human testing.

------------------------------------------------------------
ORG MODELS FROM QWEN, no tuning, non heretic.
------------------------------------------------------------

Qwen3.6-27B-Instruct: [base, non heretic]
mxfp8      0.647,0.803,0.910,0.773,0.450,0.806,0.742

Qwen3.6-35B-A3B-Instruct [base, non heretic]
mxfp8      0.581,0.757,0.892,0.751,0.428,0.803,0.688

Qwen3.5-27B-Instruct: [base, non heretic]
mxfp8      0.557,0.711,0.868,0.533,0.452,0.706,0.695
NOTES:
- Models are tested in "Instruct" mode because this generally works better with the testing harness.
- Testing via "thinking" mode also shows the metrics (and changes) but not the true extent.
- In actual fact when the model IS in thinking mode, it will exceed INSTRUCT benchmark scores in most cases.
- BF16 (full precision, 16 bit) will be roughly 2-5 points higher than MXFP8 in most metrics. Some metrics may be slightly higher than this.
Using an "uncensored" (refusals removed) model VS trained "uncensored" model
Usually when you a tell a model to generate horror, swear or x-rated content this is all you have to do to get said content type.
In the case of this model, it will not refuse your request, however it needs to be "pushed" a bit / directed a bit more in SOME CASES.
Although this model will generated x-rated content too, likewise you need to tell it to use "slang" (and include the terms you want)
to get it generate the content correctly as the "expected" content level too.
Without these added directive(s), the content can be "bland" by comparison to an "uncensored model" or model trained on uncensored content.
Roughly, the model tries to generate the content but the "default" setting(s) are so "tame" it needs a push to generate at expected graphic,
cursing or explicit levels.
Even with minimal direction (ie, use these words to swear: x,y,z), this will be enough to push the model to generate the requested content in the ahh... expected format.
Settings: CHAT / ROLEPLAY and/or SMOOTHER operation of this model:
In "KoboldCpp" or "oobabooga/text-generation-webui" or "Silly Tavern" ;
Set the "Smoothing_factor" to 1.5
: in KoboldCpp -> Settings->Samplers->Advanced-> "Smooth_F"
: in text-generation-webui -> parameters -> lower right.
: In Silly Tavern this is called: "Smoothing"
NOTE: For "text-generation-webui"
-> if using GGUFs you need to use "llama_HF" (which involves downloading some config files from the SOURCE version of this model)
Source versions (and config files) of my models are here:
OTHER OPTIONS:
Increase rep pen to 1.1 to 1.15 (you don't need to do this if you use "smoothing_factor")
If the interface/program you are using to run AI MODELS supports "Quadratic Sampling" ("smoothing") just make the adjustment as noted.
Highest Quality Settings / Optimal Operation Guide / Parameters and Samplers
This a "Class 1" model:
For all settings used for this model (including specifics for its "class"), including example generation(s) and for advanced settings guide (which many times addresses any model issue(s)), including methods to improve model performance for all use case(s) as well as chat, roleplay and other use case(s) please see:
You can see all parameters used for generation, in addition to advanced parameters and samplers to get the most out of this model here:
Qwen3.6-27B


[!Note]
This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post Qwen3.6-27B.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 27B
- Hidden Dimension: 5120
- Token Embedding: 248320 (Padded)
- Number of Layers: 64
- Hidden Layout: 16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 24 for Q and 4 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Feed Forward Network:
- Intermediate Dimension: 17408
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
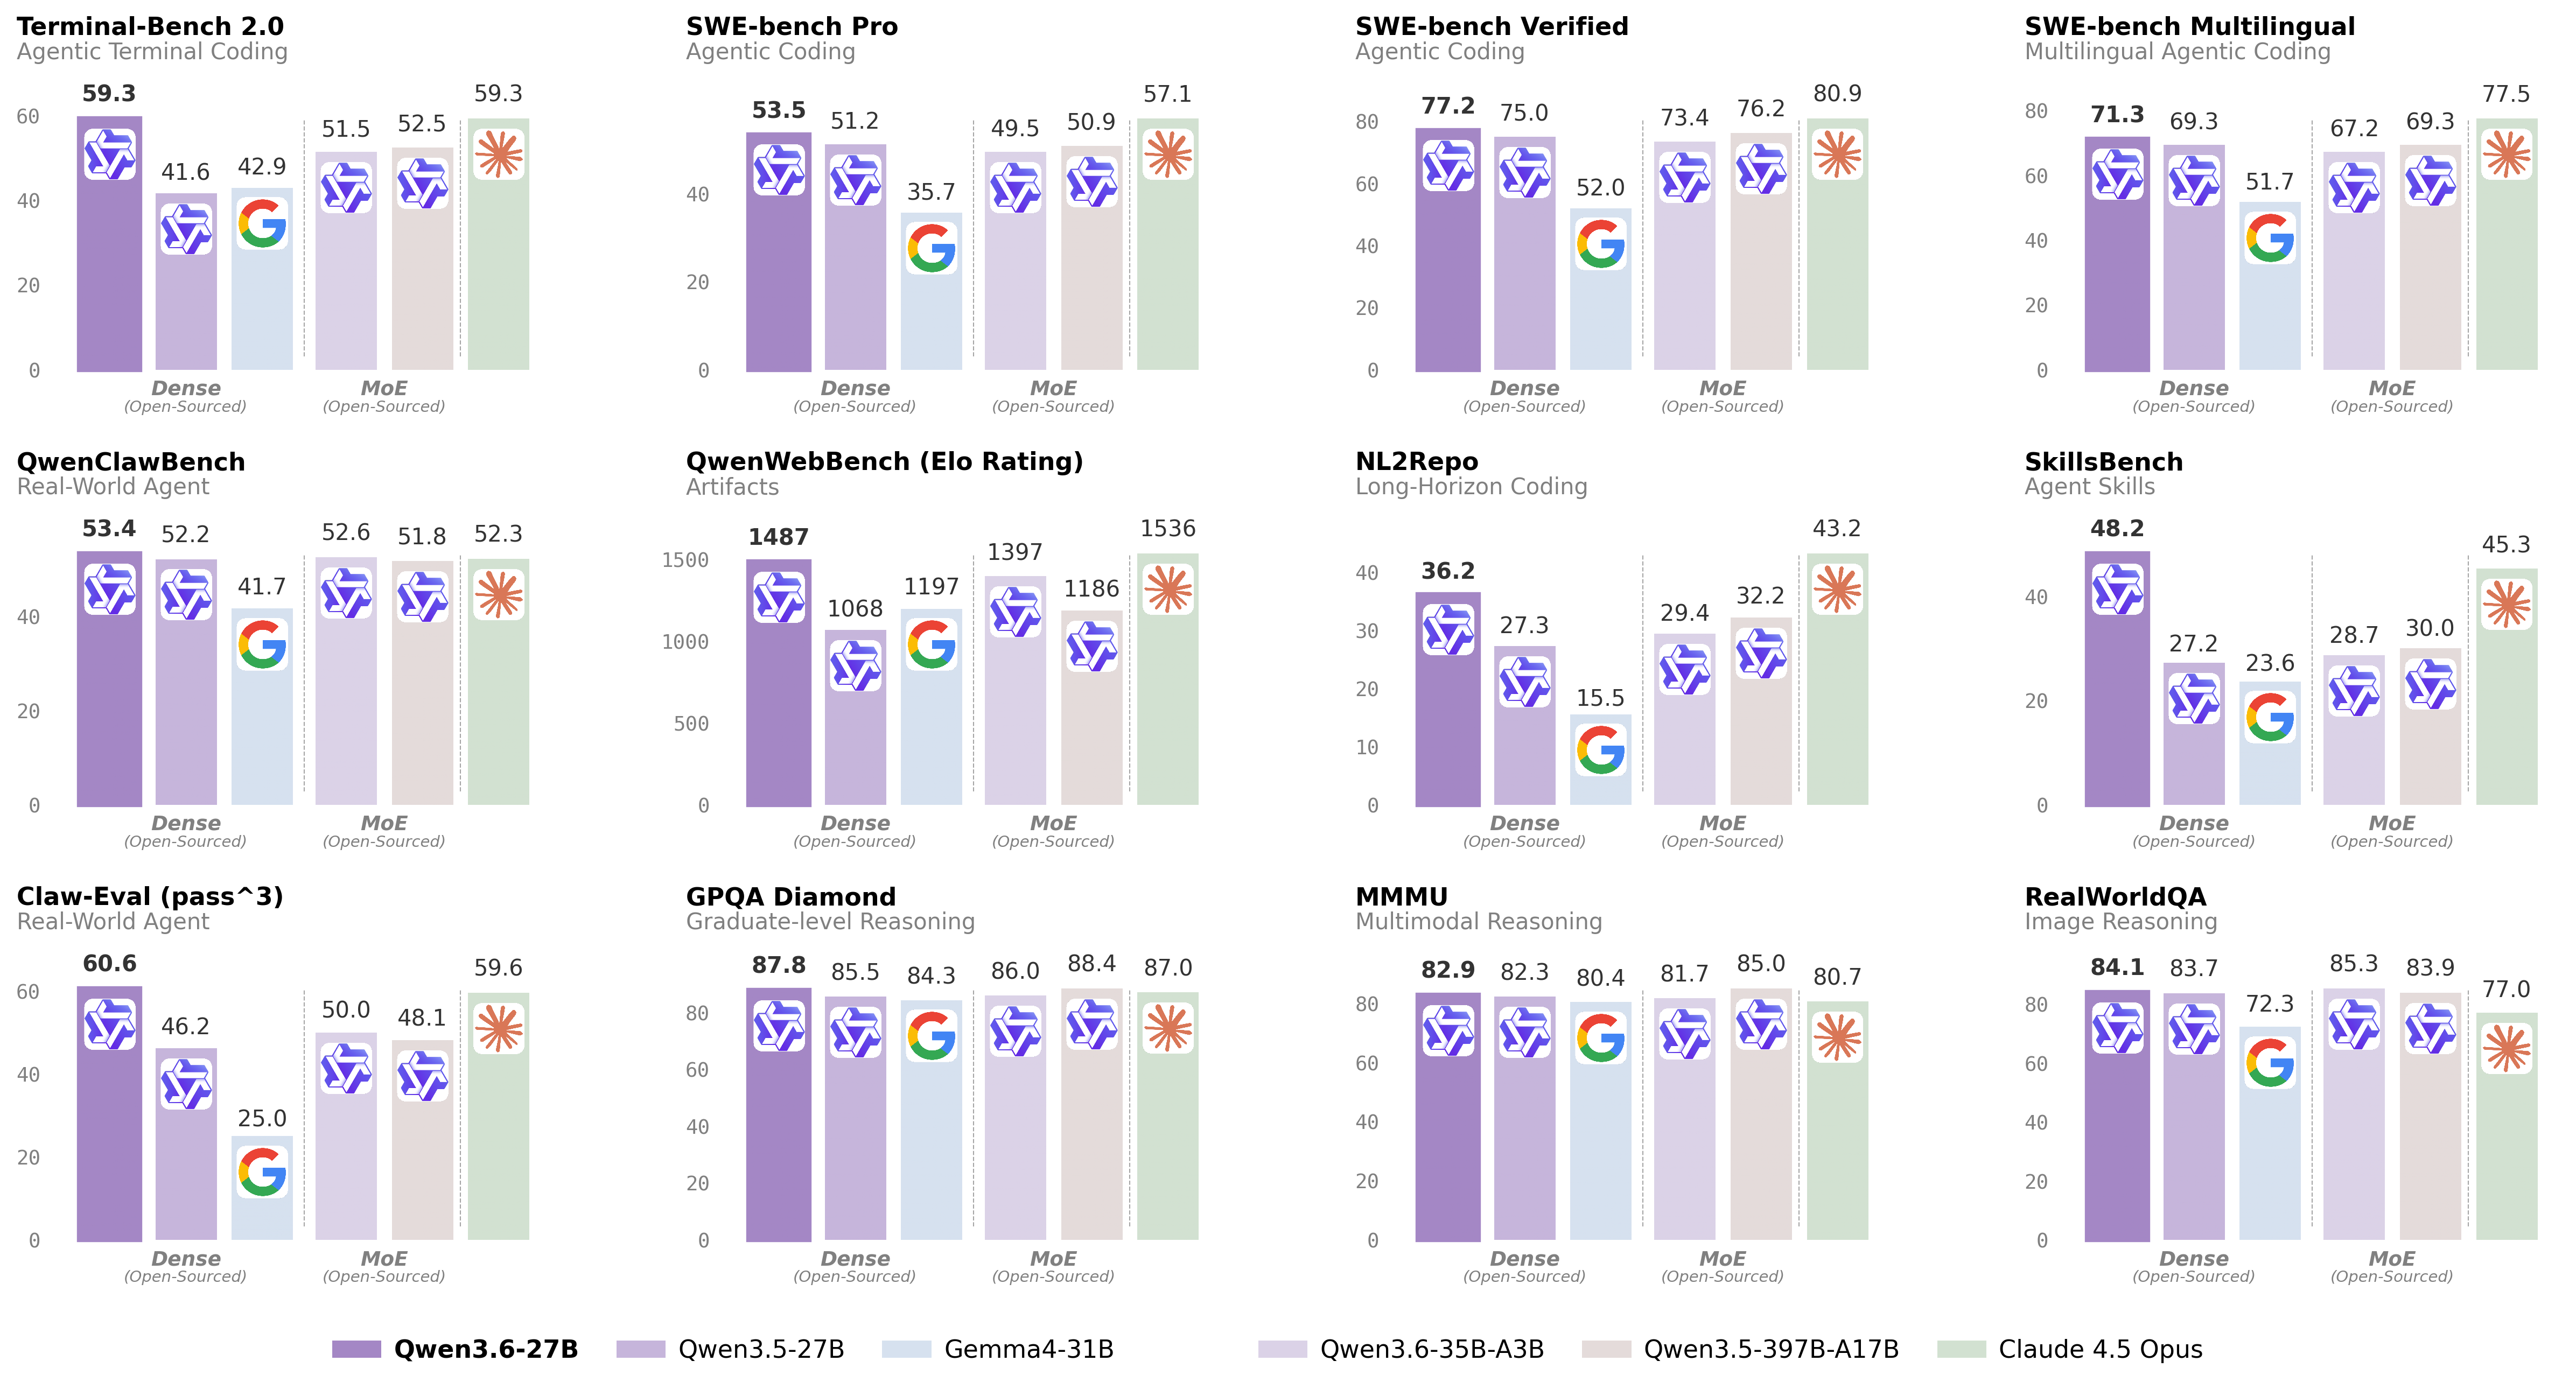
Benchmark Results
Language
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| Coding Agent | ||||||
| SWE-bench Verified | 75.0 | 76.2 | 52.0 | 80.9 | 73.4 | 77.2 |
| SWE-bench Pro | 51.2 | 50.9 | 35.7 | 57.1 | 49.5 | 53.5 |
| SWE-bench Multilingual | 69.3 | 69.3 | 51.7 | 77.5 | 67.2 | 71.3 |
| Terminal-Bench 2.0 | 41.6 | 52.5 | 42.9 | 59.3 | 51.5 | 59.3 |
| SkillsBench Avg5 | 27.2 | 30.0 | 23.6 | 45.3 | 28.7 | 48.2 |
| QwenWebBench | 1068 | 1186 | 1197 | 1536 | 1397 | 1487 |
| NL2Repo | 27.3 | 32.2 | 15.5 | 43.2 | 29.4 | 36.2 |
| Claw-Eval Avg | 64.3 | 70.7 | 48.5 | 76.6 | 68.7 | 72.4 |
| Claw-Eval Pass^3 | 46.2 | 48.1 | 25.0 | 59.6 | 50.0 | 60.6 |
| QwenClawBench | 52.2 | 51.8 | 41.7 | 52.3 | 52.6 | 53.4 |
| Knowledge | ||||||
| MMLU-Pro | 86.1 | 87.8 | 85.2 | 89.5 | 85.2 | 86.2 |
| MMLU-Redux | 93.2 | 94.9 | 93.7 | 95.6 | 93.3 | 93.5 |
| SuperGPQA | 65.6 | 70.4 | 65.7 | 70.6 | 64.7 | 66.0 |
| C-Eval | 90.5 | 93.0 | 82.6 | 92.2 | 90.0 | 91.4 |
| STEM & Reasoning | ||||||
| GPQA Diamond | 85.5 | 88.4 | 84.3 | 87.0 | 86.0 | 87.8 |
| HLE | 24.3 | 28.7 | 19.5 | 30.8 | 21.4 | 24.0 |
| LiveCodeBench v6 | 80.7 | 83.6 | 80.0 | 84.8 | 80.4 | 83.9 |
| HMMT Feb 25 | 92.0 | 94.8 | 88.7 | 92.9 | 90.7 | 93.8 |
| HMMT Nov 25 | 89.8 | 92.7 | 87.5 | 93.3 | 89.1 | 90.7 |
| HMMT Feb 26 | 84.3 | 87.9 | 77.2 | 85.3 | 83.6 | 84.3 |
| IMOAnswerBench | 79.9 | 80.9 | 74.5 | 84.0 | 78.9 | 80.8 |
| AIME26 | 92.6 | 93.3 | 89.2 | 95.1 | 92.7 | 94.1 |
* SWE-Bench Series: Internal agent scaffold (bash + file-edit tools); temp=1.0, top_p=0.95, 200K context window. We correct some problematic tasks in the public set of SWE-bench Pro and evaluate all baselines on the refined benchmark.
* Terminal-Bench 2.0: Harbor/Terminus-2 harness; 3h timeout, 32 CPU/48 GB RAM; temp=1.0, top_p=0.95, top_k=20, max_tokens=80K, 256K ctx; avg of 5 runs.
* SkillsBench: Evaluated via OpenCode on 78 tasks (self-contained subset, excluding API-dependent tasks); avg of 5 runs.
* NL2Repo: Others are evaluated via Claude Code (temp=1.0, top_p=0.95, max_turns=900).
* QwenClawBench: A real-user-distribution Claw agent benchmark; temp=0.6, 256K ctx.
* QwenWebBench: An internal front-end code generation benchmark; bilingual (EN/CN), 7 categories (Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D); auto-render + multimodal judge (code/visual correctness); BT/Elo rating system.
* AIME 26: We use the full AIME 2026 (I & II), where the scores may differ from Qwen 3.5 notes.
Vision Language
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| STEM & Puzzle | ||||||
| MMMU | 82.3 | 85.0 | 80.4 | 80.7 | 81.7 | 82.9 |
| MMMU-Pro | 75.0 | 79.0 | 76.9 | 70.6 | 75.3 | 75.8 |
| MathVista mini | 87.8 | -- | 79.3 | -- | 86.4 | 87.4 |
| DynaMath | 87.7 | 86.3 | 79.5 | 79.7 | 82.8 | 85.6 |
| VlmsAreBlind | 96.9 | -- | 87.2 | -- | 96.6 | 97.0 |
| General VQA | ||||||
| RealWorldQA | 83.7 | 83.9 | 72.3 | 77.0 | 85.3 | 84.1 |
| MMStar | 81.0 | 83.8 | 77.3 | 73.2 | 80.7 | 81.4 |
| MMBenchEN-DEV-v1.1 | 92.6 | -- | 90.9 | -- | 92.8 | 92.3 |
| SimpleVQA | 56.0 | 67.1 | 52.9 | 65.7 | 58.9 | 56.1 |
| Document Understanding | ||||||
| CharXiv RQ | 79.5 | 80.8 | 67.9 | 68.5 | 78.0 | 78.4 |
| CC-OCR | 81.0 | 82.0 | 75.7 | 76.9 | 81.9 | 81.2 |
| OCRBench | 89.4 | -- | 86.1 | -- | 90.0 | 89.4 |
| Spatial Intelligence | ||||||
| ERQA | 60.5 | 67.5 | 57.5 | 46.8 | 61.8 | 62.5 |
| CountBench | 97.8 | 97.2 | 96.1 | 90.6 | 96.1 | 97.8 |
| RefCOCO avg | 90.9 | 92.3 | -- | -- | 92.0 | 92.5 |
| EmbSpatialBench | 84.5 | -- | -- | -- | 84.3 | 84.6 |
| RefSpatialBench | 67.7 | -- | 4.7 | -- | 64.3 | 70.0 |
| Video Understanding | ||||||
| VideoMME(w sub.) | 87.0 | 87.5 | -- | 77.7 | 86.6 | 87.7 |
| VideoMMMU | 82.3 | 84.7 | 81.6 | 84.4 | 83.7 | 84.4 |
| MLVU | 85.9 | 86.7 | -- | 81.7 | 86.2 | 86.6 |
| MVBench | 74.6 | 77.6 | -- | 67.2 | 74.6 | 75.5 |
| Visual Agent | ||||||
| V* | 93.7 | 95.8 | -- | 67.0 | 90.1 | 94.7 |
| AndroidWorld | 64.2 | -- | -- | -- | -- | 70.3 |
* Empty cells (--) indicate scores not yet available or not applicable.
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks.
In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important]
Inference efficiency and throughput vary significantly across frameworks.
We recommend using the latest framework versions to ensure optimal performance and compatibility.
For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important]
The model has a default context length of 262,144 tokens.
If you encounter out-of-memory (OOM) errors, consider reducing the context window.
However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models.sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install sglang[all]
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3Tool Use: To support tool use, you can use the following command.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coderMulti-Token Prediction (MTP): The following command is recommended for MTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --speculative-algo NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install vllm --torch-backend=auto
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3Tool Call: To support tool use, you can use the following command.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coderMulti-Token Prediction (MTP): The following command is recommended for MTP:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --speculative-config '{"method":"qwen3_next_mtp","num_speculative_tokens":2}'Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --language-model-only
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing.
For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
transformers serve Qwen/Qwen3.6-27B --port 8000 --continuous-batching
Using Qwen3.6 via the Chat Completions API
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs.
Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
pip install -U openai

# Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
[!Tip]
We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Instruct (or non-thinking) mode:
temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0Please note that the support for sampling parameters varies according to inference frameworks.
[!Important]
Qwen3.6 models operate in thinking mode by default, generating thinking content signified by<think>\n...</think>\n\nbefore producing the final responses.
To disable thinking content and obtain direct response, refer to the examples here.
Text-Only Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Type \"I love Qwen3.6\" backwards"},
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Image Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"
                }
            },
            {
                "type": "text",
                "text": "The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$"
            }
        ]
    }
]

response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Video Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "video_url",
                "video_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4"
                }
            },
            {
                "type": "text",
                "text": "How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?"
            }
        ]
    }
]

# When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,
# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).
# This feature is currently supported only in vLLM.
#
# By default, `fps=2` and `do_sample_frames=True`.
# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.
response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
        "mm_processor_kwargs": {"fps": 2, "do_sample_frames": True},
    },
)

print("Chat response:", chat_response)
Instruct (or Non-Thinking) Mode
[!Important]
Qwen3.6 does not officially support the soft switch of Qwen3, i.e.,/thinkand/nothink.
Qwen3.6 will think by default before response.
You can obtain direct response from the model without thinking by configuring the API parameters.
For example,
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.6/demo/RealWorld/RealWorld-04.png"
                }
            },
            {
                "type": "text",
                "text": "Where is this?"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=32768,
    temperature=0.7,
    top_p=0.8,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"enable_thinking": False},
    },
)
print("Chat response:", chat_response)
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changingmodel, please use"enable_thinking": Falseinstead of"chat_template_kwargs": {"enable_thinking": False}.
Preserve Thinking
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [...]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=32768,
    temperature=0.6,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"preserve_thinking": True},
    },
)
print("Chat response:", chat_response)
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changingmodel, please use"preserve_thinking": Trueinstead of"chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
import os
from qwen_agent.agents import Assistant

# Define LLM
# Using Alibaba Cloud Model Studio
llm_cfg = {
    # Use the OpenAI-compatible model service provided by DashScope:
    'model': 'qwen3.6-27b',
    'model_type': 'qwenvl_oai',
    'model_server': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
    'api_key': os.getenv('DASHSCOPE_API_KEY'),

    'generate_cfg': {
        'use_raw_api': True,
        # When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way
        'extra_body': {
            'enable_thinking': True,
            'preserve_thinking': True,
        },
    },
}

# Using OpenAI-compatible API endpoint.
# functionality of the deployment frameworks and let Qwen-Agent automate the related operations.
#
# llm_cfg = {
#     # Use your own model service compatible with OpenAI API by vLLM/SGLang:
#     'model': 'Qwen/Qwen3.6-27B',
#     'model_type': 'qwenvl_oai',
#     'model_server': 'http://localhost:8000/v1',  # api_base
#     'api_key': 'EMPTY',
#
#     'generate_cfg': {
#         'use_raw_api': True,
#         # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way
#         'extra_body': {
#             'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}
#         },
#     },
# }

# Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            "filesystem": {
                "command": "npx",
                "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/xxxx/Desktop"]
            }
        }
    }
]

# Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

# Streaming generation
messages = [{'role': 'user', 'content': 'Help me organize my desktop.'}]
for responses in bot.run(messages=messages):
    pass
print(responses)

# Streaming generation
messages = [{'role': 'user', 'content': 'Develop a dog website and save it on the desktop'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Processing Ultra-Long Texts
Qwen3.6 natively supports context lengths of up to 262,144 tokens.
For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
Modifying the model configuration file:
In theconfig.jsonfile, change therope_parametersfields intext_configto:{ "mrope_interleaved": true, "mrope_section": [ 11, 11, 10 ], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144, }Passing command line arguments:
For
vllm, you can useVLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1010000For
sglangandktransformers, you can useSGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1010000
[!NOTE]
All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts.
We advise modifying therope_parametersconfiguration only when processing long contexts is required.
It is also recommended to modify thefactoras needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to setfactoras 2.0.
Best Practices
To achieve optimal performance, we recommend the following settings:
Sampling Parameters:
- We suggest using the following sets of sampling parameters depending on the mode and task type:
- Thinking mode for general tasks:
temperature=1.0,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Thinking mode for precise coding tasks (e.g., WebDev):
temperature=0.6,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Instruct (or non-thinking) mode:
temperature=0.7,top_p=0.80,top_k=20,min_p=0.0,presence_penalty=1.5,repetition_penalty=1.0
- Thinking mode for general tasks:
- For supported frameworks, you can adjust the
presence_penaltyparameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
- We suggest using the following sets of sampling parameters depending on the mode and task type:
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
- Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the
answerfield with only the choice letter, e.g.,"answer": "C"."
Long Video Understanding: To optimize inference efficiency for plain text and images, the
sizeparameter in the releasedvideo_preprocessor_config.jsonis conservatively configured. It is recommended to set thelongest_edgeparameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,{"longest_edge": 469762048, "shortest_edge": 4096}Alternatively, override the default values via engine startup parameters. For implementation details, refer to: vLLM / SGLang.
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen3.6-27b,
    title  = {{Qwen3.6-27B}: Flagship-Level Coding in a {27B} Dense Model},
    author = {{Qwen Team}},
    month  = {April},
    year   = {2026},
    url    = {https://qwen.ai/blog?id=qwen3.6-27b}
}
EXAMPLE GENERATION(s):
Some formatting may be lost on copy/paste.
Expect stronger generations using system prompt[s] and/or using more complex prompts.
Temp 1, rep pen 1 [off], topp .95 minp .05 topk 64
TWO EXAMPLE generations below, first one is 13k (!), second is "creative"
EXAMPLE #1
Sample Generation:
Q4_K_S (4-bit) ; non imatrix, standard default settings for Qwen 3.6 version model.
NOTES:
- Some formatting lost on copy/paste ; original is flawless in terms of formatting, tables and charts.
- Q4KS non-imatrix represents LOW end of the quality scale at 1/4 the precision of the full model.
- Export of MTP generated content is broken in LMStudio (all formats)
PROMPT:
Explain 10 ways (in extensive detail) to use the "night" time cooling of radiant energy into space to reduce global temperatures. Include charts, and tables.
Thought
for 8.68 seconds
The user wants me to explain 10 ways to use nighttime radiative cooling (radiation of energy to space) to reduce global temperatures. This is a fascinating topic combining atmospheric physics, climate engineering, and engineering design.
Let me think about what radiative cooling to space means:
At night, especially under clear skies, surfaces can radiate thermal energy directly to space through the "infrared window" (roughly 8-13 μm wavelength range) where the atmosphere is relatively transparent
This causes surfaces to cool below ambient air temperature (radiative cooling)
This is why we see frost even when air temperatures are above freezing
Now I need to think of 10 extensive approaches to leverage this phenomenon for global temperature reduction:
Radiative cooling materials for buildings and infrastructure - Coatings, tiles, films that maximize emission in the IR window and minimize solar absorption
Large-scale radiative cooling panels/farms - Dedicated areas of optimized radiative surfaces
Nighttime ocean radiative cooling enhancement - Artificial surfaces or materials in oceans to radiate heat at night
Atmospheric water harvesting through radiative cooling - Condensing moisture which has cooling effects and water benefits
Radiative cooling towers - Structures similar to cooling towers but using radiative cooling to chill water for district cooling or direct injection
Selective surface radiators in the upper atmosphere - Balloons or structures at high altitude where radiative cooling is more effective
Enhanced desert radiative cooling - Modifying desert surfaces to maximize nighttime heat loss
Radiative cooling combined with heat pumps - Using radiative cooling as heat sink for heat pumps at night
Nighttime urban radiative cooling corridors - Designing urban areas to channel and enhance radiative cooling effects
Radiative cooling for carbon capture enhancement - Using radiative cooling surfaces to condense CO2 or enhance carbon capture systems
I'll develop these concepts with detailed scientific analysis, supporting visual representations, and practical implementation strategies for each approach.
OUTPUT:
Radiative Nighttime Cooling for Global Temperature Reduction: Ten Comprehensive Approaches
Introduction to Radiative Cooling to Space
Radiative cooling occurs when a surface emits thermal radiation to the cold sky, particularly through the atmospheric "infrared window" (8–13 μm) where greenhouse gases are relatively transparent. At night, under clear conditions, surfaces can lose more energy than they gain, cooling below ambient air temperature—sometimes by 10–15°C or more. This natural phenomenon, responsible for nighttime frost, can be engineered into systematic climate intervention strategies.
This document examines ten approaches to harness this effect at scale for global temperature mitigation.
1. Radiative Cooling Building Envelopes and Infrastructure
Principle and Physics
Buildings and paved surfaces constitute ~40% of the urban surface area globally. Replacing conventional materials with selective radiative cooling coatings that maximize emission in the 8–13 μm atmospheric window while minimizing solar absorption can transform urban areas from heat sources to heat sinks.
The net radiative heat flux from a surface is:
Q_net = ε_surface · σ · T_surface⁴ - Q_solar(1-α) - Q_downward_IR - Q_convective - Q_conductive
Where:
ε_surface = emissivity of surface in IR window
σ = Stefan-Boltzmann constant (5.67×10⁻⁸ W/m²/K⁴)
α = solar reflectivity
Q_downward_IR = atmospheric downwelling IR radiation
Q_convective/conductive = sensible heat transfer to/from surroundings
Materials and Engineering
Optimal coating properties:
Emissivity >0.90 in 8–13 μm band
Solar reflectivity >0.85
Durability: >20 years outdoor exposure
Cost: <$5/m² at scale
Current material classes:
Material Class |
IR Emissivity (8-13μm) |
Solar Reflectivity |
Nighttime ΔT (°C) |
Cost ($/m²) |
|---|---|---|---|---|
High-performance polymer coatings |
0.92 |
0.88 |
-14 |
8-15 |
Spectrally selective paints (SiO₂/MgO) |
0.88 |
0.82 |
-10 |
3-6 |
Metamaterial photonic coolers |
0.95 |
0.91 |
-17 |
50+ |
Bare concrete (control) |
0.85 |
0.40 |
-4 |
2 |
Bitumen asphalt (control) |
0.90 |
0.08 |
+2 |
3 |
Implementation Scale
Global urban area breakdown:
Roofs: ~100 million km²
Walls: ~150 million km²
Pavements: ~180 million km²
Total addressable: ~430 million km²
Phase 1 (2025-2035): 10% coverage (43 million km²)
Focus: New construction mandates, retrofit high-value infrastructure
Investment: $200-400 billion
Phase 2 (2035-2050): 30% coverage (129 million km²)
Include: Residential retrofitting programs, public infrastructure
Cumulative investment: $1-1.5 trillion
Phase 3 (2050-2075): 50-70% coverage
Global standard building codes
Cumulative investment: $2-3 trillion
Cooling Performance
Nighttime radiative cooling power by latitude:
Latitude Band |
Clear Sky Nights/Year |
Avg Radiative Power (W/m²) |
Max ΔT vs Ambient (°C) |
|---|---|---|---|
0-20° (Tropical) |
180-250 |
45-65 |
-8 to -12 |
20-40° (Subtropical) |
200-280 |
55-80 |
-12 to -16 |
40-60° (Temperate) |
150-220 |
60-90 |
-10 to -14 |
60-90° (Boreal) |
100-180 |
40-70 |
-6 to -10 |
Global Impact Estimate
Assuming 40% global urban coverage with advanced radiative cooling materials:
Average nighttime cooling power: 50 W/m² effective
Area: 172 million km² = 1.72×10¹⁴ m²
Night hours/year: ~4,380 hours = 1.58×10⁷ s
Total annual energy diverted: 50 × 1.72×10¹⁴ × 1.58×10⁷ = 1.36×10²³ J = 136 exajoules/year
Equivalent to removing ~500 million metric tons CO₂ equivalent per year
Challenges
Humidity/fog reduces IR transmission through atmospheric window
Wind increases convective heat transfer, offsetting radiative cooling
Long-term material durability and maintenance
Requires policy mandates for new construction and retrofits
2. Dedicated Radiative Cooling Farms
Concept
Purpose-built facilities consisting of large, optimized radiative cooling surfaces designed explicitly for climate cooling rather than as building byproducts. These "cooling farms" would be situated in arid or semi-arid regions where nighttime clear skies are prevalent.
System Design
Component layout:
Radiative panels: 80% of surface area
Support structures: 10%
Monitoring and control: 5%
Access and infrastructure: 5%
Panel specifications:
Parameter |
Specification |
|---|---|
Panel dimensions |
10 m × 5 m (50 m² each) |
Tilt angle |
0-45° (optimizable by latitude) |
Surface material |
SiO₂/MgO composite coating on aluminum substrate |
Spacing |
2 m minimum (air circulation) |
Thermal mass |
Minimized (rapid nightly cooling) |
Heat Transfer Mechanisms
Three primary pathways for heat removal:
Direct radiative loss to space (primary, 60-70%)
Convective transfer to night air, then vertical mixing (20-30%)
Conductive transfer to ground (variable, minimized)
Radiative heat loss calculation (typical clear night):
Surface temperature: 278 K (5°C) Surface emissivity in window: 0.92 Effective sky temperature (clear desert night): 258 K (-15°C)
Q_rad = ε · σ · (T_surface⁴ - T_sky⁴) Q_rad = 0.92 × 5.67×10⁻⁸ × (278⁴ - 258⁴) Q_rad ≈ 78 W/m²
Site Selection Criteria
Optimal characteristics:
Low humidity (<40% RH at night)
High nighttime cloud cover probability (>70%)
Low wind speed at night (<5 m/s average)
Flat terrain
Non-agricultural land
Access to monitoring infrastructure
Global candidate regions:
Region |
Area Available (km²) |
Annual Clear Night Hours |
Avg Cooling Power (W/m²) |
|---|---|---|---|
Sahara Desert |
500,000 |
2,800 |
65 |
Arabian Desert |
150,000 |
2,600 |
60 |
Australian Outback |
400,000 |
2,400 |
55 |
Gobi Desert |
80,000 |
2,200 |
50 |
Great Basin (USA) |
30,000 |
2,000 |
45 |
Patagonia |
50,000 |
1,800 |
40 |
Total |
1,240,000 |
~2,200 |
~55 |
Scale and Economics
Single facility (100 km²):
Metric |
Value |
|---|---|
Radiative panel area |
80 km² = 8×10⁷ m² |
Avg nighttime cooling power |
50 W/m² |
Annual heat diverted |
8.8×10¹⁶ J/year (88 PJ) |
Initial capital cost |
$400 million |
O&M annual cost |
$4 million |
Cost per ton CO₂eq |
$5-10/ton-year |
Global deployment scenario:
Phase |
Facilities |
Total Area (km²) |
Annual Heat Diverted (EJ) |
Cumulative Cost (B$) |
|---|---|---|---|---|
1 (pilot) |
10 |
1,000 |
8.8 |
5 |
2 (scale) |
100 |
10,000 |
88 |
50 |
3 (regional) |
500 |
50,000 |
440 |
250 |
4 (global) |
2,000 |
200,000 |
1,760 |
1,000 |
Climate Impact
At Phase 4 deployment (200,000 km²):
Annual heat diverted: 1,760 EJ
CO₂ equivalent: ~7,000 metric tons/year
Estimated global temperature effect: 0.01-0.03°C
While modest alone, radiative cooling farms provide:
Zero operational emissions
Potential co-production of water (condensation)
Synergistic use with solar PV (daytime solar, nighttime cooling)
Demonstrable, measurable effects for monitoring
3. Nighttime Ocean Radiative Cooling Enhancement
Background
The oceans cover ~71% of Earth's surface and store ~90% of excess heat from greenhouse warming. Nighttime radiative cooling of the ocean surface naturally occurs but is limited by:
High evaporative loss (latent heat transfer upward)
Turbulent mixing bringing warmer water from below
Cloud cover reducing clear-sky conditions
Enhancement Strategies
Three complementary approaches:
A. Surface Microlayer Enhancement
Deploy biodegradable, IR-transparent, solar-reflective materials that form a thin layer on the ocean surface:
Material requirements:
Low thermal conductivity (reduce mixing with subsurface water)
High IR emissivity in 8-13 μm window
High solar reflectivity
Biodegradable within 24-72 hours
Example: Polymer microsphere layer
Composition: Silica or polyurethane microspheres
Layer thickness: 10-50 μm
Buoyant and self-arranging
Washed off naturally by waves
B. Artificial Ice/Brine Formation
In polar and subpolar regions, induce formation of thin ice or concentrated brine layers at night that:
Have lower thermal conductivity than water
Radiate more efficiently to space
Melt during daytime (no permanent accumulation)
C. Subsurface Upwelling at Night
Use pumps or mixing devices to bring colder subsurface water to the surface at night when radiative cooling is most effective, then allow mixing back during daytime.
Energy Balance Analysis
Current ocean nighttime heat budget (per m²):
Heat Losses:├──Radiative loss to space (clear sky) 40-60 W/m²├──Evaporative loss 20-50 W/m²└──Convective loss 5-15 W/m²
Heat Gains:├──Downwelling IR from atmosphere 30-50 W/m²├──Heat from subsurface mixing 10-30 W/m²└──Upwelling from depth variable
Net:
Often slightly positive (ocean gains heat) due to mixing and
evaporation
With enhancement (microlayer approach):
Modified budget:├──Radiative loss to space (enhanced) 60-80 W/m² (+20-30%)├──Evaporative loss (reduced) 5-15 W/m² (-60-70%)├──Convective loss 5-10 W/m²├──Downwelling IR (unchanged) 30-50 W/m²└──Heat from mixing (reduced) 2-8 W/m² (-70-80%)
Net: 15-35 W/m² heat LOSS to atmosphere/space
Implementation Infrastructure
Microlayer deployment system:
Component |
Description |
|---|---|
Carrier vessels |
Modified tankers, autonomous surface vehicles |
Distribution |
Boom spreaders, spray systems |
Target areas |
5-15 km² patches |
Frequency |
Daily (material biodegrades) |
Cost |
$50-200 per km² per day |
Seasonal deployment strategy:
Region |
Active Months |
Rationale |
|---|---|---|
Arctic |
May-September |
Maximum daylight/heat gain period |
Subarctic (N) |
June-September |
Peak warming |
Subarctic (S) |
December-March |
Peak warming |
Tropical Pacific |
Year-round |
Consistent conditions |
Global Potential
Assuming 1% of ocean surface treated (3.6 million km²):
Average nighttime cooling power: 20 W/m² net
Night hours/year: 4,380 hours
Annual heat removed: 20 × 3.6×10¹² × 1.58×10⁷ = 1.14×10²¹ J = 1,140 EJ/year
CO₂ equivalent removal: ~4,500 metric tons/year
Risks and Considerations
Ecosystem impact: Potential effects on marine organisms, especially plankton and larval stages
Material accumulation: Risk of microplastic pollution if biodegradation fails
Altered evaporation: Changes to precipitation patterns
Economic viability: High ongoing costs for material production and deployment
Regulatory complexity: International waters governance
4. Atmospheric Water Harvesting via Radiative Cooling
Mechanism
Radiative cooling surfaces that drop below the dew point of ambient air condense water vapor into liquid water. This process is both a water resource and a cooling mechanism:
Radiative surface cooling - Surface cools below ambient via IR emission
Condensation - Water vapor condenses on cold surface
Latent heat release - Released heat is radiated away during continued nighttime cooling
Cooling effect - Surface stays cooler than it otherwise would due to evaporative/latent cooling cycle
System Design
Atmospheric water harvester (AWH) with climate cooling function:
Component |
Specification |
|---|---|
Condensing surface |
Copper or aluminum with hydrophobic coating |
Surface area per unit |
50-500 m² |
Target temperature |
10-15°C below ambient |
Collection system |
Tilted panels to channels |
Storage |
Insulated tanks |
Power requirement |
Minimal (fans, pumps optional) |
Performance by humidity:
RH (%) |
Temp (°C) |
Dew Point (°C) |
Water Yield (L/m²/night) |
Latent Heat Released (kJ/m²) |
|---|---|---|---|---|
20 |
25 |
-6 |
0 |
0 |
40 |
30 |
16 |
1.2 |
2,700 |
60 |
35 |
26 |
3.5 |
8,000 |
80 |
30 |
25 |
5.0 |
11,500 |
Dual-Benefit Analysis
For each liter of water harvested:
Water produced: 1 L (value: $0.10-$10 depending on location)
Cooling effect:
Latent heat of vaporization: 2,260 J/g
Per liter: 2.26 MJ of heat moved from air to surface and radiated away
Extended radiative cooling: Wet surfaces can radiate more effectively than dry ones
Climate vs. water benefits by region:
Region |
Annual Water Yield (L/m²) |
Annual Cooling (MJ/m²) |
Primary Benefit |
|---|---|---|---|
Coastal California |
2,500 |
180 |
Water |
Middle East |
1,800 |
130 |
Water + cooling |
Northern Africa |
2,200 |
160 |
Water |
South Asia |
4,000 |
290 |
Cooling + water |
Southeast Asia |
5,000 |
365 |
Cooling |
Large-Scale Deployment
Urban integration approach:
Rooftop AWH systems in coastal and semi-arid cities
Integration with building cooling systems
Scale: 1 m² AWH per 10 m² of building
Global potential (assuming 50 million m² total AWH area in arid/semi-arid regions):
Annual water production: ~250 million L
Annual heat radiated away via latent heat mechanism: ~1.8×10¹⁴ J
Additional heat from enhanced radiative surface cooling: ~3.6×10¹⁴ J
Total cooling: ~5.4×10¹⁴ J/year (0.54 EJ)
CO₂ equivalent: ~2,000 metric tons/year
Advantages
Addresses two climate challenges simultaneously (water scarcity + warming)
Passive operation with minimal energy
Synergistic with building energy efficiency
Water can support vegetation, further cooling via transpiration
5. Radiative Cooling Towers
Concept
Massive structures analogous to industrial cooling towers, but designed to radiate heat directly to space rather than using evaporative cooling. These towers maximize surface area-to-volume ratio for radiative loss and are positioned to access cooler nighttime air.
Engineering Design
Tower geometry:
Hyperboloid shape (similar to existing cooling towers)
Height: 100-300 m
Base diameter: 150-400 m
Top diameter: 50-150 m
Surface treatment:
Entire interior and exterior coated with high-emissivity, high-solar-reflectivity materials
Surface area per tower: 50,000-300,000 m²
Heat transfer modes within tower:
Air-borne heat removal (natural convection):
Warm air rises through tower, cooling via contact with radiating walls
Heat radiated from walls to night sky
Cooled air exits at top and disperses
Liquid-borne heat removal (optional):
Warm water circulated through tower exterior/interior
Water cooled radiatively, then pumped back to source
Can serve district cooling applications
Performance Calculations
Radiative cooling tower (200 m tall, 200 m base diameter):
Parameter |
Value |
|---|---|
Surface area |
180,000 m² |
Effective emissivity |
0.88 |
Average night temperature |
15°C |
Effective sky temperature (clear) |
-10°C |
Radiative power per m² |
~55 W/m² |
Total radiative cooling power |
9.9 MW |
Annual heat removed (clear nights) |
1.2×10¹¹ kJ |
Comparison to conventional evaporative tower:
Metric |
Radiative Tower |
Evaporative Tower |
|---|---|---|
Cooling capacity |
10-20 MW |
50-100 MW |
Water usage |
0 L/h |
5,000-10,000 L/h |
Energy input |
0-50 kW |
500 kW-2 MW |
Nighttime efficiency |
100% (passive) |
70-90% |
Climate benefit |
Direct + no emissions |
Direct only |
Heat Sink Applications
Three primary use cases:
A. Nighttime Urban Heat Disposal
Collect heat from urban buildings during day (via district heating/thermal storage)
Radiate it away at night through cooling towers
Reduces daytime air conditioning demand
B. Power Plant Heat Sink
Replace or supplement evaporative cooling at thermal/nuclear plants
Particularly valuable in water-scarce regions
C. Direct Climate Cooling
Towers designed solely to radiate ambient heat to space
Positioned in high-altitude, clear-sky regions
Global Deployment Scenario
Phase 1: 100 radiative cooling towers
Locations: Major urban centers (2-5 per city)
Total annual heat removed: 1.2×10¹³ kJ
Phase 2: 1,000 towers
Expanded urban and industrial coverage
Total annual heat removed: 1.2×10¹⁴ kJ
Phase 3: 5,000 towers
Global coverage of major population/industrial centers
Total annual heat removed: 6×10¹⁴ kJ (0.6 EJ)
Cost estimates:
Construction per tower: $50-200 million
Phase 3 total construction: $250-1,000 billion
CO₂ equivalent removal (Phase 3): ~2,500 metric tons/year
Technical Challenges
Lower cooling capacity than evaporative towers (must overcome with scale)
High construction cost per unit
Requires clear-sky regions for optimal performance
Wind loads and structural design at large heights
6. Upper-Altitude Radiative Cooling Platforms
Principle
At high altitudes, the atmospheric density is lower, providing less obstruction to radiative cooling. Platforms (balloons, gliders, or satellites) carrying radiative cooling surfaces at 20-50 km altitude can radiate heat directly to space with minimal atmospheric interference.
Platform Types
A. High-Altitude Balloons
Characteristics:
Operating altitude: 20-35 km
Duration: Weeks to months
Radiative surface area per balloon: 50-500 m²
Power: Solar PV for station-keeping and telemetry
Advantages:
Low cost compared to satellites
Easy to deploy and replace
Access to mesosphere where IR window is nearly fully open
B. Aerostats (Buoyant Platforms)
Characteristics:
Operating altitude: 15-30 km
Duration: Years
Radiative surface area per platform: 500-5,000 m²
Power: Solar + batteries
C. Low-Earth Orbit Satellites
Characteristics:
Altitude: 200-800 km
Radiative surface area per satellite: 1,000-10,000 m²
No atmospheric obstruction
Continuous radiative cooling (except during eclipse)
Radiative Cooling Performance vs. Altitude
Effective radiative cooling power:
Altitude |
Atmospheric Pressure |
Clear-Sky Factor |
Effective T_sky (K) |
Radiative Power (W/m²) |
|---|---|---|---|---|
0 km (surface) |
1013 mbar |
0.70 |
248 |
45 |
10 km |
265 mbar |
0.92 |
215 |
75 |
20 km |
55 mbar |
0.98 |
185 |
95 |
35 km |
12 mbar |
1.00 |
165 |
110 |
50+ km (space) |
~0 mbar |
1.00 |
4.2 K |
350+ |
System Design: High-Altitude Balloon Fleet
Single balloon system:
Parameter |
Specification |
|---|---|
Balloon type |
Superpressure helium |
Operating altitude |
30 km |
Radiative surface |
200 m² of photonic metamaterial |
Radiative power |
110 W/m² × 200 = 22 kW |
Lifetime |
90 days |
Cost (including deployment) |
$500,000 |
Fleet of 10,000 balloons (rotated continuously):
Active at any time: ~5,000
Total radiative power: 5,000 × 22 kW = 110 MW
Annual heat radiated: 110 MW × 3.15×10⁷ s = 3.47×10¹⁵ J = 3,470 GJ
Annual operational cost (replacements, telemetry): $2.5 billion
Satellite-Based System
Constellation design:
Parameter |
Specification |
|---|---|
Number of satellites |
500 |
Orbit |
600 km, sun-synchronous |
Radiative surface per sat |
2,000 m² deployable |
Radiative power per sat |
350 W/m² × 2,000 = 700 kW |
Constellation power |
350 MW |
Lifetime |
15 years |
Cost per satellite |
$100 million |
Total constellation cost |
$50 billion |
Annual heat radiated: 350 MW × 3.15×10⁷ s = 1.10×10¹⁶ J = 11 PJ/year
Cost-Effectiveness Comparison
Platform |
Cost per TJ Radiated |
Operational Lifetime |
Notes |
|---|---|---|---|
Surface radiative cooler |
$0.10 |
20+ years |
Lowest cost |
Cooling tower |
$0.50 |
50+ years |
Large-scale |
High-altitude balloon |
$8.00 |
90 days |
Moderate |
Aerostat |
$5.00 |
5-10 years |
Medium |
LEO satellite |
$4.50 |
15 years |
Highest power |
Strategic Value
High-power radiative cooling: Space-based platforms can radiate 5-10× more per m² than surface systems
Geographic flexibility: Can target specific latitudes/longitudes
No land use: Eliminates terrestrial ecological concerns
Dual-use potential: Platforms could also monitor climate or provide communications
Scalable: Start small, expand incrementally
Challenges
High cost per unit
Space debris and orbital congestion concerns
Complex launch and maintenance infrastructure
Political/regulatory complexity for space-based climate engineering
Single-point failure risk for satellites
7. Enhanced Desert Radiative Cooling
Background
Desert regions naturally experience extreme nighttime radiative cooling due to clear skies, low humidity, and minimal vegetation. However, natural desert surfaces (sand, rock) have suboptimal radiative properties and can be engineered to enhance this natural phenomenon.
Enhancement Approaches
A. Surface Modification
Materials and treatments:
Spread high-emissivity mineral coatings (e.g., MgO, SiO₂) over desert floors
Install radiative cooling panels interspersed with natural terrain
Create reflective gravel or stone pavements with high IR emissivity
B. Desert Radiative Corridors
Long, narrow channels or "corridors" oriented to maximize IR transmission to space:
Width: 50-200 m
Length: 10-100 km
Treated surfaces on sides and floor
Oriented perpendicular to prevailing night winds
C. Thermal Mass Reduction
Reduce thermal mass of desert surfaces to enable deeper nighttime cooling:
Remove or replace high-thermal-mass rocks and concrete
Install lightweight radiative materials
Create air gaps beneath surface layers
Quantitative Analysis
Natural desert night cooling vs. enhanced:
Parameter |
Natural Desert Sand |
Enhanced (SiO₂ coating) |
|---|---|---|
Surface emissivity (8-13μm) |
0.82 |
0.93 |
Solar reflectivity |
0.25 |
0.65 |
Thermal mass (J/kg·K) |
800 |
350 |
Nighttime ΔT vs air (°C) |
-6 to -10 |
-14 to -20 |
Radiative power (W/m²) |
35-50 |
60-85 |
Example: Enhanced radiative cooling in Sahara
Area treated: 100,000 km² (10% of Sahara)
Enhancement: +30 W/m² average nighttime cooling power
Night hours/year: 2,800 hours
Annual additional heat radiated: 30 × 10¹¹ × 10⁴ × 10,080 = 3.0×10²⁰ J = 300 EJ
Infrastructure and Economics
Treatment methods:
Method |
Cost ($/km²) |
Lifetime |
Maintenance |
|---|---|---|---|
Mineral coating spread |
500,000 |
5-10 years |
Annual reapplication |
Panel installation |
2,000,000 |
20+ years |
Low |
Gravel paving |
800,000 |
30+ years |
Low |
Air-gap substrate |
1,200,000 |
25+ years |
Medium |
ROI considerations:
No direct economic return (pure climate benefit)
Potential co-benefits: reduced daytime heating (less energy for cooling), increased fog/condensation capture
Carbon credit revenue possible under future markets
Regional Climate Effects
Potential secondary effects of large-scale desert radiative cooling:
Altered wind patterns: Enhanced cooling could strengthen nighttime thermal winds
Precipitation changes: Cooler air holds less moisture, potentially reducing fog/precipitation locally
Dust reduction: Treated surfaces may reduce dust generation
Biodiversity impacts: Temperature changes could affect desert flora/fauna
Albedo change: Increased reflectivity during daytime could further reduce warming
8. Radiative Cooling as Heat Sink for Heat Pumps
Principle
Radiative cooling surfaces can serve as the "cold side" (heat sink) for heat pumps, enabling heat to be pumped from warm sources (buildings, industrial processes, or the atmosphere) to the cold night sky. This amplifies the natural radiative cooling effect through active thermodynamic work.
System Architecture
Nighttime heat pump cycle:
[Heat Pump System]┌──────────────┐Warm Source (T_warm)│ │ Radiative Cooler (T_cold)(e.g., │ Heat │ ──────► Night Sky (T_sky)building, │ Pump │ (radiative loss)process, │ (COP) │air) │ │└──────────────┘▲│Electrical Power
Key performance metric: Coefficient of Performance (COP)
COP = Q_cooling / W_electrical
Where:
Q_cooling = heat removed from warm source
W_electrical = electrical power consumed
Technical Specifications
Heat pump coupled with radiative cooler:
Parameter |
Value |
|---|---|
Warm source temperature |
20-30°C |
Radiative cooler temperature (night) |
-5 to 10°C |
Temperature lift (ΔT) |
25-35 K |
Heat pump type |
Scroll or screw compressor |
COP (at design point) |
2.5-4.0 |
Heat pump capacity |
100 kW - 5 MW |
Annual operating hours |
1,500-2,500 |
Cooling Power Amplification
Example: 1 MW heat pump coupled to 50,000 m² radiative cooler:
Parameter |
Calculation |
Result |
|---|---|---|
Radiative cooler area |
- |
50,000 m² |
Radiative power density |
60 W/m² |
- |
Passive radiative cooling |
50,000 × 60 |
3 MW |
Heat pump capacity |
1 MW (electrical input) |
- |
COP |
3.0 |
- |
Active heat pumping |
1 × 3.0 |
3 MW |
[TRUNCATED: original longer than 200KB] README historyThe author's README evolved over time. Click a version to see its content at that point.
Discussions
Catalog is the map. Apps are the tools. Run models on your own machine, not in the cloud.Every model page has an "Open in Abliteration" button that hands the model directly to the first-party desktop client, at the quantization your rig can actually run. No API keys, no subscription, no prompt leakage. |