license: apache-2.0
pipeline_tag: text-generation
base_model: fearlessdots/WizardLM-2-7B-abliterated
WizardLM-2-7B-abliterated-GGUF
This is quantized version of fearlessdots/WizardLM-2-7B-abliterated created using llama.cpp
Model Description
This is the WizardLM-2-7B model with orthogonalized bfloat16 safetensor weights, based on the implementation by @failspy. For more info:
- Original paper preview presenting the methodology: https://www.alignmentforum.org/posts/jGuXSZgv6qfdhMCuJ/refusal-in-llms-is-mediated-by-a-single-direction
- Jupyter notebook containing a implementation of the methodology, by
@failspy: https://huggingface.co/failspy/llama-3-70B-Instruct-abliterated/blob/main/ortho_cookbook.ipynb
Prompt Template
This model uses the prompt format from Vicuna and supports multi-turn conversation.
Original model card:
🤗 HF Repo •🐱 Github Repo • 🐦 Twitter • 📃 [WizardLM] • 📃 [WizardCoder] • 📃 [WizardMath]
👋 Join our Discord
News 🔥🔥🔥 [2024/04/15]
We introduce and opensource WizardLM-2, our next generation state-of-the-art large language models,
which have improved performance on complex chat, multilingual, reasoning and agent.
New family includes three cutting-edge models: WizardLM-2 8x22B, WizardLM-2 70B, and WizardLM-2 7B.
- WizardLM-2 8x22B is our most advanced model, demonstrates highly competitive performance compared to those leading proprietary works
and consistently outperforms all the existing state-of-the-art opensource models. - WizardLM-2 70B reaches top-tier reasoning capabilities and is the first choice in the same size.
- WizardLM-2 7B is the fastest and achieves comparable performance with existing 10x larger opensource leading models.
For more details of WizardLM-2 please read our release blog post and upcoming paper.
Model Details
- Model name: WizardLM-2 7B
- Developed by: WizardLM@Microsoft AI
- Base model: mistralai/Mistral-7B-v0.1
- Parameters: 7B
- Language(s): Multilingual
- Blog: Introducing WizardLM-2
- Repository: https://github.com/nlpxucan/WizardLM
- Paper: WizardLM-2 (Upcoming)
- License: Apache2.0
Model Capacities
MT-Bench
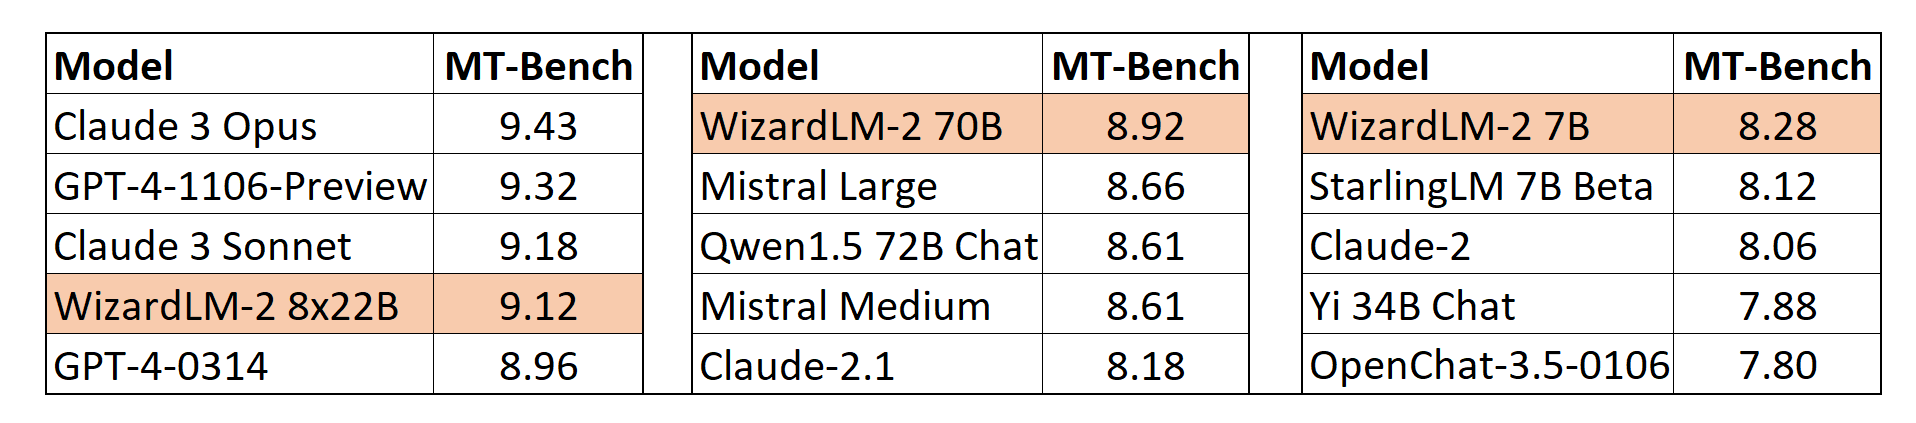
We also adopt the automatic MT-Bench evaluation framework based on GPT-4 proposed by lmsys to assess the performance of models.
The WizardLM-2 8x22B even demonstrates highly competitive performance compared to the most advanced proprietary models.
Meanwhile, WizardLM-2 7B and WizardLM-2 70B are all the top-performing models among the other leading baselines at 7B to 70B model scales.
Human Preferences Evaluation
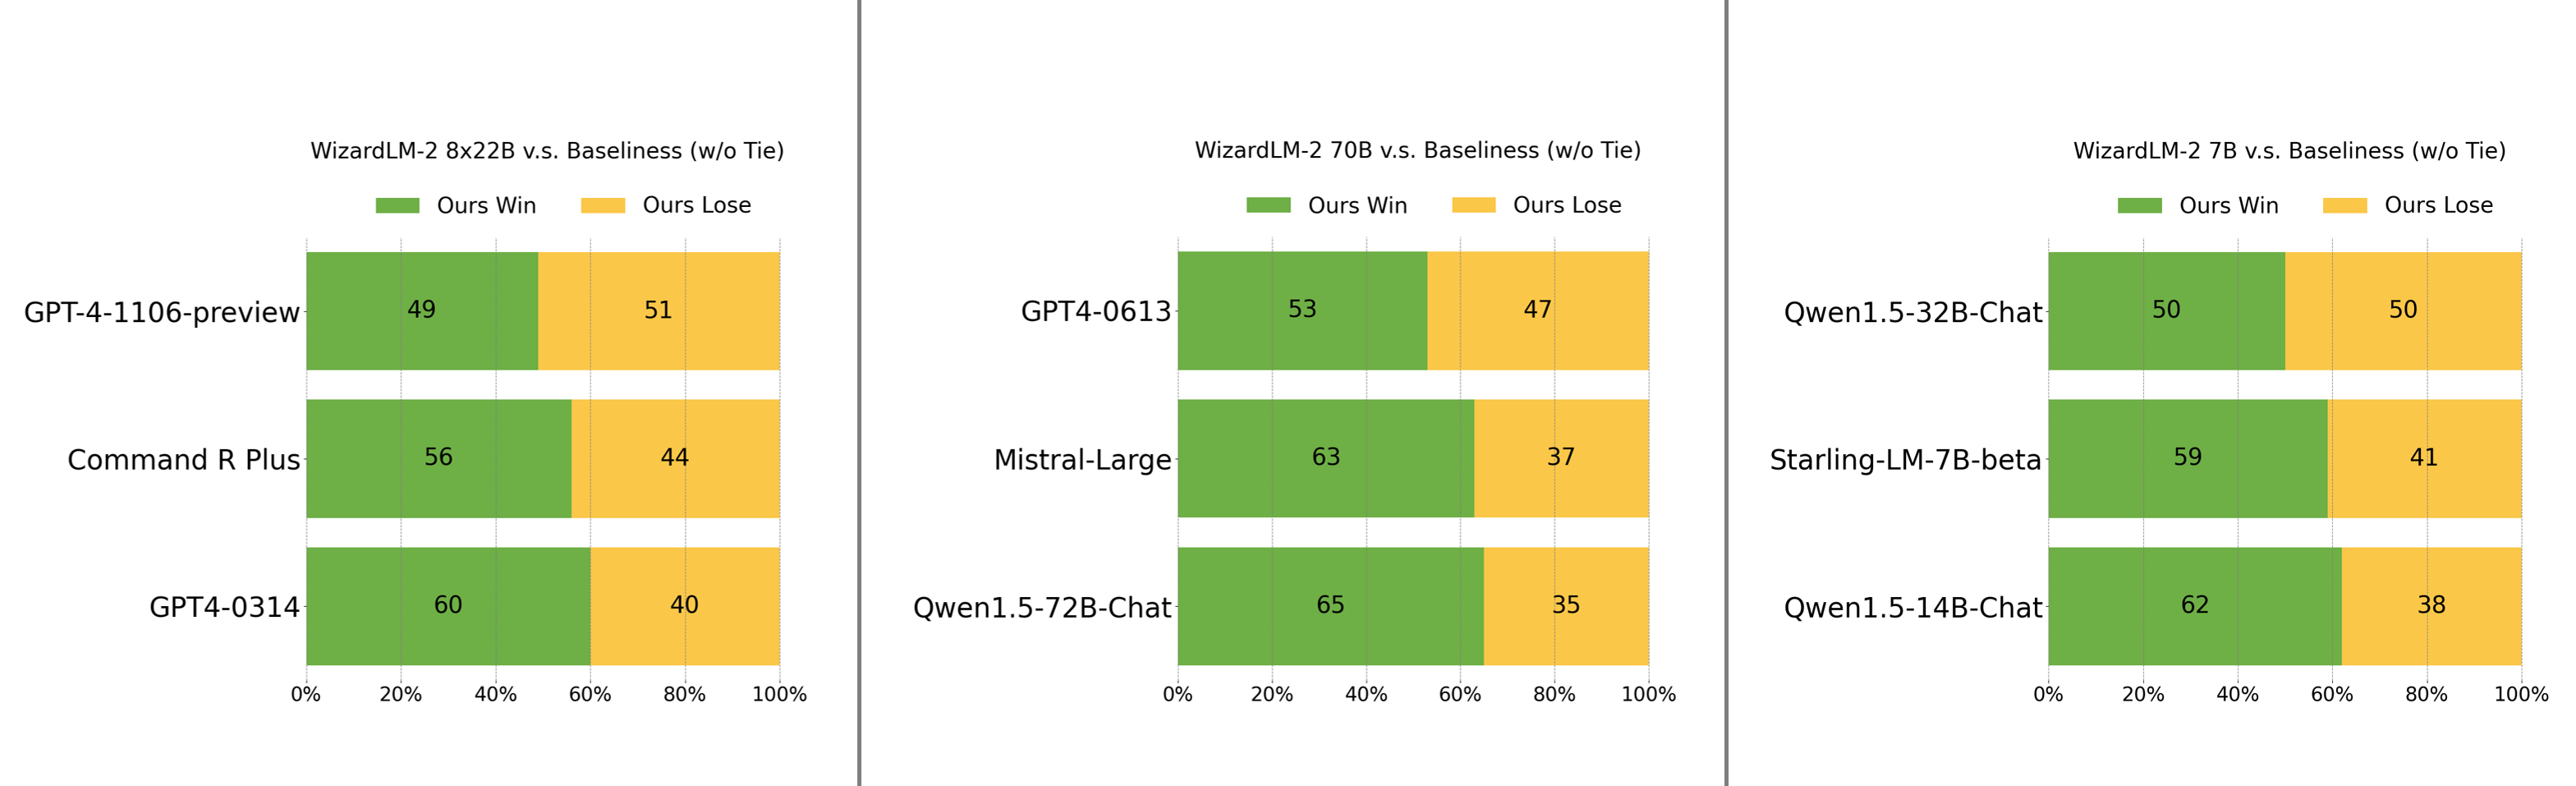
We carefully collected a complex and challenging set consisting of real-world instructions, which includes main requirements of humanity, such as writing, coding, math, reasoning, agent, and multilingual.
We report the win:loss rate without tie:
- WizardLM-2 8x22B is just slightly falling behind GPT-4-1106-preview, and significantly stronger than Command R Plus and GPT4-0314.
- WizardLM-2 70B is better than GPT4-0613, Mistral-Large, and Qwen1.5-72B-Chat.
- WizardLM-2 7B is comparable with Qwen1.5-32B-Chat, and surpasses Qwen1.5-14B-Chat and Starling-LM-7B-beta.
Method Overview
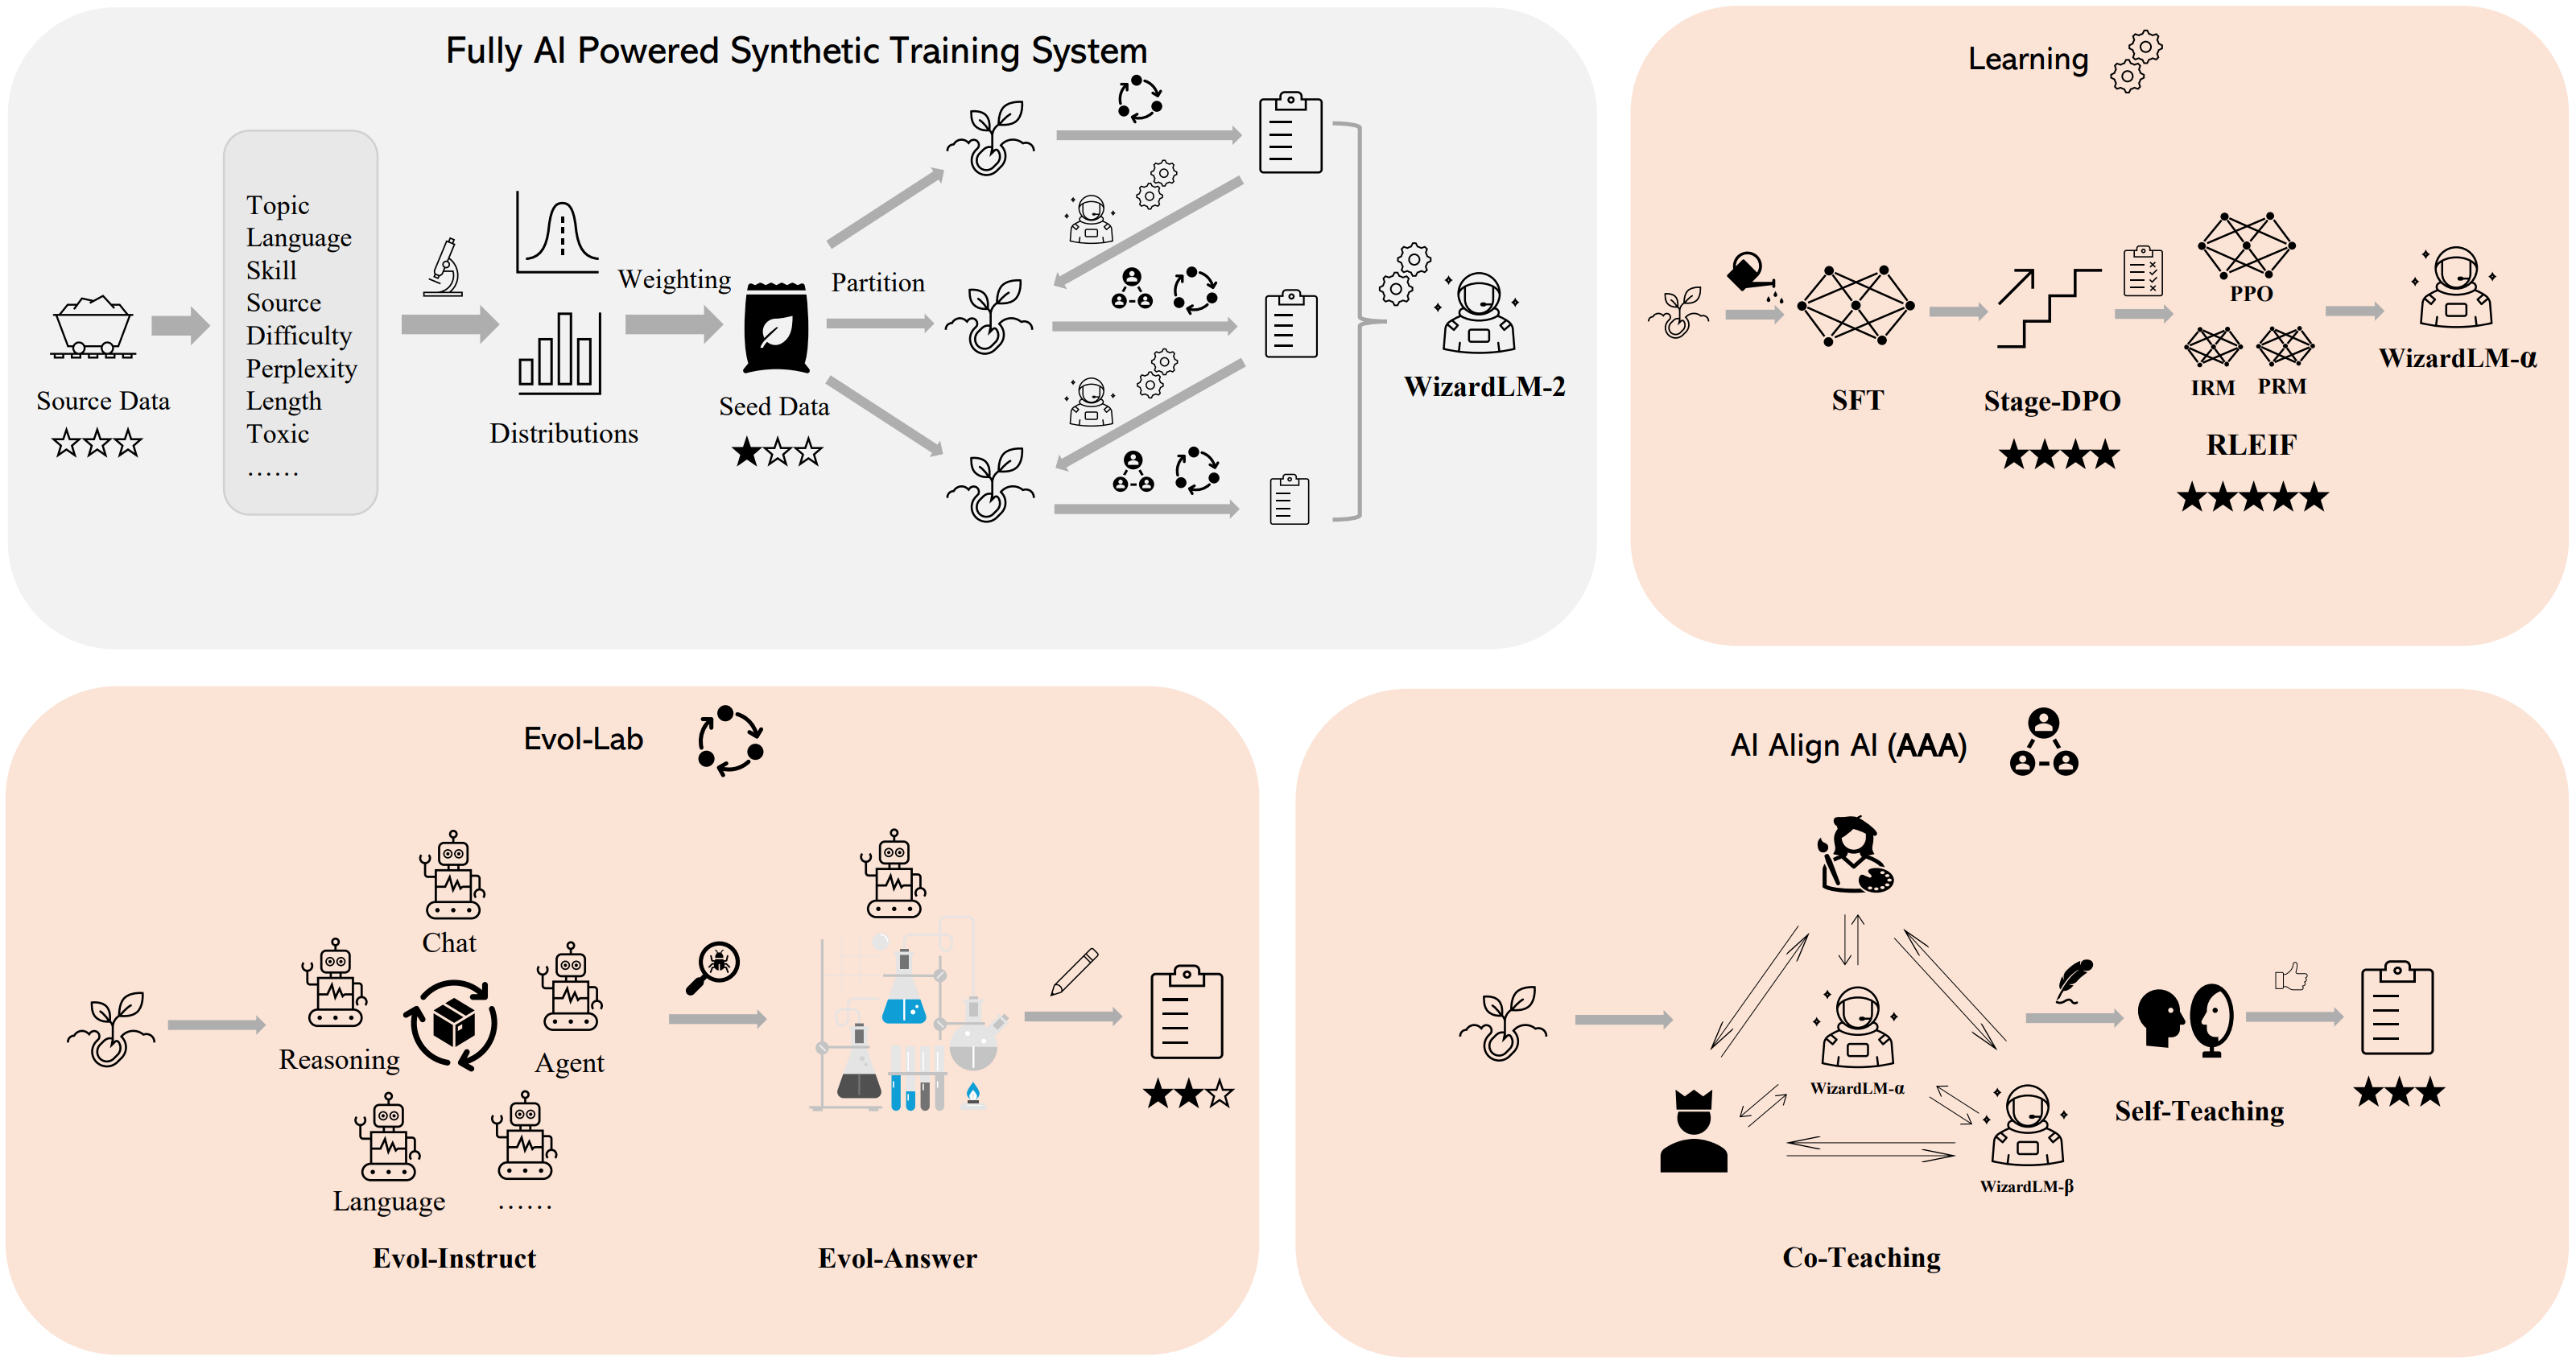
We built a fully AI powered synthetic training system to train WizardLM-2 models, please refer to our blog for more details of this system.
Usage
❗Note for model system prompts usage:
WizardLM-2 adopts the prompt format from Vicuna and supports multi-turn conversation. The prompt should be as following:
A chat between a curious user and an artificial intelligence assistant. The assistant gives helpful,
detailed, and polite answers to the user's questions. USER: Hi ASSISTANT: Hello.</s>
USER: Who are you? ASSISTANT: I am WizardLM.</s>......
Inference WizardLM-2 Demo Script
We provide a WizardLM-2 inference demo code on our github.