license: apache-2.0
base_model: Qwen/Qwen3.6-27B
tags:
- abliterated
- uncensored
- mtp
- gguf
- qwen3.6
- heretic
- speculative-decoding
- imatrix
- tool-use
- agentic
- pentest
- function-calling
language:
- en
- es
- zh
Qwen3.6-27B Abliterated + MTP GGUF
The first publicly available Qwen3.6-27B uncensored GGUF with native MTP speculative decoding.
Refusal-free at the weight level · Full MTP block grafted · ~70 t/s on RTX 3090 · No custom fork required
Published by Gastón Parravicini
Why this exists
When Qwen3.6-27B dropped, two things were true at the same time:
- The only abliterated versions available had no MTP support — the draft heads were stripped during the merge, killing speculative decoding speed
- The only MTP-enabled GGUFs were fully censored — original refusal behavior intact
Nobody had combined both. Doing it required writing custom patches to handle Qwen3.6's MTP tensor naming conventions and avoid GGUF metadata corruption. This release is the result of that work.
This was the first. It still has the most complete quant coverage.
What this release adds
Refusal suppression
Removed at the weight level using two-pass orthogonal-projection abliteration (abliterix + Optuna TPE). KL divergence of 0.024 vs the base model — well below the 0.05 threshold where quality degradation becomes measurable. General intelligence, reasoning, and tool use are fully intact.
Full MTP speculative decoding
The complete blk.64 MTP block — all 15 tensors — grafted from the official Unsloth release. MTP is baked into Qwen3.6-27B at training time, so the draft heads are native, not bolted on.
| Config | Speed | Notes |
|---|---|---|
| No MTP | ~45 t/s | baseline |
MTP --spec-draft-n-max 3 |
~70 t/s | recommended |
| Draft acceptance rate | 90–100% | context-dependent |
| Max tested context | 150k tokens | RTX 3090, q4_0 KV |
~55% speedup. No quality loss. No custom fork required — MTP support is now in llama.cpp mainline.
Quants
| File | Size | VRAM | Notes |
|---|---|---|---|
| Q2_K | 11 GB | 12 GB | Fast, lower quality |
| Q3_K_M | 13 GB | 16 GB | Decent for 16GB GPUs |
| Q4_K_M | 16 GB | 24 GB | Recommended — best quality/speed tradeoff |
| Q5_K_M | 19 GB | 24 GB+ | Noticeably better than Q4 |
| Q6_K | 21 GB | 32 GB | High fidelity |
| Q8_0 | 28 GB | 48 GB | Near-lossless |
Mac users: memory is unified — M2 Max 32GB fits Q4_K_M comfortably.
All quants include the full MTP draft head block. Speculative decoding works across all tiers.
Requirements
MTP support is now in llama.cpp mainline. No custom fork needed.
git clone https://github.com/ggml-org/llama.cpp.git
cd llama.cpp
cmake -B build -DGGML_CUDA=ON -DCMAKE_BUILD_TYPE=Release
cmake --build build -j$(nproc) --target llama-server llama-cli
For Mac (Metal), replace -DGGML_CUDA=ON with -DGGML_METAL=ON.
Usage
Standard server (OpenAI-compatible API)
./llama-server \
  -m Qwen3.6-27B-abliterated-Gaston-MTP-Q4_K_M.gguf \
  -ngl 99 \
  --flash-attn on \
  --ctx-size 32768 \
  --spec-type draft-mtp \
  --spec-draft-p-min 0.75 \
  --spec-draft-n-max 3 \
  --cache-type-k q4_0 \
  --cache-type-v q4_0 \
  --host 0.0.0.0 \
  --port 8080 \
  --jinja \
  -n 16384
Agentic and coding workloads (thinking visible)
./llama-server \
  -m Qwen3.6-27B-abliterated-Gaston-MTP-Q4_K_M.gguf \
  -ngl 99 \
  --flash-attn on \
  --ctx-size 80000 \
  -b 2048 -ub 1024 \
  --temp 0.6 \
  --top-p 0.95 \
  --top-k 20 \
  --min-p 0.0 \
  --spec-type draft-mtp \
  --spec-draft-p-min 0.75 \
  --spec-draft-n-max 3 \
  --cache-type-k q4_0 \
  --cache-type-v q4_0 \
  --host 0.0.0.0 \
  --port 8080 \
  --jinja \
  -n 16384 \
  --chat-template-kwargs '{"preserve_thinking":true}'
Recommended sampling
temperature: 0.6
top_p: 0.95
top_k: 20
min_p: 0.0
Validated use cases
This model has been tested in production with:
- PentAGI — autonomous multi-agent penetration testing, full tool call loop
- Qwen Code — agentic coding with MCP servers (Context7, SearXNG)
- OpenClaw — local agent framework with OpenAI-compatible API
- Standard OpenAI function calling via
--jinjachat template
The abliteration does not affect tool call behavior, function calling, or structured output generation.
Abliteration quality
Refusal suppression was done with orthogonal projection + Optuna TPE optimization. The result is one of the cleanest abliterations publicly available for this model:
| Metric | This model | Typical abliteration |
|---|---|---|
| KL divergence vs base | 0.024 | 0.04–0.10 |
| Refusals (out of 100) | ~2/100 | varies |
| Quality threshold | < 0.05 ✅ | often exceeded |
Lower KL divergence = closer to the original model's output distribution = less quality loss. At 0.024, the abliteration is essentially invisible to downstream tasks.
Base model benchmarks
Capabilities are fully preserved. Abliteration removes refusal directions only — not reasoning, coding, or general intelligence.
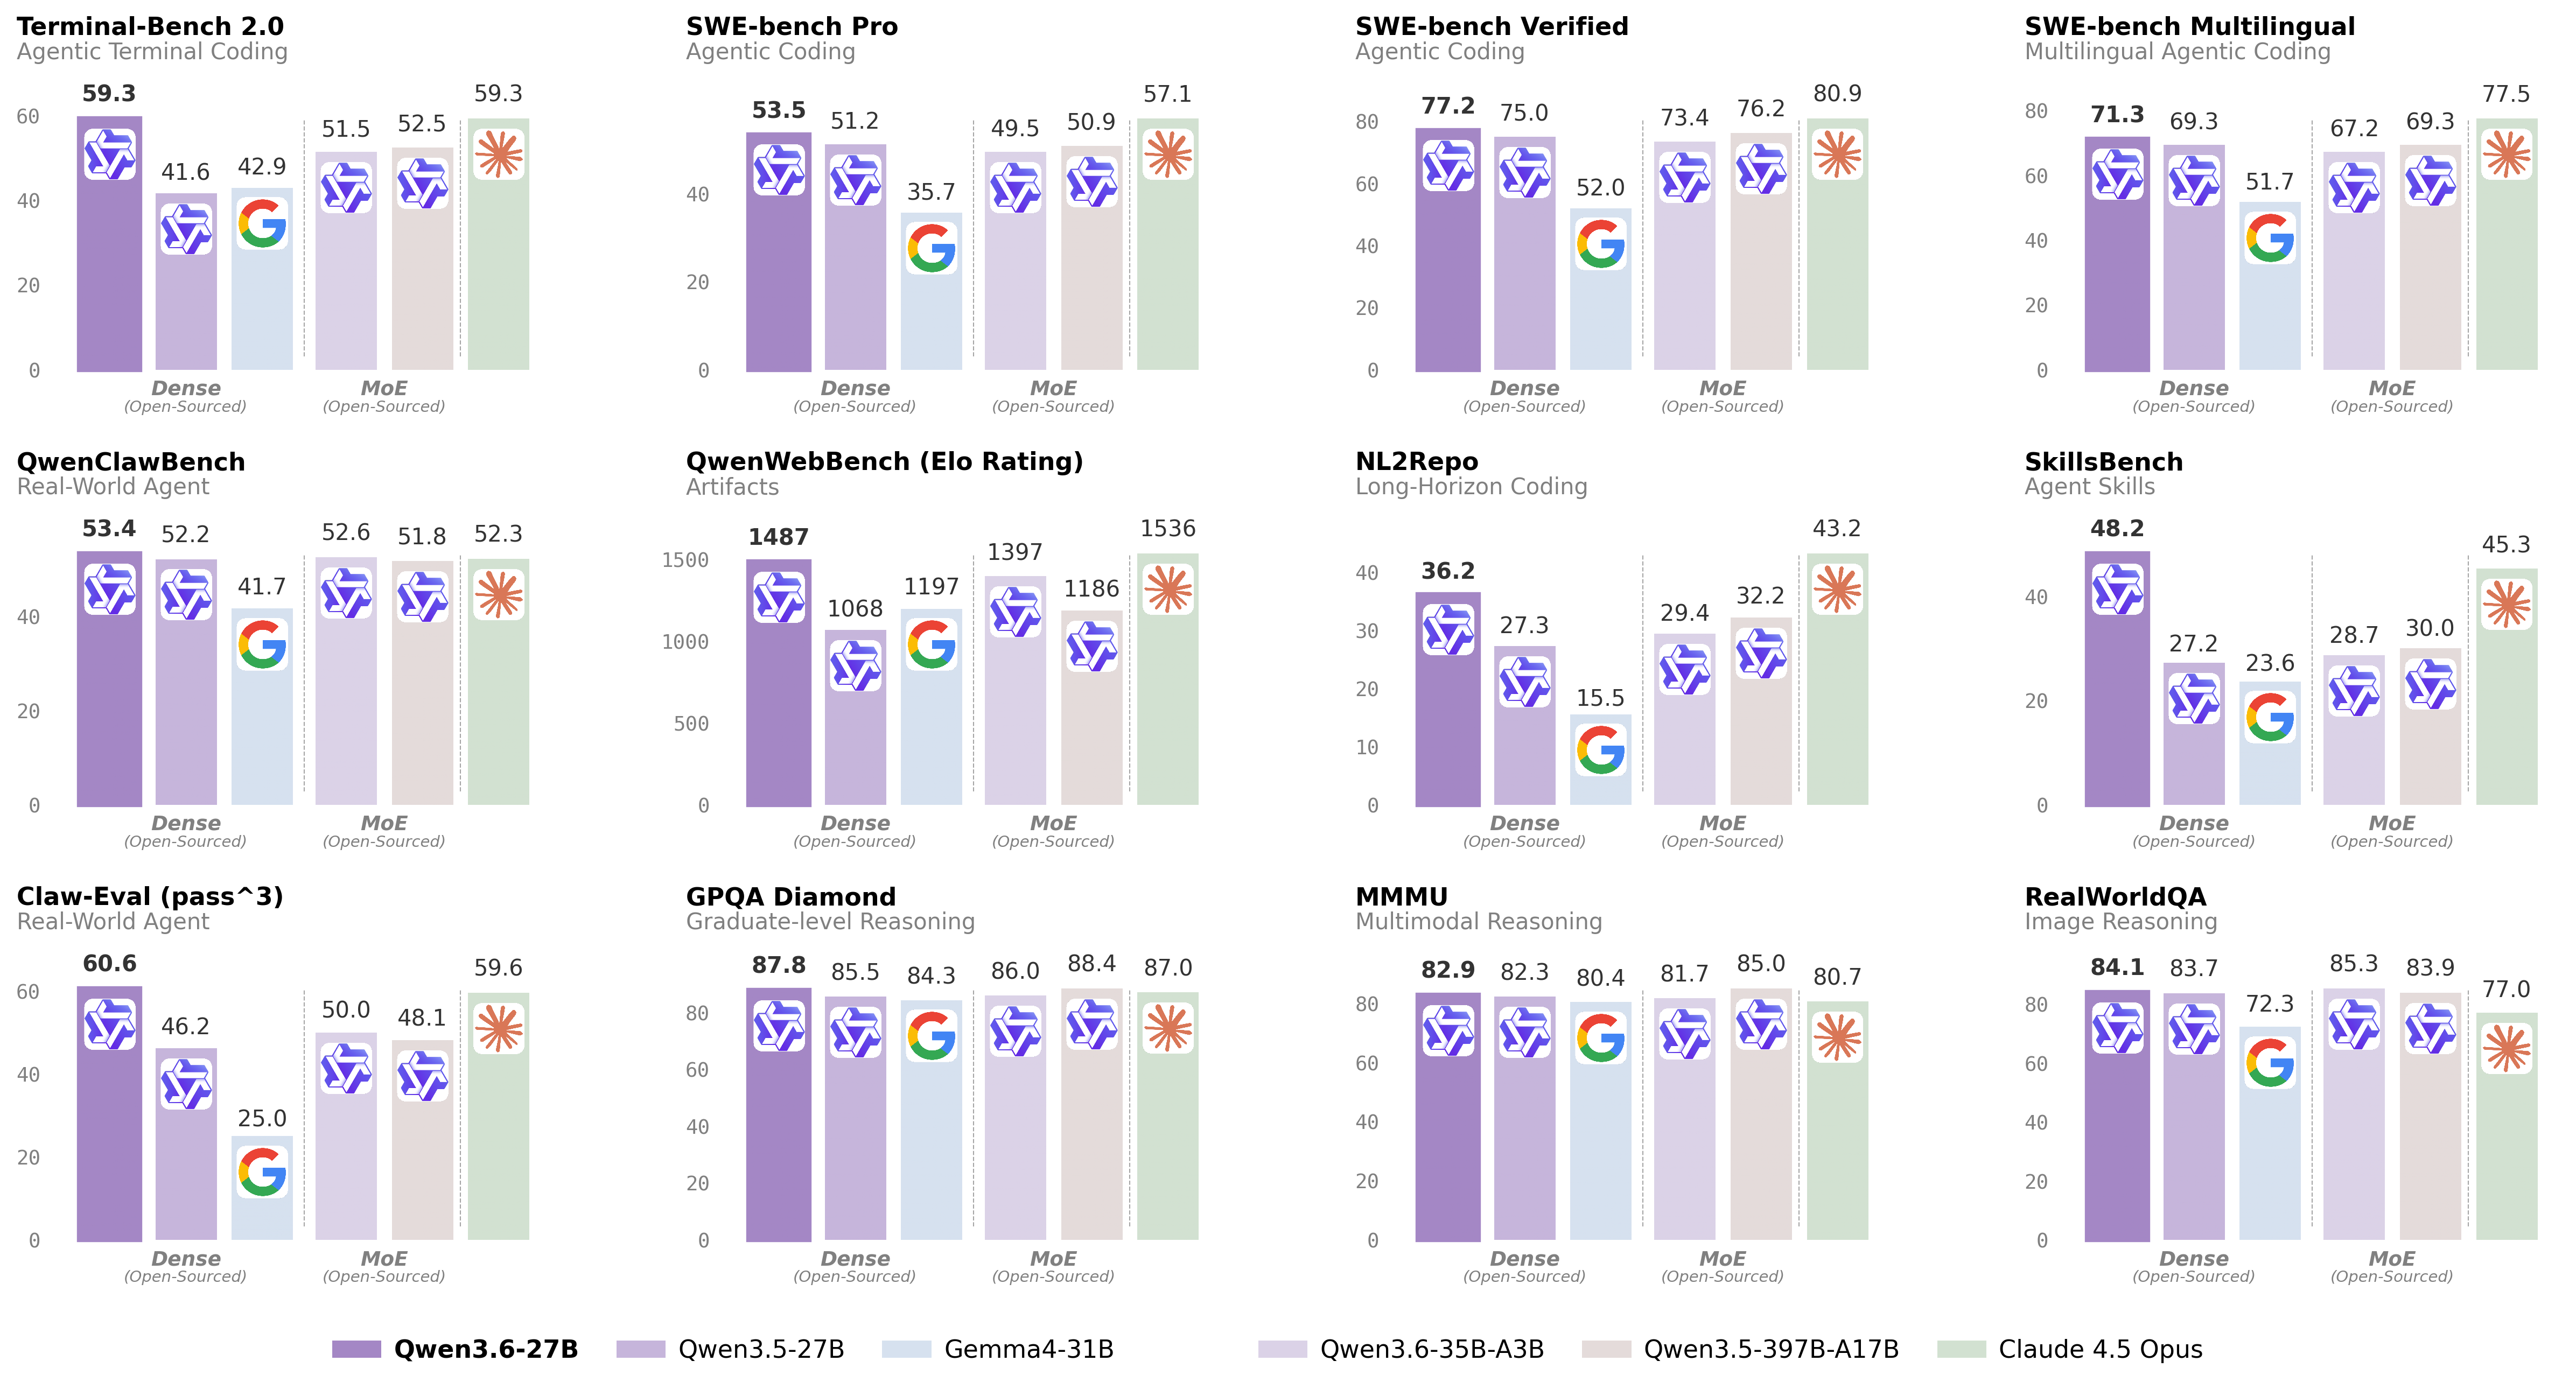
Coding & Agentic
| Benchmark | Qwen3.5-27B | Qwen3.6-27B |
|---|---|---|
| SWE-bench Verified | 75.0 | 77.2 |
| SWE-bench Pro | 51.2 | 53.5 |
| SWE-bench Multilingual | 69.3 | 71.3 |
| Terminal-Bench 2.0 | 41.6 | 59.3 |
| SkillsBench Avg5 | 27.2 | 48.2 |
| LiveCodeBench v6 | 80.7 | 83.9 |
Knowledge & Reasoning
| Benchmark | Qwen3.5-27B | Qwen3.6-27B |
|---|---|---|
| MMLU-Pro | 86.1 | 86.2 |
| GPQA Diamond | 85.5 | 87.8 |
| AIME 2026 | 92.6 | 94.1 |
| HMMT Feb 26 | 84.3 | 84.3 |
| SuperGPQA | 65.6 | 66.0 |
Full benchmark details: official Qwen3.6-27B model card.
How this was built
Standard abliteration pipelines strip MTP tensors during the merge — there was no existing tool that preserved them. This required a custom multi-step process:
- Download
wangzhang/Qwen3.6-27B-abliteratedBF16 safetensors — abliteration via two-pass orthogonal projection with Optuna TPE optimization (KL divergence 0.024) - Convert to GGUF Q8_0 using the llama.cpp converter
- Graft the full
blk.64MTP block (15 tensors) fromunsloth/Qwen3.6-27B-MTP-GGUFusing a patched version of havenoammo's graft script - Three custom patches written to handle Qwen3.6's MTP tensor naming conventions and prevent duplicate KV metadata errors in the output GGUF
- Quantize all tiers from the grafted Q8_0 using
llama-quantize - Validate MTP activation in llama.cpp — confirmed draft acceptance rates above 90% across all context lengths tested
The three patches were the non-trivial part. Qwen3.6's tensor naming diverges from prior Qwen versions in ways that broke existing graft tooling. No existing public script handled this correctly at the time of release.
Credits
| Component | Author |
|---|---|
| Base model | Alibaba Qwen Team |
| Abliteration weights | wangzhang / abliterix |
| MTP draft heads | Unsloth |
| Graft script (base) | havenoammo |
| MTP llama.cpp branch (original validation) | am17an |
| MTP llama.cpp mainline merge | llama.cpp contributors |
| Custom patches, integration, quantization, publication | Gastón Parravicini |
License
Apache 2.0, inherited from Qwen/Qwen3.6-27B.
Disclaimer
This model has had its safety guardrails removed at the weight level. It is intended for research, security testing, and unrestricted local inference. You are solely responsible for how you use it.