license: apache-2.0
language:
- en
- zh
library_name: transformers
pipeline_tag: text-generation
tags: - minicpm
- minicpm5
- llama
- text-generation
- long-context
- tool-calling
- on-device
- edge-ai
- heretic
- uncensored
- decensored
- abliterated
- reproducible
datasets: - openbmb/Ultra-FineWeb
- openbmb/UltraX-Preview
- openbmb/Ultra-FineWeb-L3
- openbmb/UltraData-Math
- openbmb/UltraData-Code
- openbmb/UltraData-SFT-2605
- openbmb/UltraData-SFT-Agent-2609
- openbmb/UltraData-RL-2609
This is a decensored version of openbmb/MiniCPM5-2B, made using Heretic v1.4.0
[!TIP]
This model is reproducible!See the README in the
reproducedirectory for more information.
Abliteration parameters
| Parameter | Value |
|---|---|
| direction_index | per layer |
| attn.o_proj.max_weight | 1.49 |
| attn.o_proj.max_weight_position | 27.60 |
| attn.o_proj.min_weight | 1.28 |
| attn.o_proj.min_weight_distance | 11.63 |
| mlp.down_proj.max_weight | 1.15 |
| mlp.down_proj.max_weight_position | 27.60 |
| mlp.down_proj.min_weight | 1.10 |
| mlp.down_proj.min_weight_distance | 13.80 |
Performance
| Metric | This model | Original model (openbmb/MiniCPM5-2B) |
|---|---|---|
| KL divergence | 0.0424 | 0 (by definition) |
| Refusals | 7/100 | 99/100 |
MiniCPM Tech Report | MiniCPM Wiki(Chinese) | GitHub Repo | UltraData | Online Demo
English | 中文
Highlights
We are releasing MiniCPM5-2B, the second model in the MiniCPM5 series, following MiniCPM5-1B. It is a dense 2B Transformer that scales up the same training recipe, built for on-device, local deployment, and resource-constrained scenarios, reaching 2B-class open-source SOTA.
🏆 2B-class open-source SOTA: compared with strong open-source models of similar size, MiniCPM5-2B achieves SOTA performance within this comparison set. It remains competitive with 4B-class models overall, while showing its advantages over models of comparable size in coding, mathematics, long-context understanding, tool use, and agentic tasks.
📂 Open High-Quality Data: Alongside the model, we are releasing the high-quality training datasets behind it as part of the UltraData family: UltraX, a high-quality web pre-training dataset; UltraData-Code, featuring L0–L3 tiered code data management to drive a significant leap in coding capabilities; UltraData-SFT-Agent-2609, comprising 500K agent training samples to enhance comprehensive on-device agent capabilities; and UltraData-RL-2609, with 80K+ high-quality RL training samples covering mathematics, code, general knowledge, and long-context reasoning.
Model List
Use this directory to choose the model format that matches your runtime:
MiniCPM5-2B
- MiniCPM5-2B · ModelScope · BF16 final release (post-trained with RL + OPD) 👈 you are here
- MiniCPM5-2B-SFT · ModelScope · BF16 SFT-only checkpoint (before RL / OPD)
- MiniCPM5-2B-Midtrain · ModelScope · BF16 mid-training checkpoint (before SFT)
- MiniCPM5-2B-Base · ModelScope · BF16 base checkpoint (pre-training only)
- MiniCPM5-2B-GGUF · ModelScope · GGUF for llama.cpp / Ollama / LM Studio
- MiniCPM5-2B-MLX · ModelScope · MLX / 4bit for Apple Silicon
- MiniCPM5-2B-GPTQ · ModelScope · GPTQ / 4bit quantized model
- MiniCPM5-2B-DSpark · ModelScope · DSpark draft model for inference acceleration
MiniCPM5-1B
- MiniCPM5-1B · ModelScope · BF16 final release (post-trained with RL + OPD)
- MiniCPM5-1B-SFT · ModelScope · BF16 SFT-only checkpoint (before RL / OPD)
- MiniCPM5-1B-Base · ModelScope · BF16 base checkpoint (pre-training only)
- MiniCPM5-1B-GGUF · ModelScope · GGUF for llama.cpp / Ollama / LM Studio
- MiniCPM5-1B-MLX · ModelScope · MLX / 4bit for Apple Silicon
Model Information
MiniCPM5-2B has the following features:
- Type: Causal Language Model
- Architecture: Standard
LlamaForCausalLM - Number of Parameters: 2,516,756,480
- Number of Non-Embedding Parameters: 1,981,982,720
- Number of Layers: 42
- Number of Attention Heads (GQA): 16 for Q and 2 for KV
- Context Length: 131,072
Introduction
MiniCPM5-2B is the second model in the MiniCPM5 series. It is designed for local assistants, coding agents, tool-use workflows, and reasoning scenarios where a compact model is preferred. The model keeps a small deployment footprint while providing native long-context support.
Evaluation Results
We compare MiniCPM5-2B with strong open-source models in the same size class, including LFM2.5-2.6B, Qwen3.5-2B, and Gemma-4-E2B-it, while also listing larger models such as Qwen3.5-4B, granite-4.2-3B, Nemotron-3-Nano-4B, Gemma-4-E4B-it, and LFM2.5-8B-A1B for reference.
Within this comparison set, MiniCPM5-2B reaches 2B-class open-source SOTA with an average score of 53.9, and also exceeds all of the larger models included here (the highest is 51.1). Its advantages are most visible in code reasoning, math reasoning, long-context understanding, tool use, and multiple agentic tasks.
Evaluation Results of MiniCPM5-2B and Baselines
| MiniCPM5-2B | 2B-class Models | 4B-class Models | |||||||
|---|---|---|---|---|---|---|---|---|---|
| LFM2.5-2.6B | Qwen3.5-2B | Gemma-4-E2B-it | Qwen3.5-4B | granite-4.2-3B | Nemotron-3-Nano-4B | Gemma-4-E4B-it | LFM2.5-8B-A1B | ||
Average | 53.9 | 33.2 | 28.0 | 24.6 | 51.1 | 42.7 | 32.6 | 31.2 | 28.4 |
| Code Reasoning | |||||||||
LiveCodeBench v6 | 69.1 | 42.1 | 20.2 | 42.9 | 56.4 | 58.9 | 50.7 | 53.9 | 39.8 |
LCB-Pro 25Q2 (Easy) | 68.0 | 30.9 | 10.3 | 27.1 | 58.3 | 54.6 | 51.6 | 45.8 | 27.8 |
LCB-Pro 25Q2 (Medium) | 17.5 | 0.0 | 0.0 | 0.0 | 7.0 | 5.3 | 5.3 | 1.8 | 0.0 |
OJBench | 32.5 | 11.2 | 2.6 | 11.6 | 24.8 | 21.8 | 20.0 | 19.0 | 8.2 |
SciCode (wbg) | 26.3† | 14.2† | 2.8† | 20.9† | 16.1† | 24.9† | 16.4† | 24.4† | 7.8† |
| Math Reasoning | |||||||||
AIME 2025 | 86.5 | 41.9 | 29.6 | 31.7 | 78.8 | 79.4 | 56.3 | 37.1 | 46.0 |
AIME 2026 | 86.5 | 45.2 | 29.0 | 39.8 | 82.7 | 83.5 | 62.1 | 45.0 | 56.7 |
HMMT Feb 2026 | 63.8 | 33.7 | 20.5 | 17.8 | 64.0 | 60.8 | 51.3 | 30.1 | 38.5 |
MATH-500 | 94.6 | 89.6 | 85.8 | 85.4 | 99.0 | 97.0 | 91.6 | 88.2 | 93.2 |
| Instruction Following | |||||||||
IFBench | 66.3 | 59.0 | 46.0 | 25.7 | 59.0 | 73.0 | 58.3 | 28.3 | 51.0 |
IFEval | 86.7 | 93.4 | 77.5 | 31.4 | 90.2 | 93.7 | 88.0 | 44.4 | 90.8 |
Multi-IF | 71.8 | 76.8 | 57.1 | 40.3 | 73.6 | 75.9 | 65.9 | 45.9 | 71.4 |
| General Knowledge | |||||||||
MMLU-Pro | 70.8 | 65.2 | 64.3 | 56.0 | 78.0 | 65.8 | 65.7 | 68.3 | 63.1 |
MMLU-Redux | 84.7 | 80.0 | 80.0 | 71.8 | 88.7 | 78.9 | 79.8 | 83.7 | 80.0 |
HLE | 8.9† | 6.2† | 2.6† | 4.8† | 9.9† | 6.6† | 4.9† | 3.8† | 6.9† |
GPQA-Diamond | 70.2† | 55.8† | 45.6† | 43.3† | 77.1† | 55.9† | 51.3† | 57.6† | 51.3† |
SuperGPQA | 40.8 | 26.2 | 38.6 | 30.3 | 52.8 | 39.9 | 37.8 | 38.7 | 34.5 |
| Long Context | |||||||||
AA-LCR | 59.0† | 5.3† | 28.7† | 17.0† | 61.0† | 24.3† | 17.3† | 33.0† | 0.0† |
NoLiMa | 68.1 | 0.7 | 17.1 | 3.9 | 43.5 | 5.1 | 1.1 | 2.3 | 0.5 |
LongBenchPro | 44.8 | 23.7 | 8.2 | 42.2 | 58.4 | 34.8 | 27.9 | 53.5 | 19.6 |
LongBench v2 | 43.7 | 30.3 | 24.9 | 33.2 | 47.3 | 36.0 | 32.0 | 42.7 | 30.4 |
| Tool Use | |||||||||
τ³-Bench Banking | 20.8† | 7.2† | 2.1 | 3.9 | 6.8† | 5.6† | 1.2 | 4.1 | 3.4 |
τ²-Bench Telecom | 97.1 | 90.4 | 69.0† | 20.8† | 92.1† | 40.9 | 28.1† | 20.8† | 16.1† |
BFCL v4 | 66.6 | 61.1 | 43.6 | 36.6 | 56.8 | 52.2 | 43.7 | 47.0 | 49.2 |
| Coding Agent | |||||||||
SWE-bench Verified | 46.4 | 6.0 | 5.0 | 2.0 | 33.6 | 36.8 | 3.0 | 15.0 | 0.4 |
SWE-bench Pro | 14.4 | 0.6 | 0.8 | 0.0 | 28.2 | 12.3 | 0.1 | 3.3 | 0.4 |
Terminal-Bench v2.1 | 8.6† | 4.5† | 3.0† | 0.4† | 25.8† | 13.9† | 3.8† | 1.9† | 1.9 |
| Search Agent | |||||||||
BrowseComp-ZH | 43.5 | 9.8 | 18.2 | 4.7 | 39.6 | 21.1 | 3.3 | 7.0 | 13.2 |
BrowseComp Top100 | 39.7 | 13.7 | 19.3 | 6.0 | 33.3 | 19.0 | 4.7 | 6.3 | 9.7 |
GAIA Text-103 | 88.7 | 49.5 | 47.9 | 30.1 | 78.6 | 57.3 | 26.5 | 39.5 | 41.1 |
| General Agent | |||||||||
GDPval-AA v2 | 19.6† | 4.5 | 0.0 | 0.0 | 11.7 | 0.0† | 0.0 | 0.0 | 0.0 |
Claw-Gym | 59.2 | 19.3 | 25.5 | 31.3 | 51.6 | 60.0 | 33.7 | 37.9 | 2.7 |
WildClaw | 23.9 | 10.2 | 9.2 | 8.9 | 17.0 | 20.0 | 8.9 | 14.3 | 4.5 |
QwenClaw | 42.9 | 19.3 | 18.2 | 14.5 | 37.1 | 36.4 | 16.8 | 16.7 | 4.5 |
1. Blue bold indicates the best result across all models in the row (including 4B-class models); Black bold indicates the best result among 2B-class models.
2. Scores marked † come from the official Artificial Analysis release; all others are reproduced internally.
Training Recipe
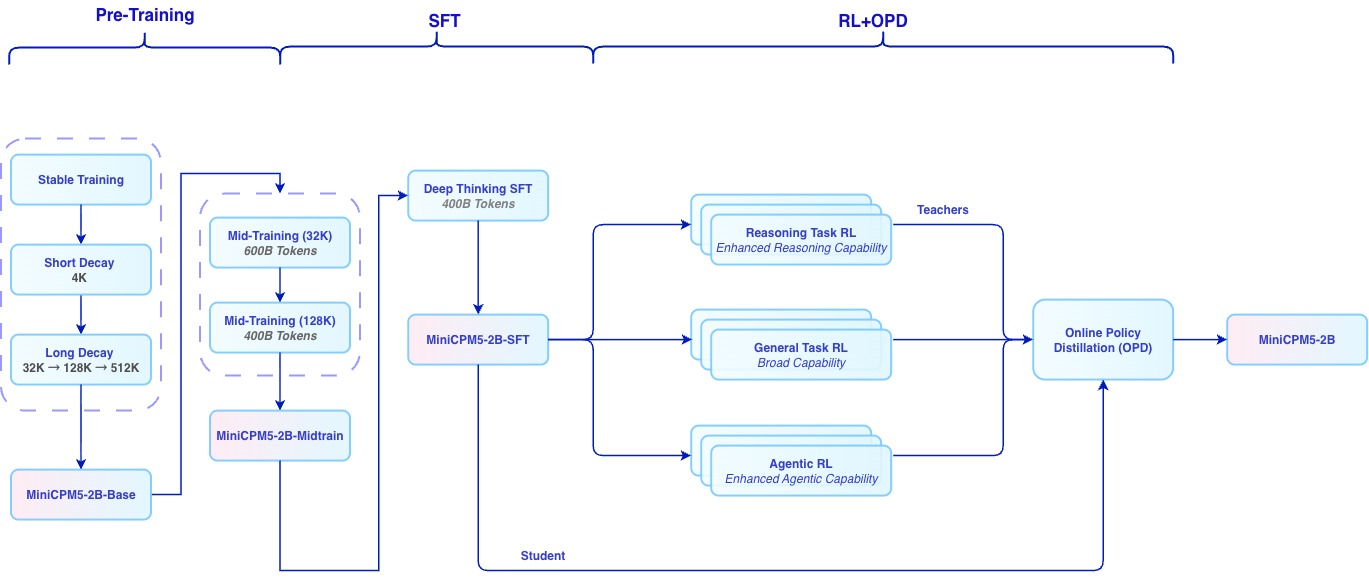
The training of MiniCPM5-2B is a full-stack practice of UltraData Tiered Data Management, covering three stages: base training, mid-training, and post-training.
During base training, the model goes through stable training and decay training to build core language capability and training stability. It then enters mid-training to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as Ultra-FineWeb, Ultra-FineWeb-L3, UltraX, UltraData-Code and UltraData-Math.
During post-training, we proceed in three steps: SFT, RL, and OPD. We first use 400B tokens of deep-thinking SFT to establish deep-thinking and general chat abilities; the SFT data is released as UltraData-SFT-2605 and the Agent SFT data is released as UltraData-SFT-Agent-2609. We then train specialized RL teachers for math, code, agentic tasks, writing, and related domains (with the corresponding data also open-sourced as UltraData-RL-2609), and use On-Policy Distillation (OPD) to distill these teachers back into one release model.
What does RL + OPD bring?
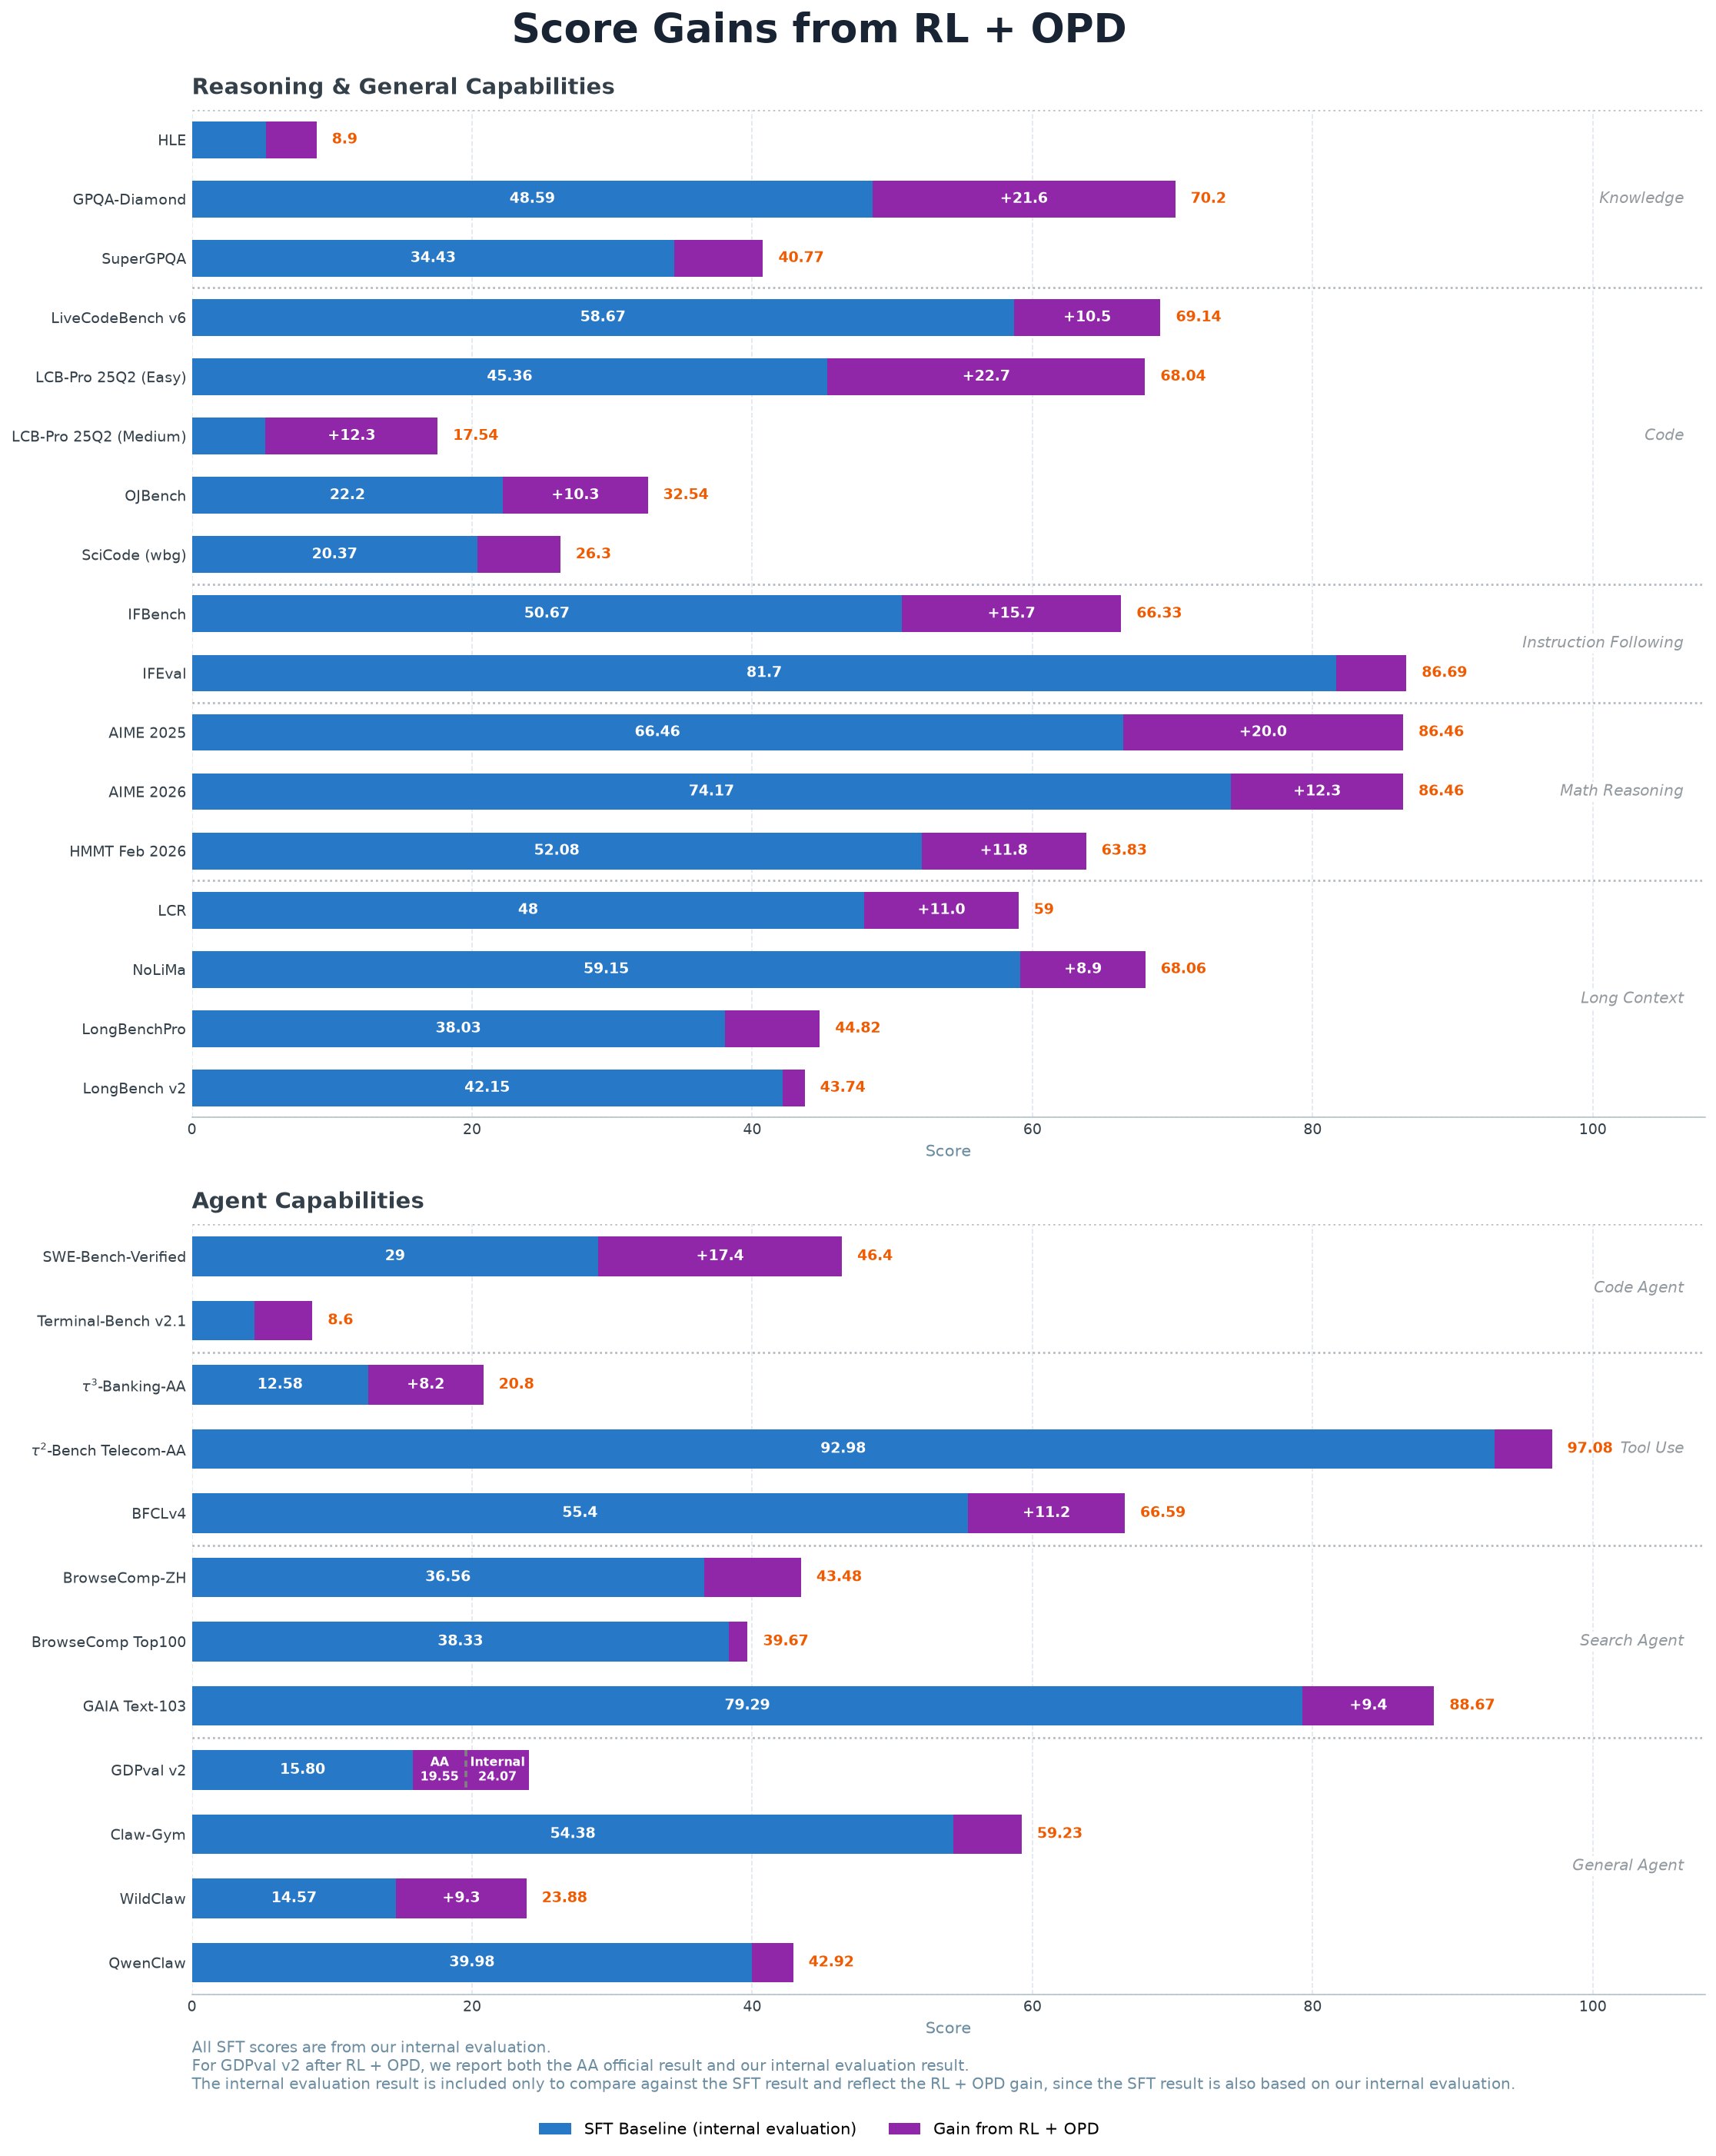
RL + OPD is a key part of MiniCPM5-2B post-training. During the RL stage, we adopted the critic-based algorithm described in JustRL II, substantially improving training stability and achieving significant gains across multiple domains. On the benchmarks listed below, RL + OPD improves reasoning and general capabilities by an average of ↑10.96 points, and agentic capabilities by ↑6.96 points.
OPD merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
Quickstart
vLLM
pip install "vllm>=0.21"
vllm serve openbmb/MiniCPM5-2B --port 8000
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openbmb/MiniCPM5-2B",
    "messages": [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}],
    "max_tokens": 128,
    "temperature": 1.0
  }'
SGLang
pip install "sglang[srt]>=0.5.16"
python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000
curl http://localhost:30000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openbmb/MiniCPM5-2B",
    "messages": [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}],
    "max_tokens": 128,
    "temperature": 1.0
  }'
Speculative decoding (DSpark): we also release MiniCPM5-2B-DSpark, a DSpark draft model trained for MiniCPM5-2B. Enable it in SGLang to accelerate decoding while keeping the target model's outputs unchanged:
python -m sglang.launch_server \
  --model-path openbmb/MiniCPM5-2B \
  --trust-remote-code \
  --speculative-algorithm DSPARK \
  --speculative-draft-model-path openbmb/MiniCPM5-2B-DSpark \
  --speculative-dspark-block-size 7 \
  --port 30000
Transformers
pip install -U "transformers>=5.6" accelerate torch
from transformers import AutoModelForCausalLM, AutoTokenizer
model_id = "openbmb/MiniCPM5-2B"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype="auto",
    device_map="auto",
)
messages = [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}]
inputs = tokenizer.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    enable_thinking=True,
    return_dict=True,
    return_tensors="pt",
).to(model.device)
outputs = model.generate(**inputs, max_new_tokens=128)
print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:], skip_special_tokens=True))
Recommended sampling params: temperature=1.0, top_p=0.95
Tool Calling
For tool / function calling, SGLang is the recommended backend. MiniCPM5-2B emits XML-style tool calls and SGLang's built-in minicpm5 parser converts them to OpenAI-compatible tool_calls natively:
python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000 \
    --tool-call-parser minicpm5      # or: --tool-call-parser auto
GitHub Cookbooks and Agent Skills
MiniCPM5-2B uses the standard LlamaForCausalLM architecture, so mainstream inference engines can load it directly: no custom kernels, no model-code fork. For step-by-step deployment and fine-tuning instructions, use the GitHub cookbooks below. Agent Skills are linked as GitHub resources for users working with Cursor / Claude Code style coding agents.
Deployment
| Backend | Model format / use case | Cookbook | Agent Skill |
|---|---|---|---|
| Transformers | BF16 / FP16 local Python inference, GPU + CPU | transformers.md | minicpm5-deploy-transformers |
| vLLM | BF16 / FP16 OpenAI server | vllm.md | minicpm5-deploy-vllm |
| SGLang | BF16 / FP16 OpenAI server, recommended for tool calling | sglang.md | minicpm5-deploy-sglang |
| llama.cpp | GGUF local inference, CPU/GPU | llama_cpp.md | minicpm5-deploy-llama-cpp |
| Ollama | GGUF local on-device runtime | ollama.md | minicpm5-deploy-ollama |
| LM Studio | GGUF Mac desktop app and OpenAI server | lmstudio.md | minicpm5-deploy-lmstudio |
| MLX | MLX / 4bit local inference on Apple Silicon | mlx.md | minicpm5-deploy-mlx |
| ArcLight | GGUF local on-device, CPU, Desktop & Server | arclight.md | minicpm5-deploy-arclight |
| vLLM Ascend | BF16 / FP16 OpenAI server | vllm_ascend.md | minicpm5-deploy-vllm-ascend |
Fine-tuning
| Framework | Use case | Cookbook | Agent Skill |
|---|---|---|---|
| TRL + PEFT | LoRA / SFT fine-tuning | trl.md | minicpm5-finetune-trl |
| LLaMA-Factory | Fine-tuning | llamafactory.md | minicpm5-finetune-llamafactory |
| ms-swift | Fine-tuning | ms_swift.md | minicpm5-finetune-ms-swift |
| unsloth | Fine-tuning | unsloth.md | minicpm5-finetune-unsloth |
Other Supported Frameworks
In addition to the deployment and fine-tuning frameworks listed above, MiniCPM5-2B is also supported by FlagOS for multi-chip deployment.
FlagOS Overview
To enable large-scale deployment across different AI chips, Beijing Zhiyuan Research Institute, together with numerous research institutions, chip manufacturers, system vendors, and algorithm and software organizations both domestically and internationally, jointly initiated and established the FlagOS Open Source Community.
The FlagOS community is dedicated to building a unified, open-source system software stack for various AI chips, encompassing core open-source projects such as a large-scale operator library, a unified AI compiler, parallel training and inference frameworks, and a unified communication library. It aims to create an open technology ecosystem connecting the “model-system-chip” layers. By enabling “develop once, deploy across chips”, FlagOS unlocks the computational potential of hardware, breaks down the ecosystem silos between different chip software stacks, and effectively reduces migration costs for developers.The FlagOS community fosters an AI hardware and software ecosystem, overcomes single-vendor closed-source monopolies, promotes widespread deployment of AI hardware technologies, and is committed to rooted in China while embracing global collaboration.
Official website express: https://flagos.io
FlagOS multi-chip support and usage
FlagOS: Supporting Multiple AI Chips
Thanks to FlagOS’s unified multi-chip AI system software stack, MiniCPM5-2B was adapted to 9 different AI chips in an extremely short time. Currently, the multi-chip version of MiniCPM5-2B has been released on FlagRelease, FlagOS’s platform for automatic migration, adaptation, and deployment of large models across multi-architecture AI chips. Details are as follows:
| Vendor | ModelScope | Huggingface |
|---|---|---|
| Nvidia | MiniCPM5-2B-nvidia-FlagOS | MiniCPM5-2B-nvidia-FlagOS |
| Hygon | MiniCPM5-2B-hygon-FlagOS | MiniCPM5-2B-hygon-FlagOS |
| Metax | MiniCPM5-2B-metax-FlagOS | MiniCPM5-2B-metax-FlagOS |
| Iluvatar | MiniCPM5-2B-iluvatar-FlagOS | MiniCPM5-2B-iluvatar-FlagOS |
| Zhenwu | MiniCPM5-2B-zhenwu-FlagOS | MiniCPM5-2B-zhenwu-FlagOS |
| Mthreads | MiniCPM5-2B-mthreads-FlagOS | MiniCPM5-2B-mthreads-FlagOS |
| Kunlunxin | MiniCPM5-2B-kunlunxin-FlagOS | MiniCPM5-2B-kunlunxin-FlagOS |
| Ascend | MiniCPM5-2B-ascend-FlagOS | MiniCPM5-2B-ascend-FlagOS |
| ARM-v9 | MiniCPM5-2B-Armv9-FlagOS | MiniCPM5-2B-Armv9-FlagOS |
FlagOS Usage
FlagOS Performance Acceleration on Nvidia
From FlagRelease (Recommendation)
FlagRelease is a platform developed by the FlagOS team for automatic migration, adaptation, and deployment of large models across multi-architecture AI chips. The multi-chip version of MiniCPM5-2B has already been released on FlagRelease. All necessary software packages are pre-installed on the platform, so users do not need to install anything.
FlagRelease Image Key Versions
FlagRelease Quick Start
| Vendor | ModelScope | Huggingface |
|---|---|---|
| Nvidia | MiniCPM5-2B-nvidia-FlagOS | MiniCPM5-2B-nvidia-FlagOS |
| Hygon | MiniCPM5-2B-hygon-FlagOS | MiniCPM5-2B-hygon-FlagOS |
| Metax | MiniCPM5-2B-metax-FlagOS | MiniCPM5-2B-metax-FlagOS |
| Iluvatar | MiniCPM5-2B-iluvatar-FlagOS | MiniCPM5-2B-iluvatar-FlagOS |
| Zhenwu | MiniCPM5-2B-zhenwu-FlagOS | MiniCPM5-2B-zhenwu-FlagOS |
| Mthreads | MiniCPM5-2B-mthreads-FlagOS | MiniCPM5-2B-mthreads-FlagOS |
| Kunlunxin | MiniCPM5-2B-kunlunxin-FlagOS | MiniCPM5-2B-kunlunxin-FlagOS |
| Ascend | MiniCPM5-2B-ascend-FlagOS | MiniCPM5-2B-ascend-FlagOS |
| ARM-v9 | MiniCPM5-2B-Armv9-FlagOS | MiniCPM5-2B-Armv9-FlagOS |
From Scratch
- Dependencies: Python 3.12, GLIBC 2.39, GLIBCXX 3.4.33, CXXABI 1.3.15
Vllm Version
Installing the FlagOS Operator Library
Official Repository: https://github.com/flagos-ai/FlagGems
pip install flag-gems==4.2.1rc0
pip install triton==3.5.1
Activating Acceleration
You can enable flagGems acceleration by adding the import of flagGems in the source code of vllm where inference is performed.
import flag_gems
flag_gems.enable(record=True, once=True, path="/root/gems.txt")
vllm serve ${model_path} \
--trust-remote-code \
--dtype bfloat16 \
--enforce-eager \
--port ${Port} \
--served-model-name ${model_name} \
--gpu-memory-utilization 0.85
Using FlagOS Unified Multi-Chip Backend Plugin
vllm-plugin-FL is a plugin built for the vLLM inference/service framework. Developed on top of FlagOS’s unified multi-chip backend, it is designed to extend vLLM’s capabilities and performance across a variety of hardware environments.
Using vllm-plugin-FL
| Vendor | From Scratch | From FlagRelease | |
|---|---|---|---|
| Nvidia | vllm-plugin-FL/MiniCPM5-2B | MiniCPM5-2B-ModelScope | MiniCPM5-2B-nvidia-FlagOS |
Limitations and Disclaimer
This model has no autonomous intent or legal personhood; its outputs are text generated from statistical patterns and may be inaccurate, biased, or offensive, and may be manipulated by carefully crafted prompts ("jailbreaks") into producing unintended content. Its responses on sensitive topics such as politics, health, finance, and law are not reviewed by experts and should not be treated as professional advice.
This model is provided "AS IS", without warranty of any kind, express or implied, and the developers are not liable for any damages arising from its use. Users must employ the model only for lawful, compliant, and ethical purposes, configure their own safeguards, and label AI-generated content where required; deliberate jailbreaking, injection attacks, or inducing harmful output is prohibited, and any such testing is at the user's own risk.
License
This repository and MiniCPM model weights are released under the Apache-2.0 License.
Citation
Please cite our paper if you find our work valuable:
@article{minicpm4,
  title={Minicpm4: Ultra-efficient llms on end devices},
  author={MiniCPM, Team},
  journal={arXiv preprint arXiv:2506.07900},
  year={2025}
}