library_name: transformers
license: apache-2.0
license_link: https://huggingface.co/Qwen/Qwen3.6-27B/blob/main/LICENSE
pipeline_tag: image-text-to-text
tags:
- qwen3_5
- heretic
- uncensored
- decensored
- abliterated
- mpoa
- mtp
base_model: - llmfan46/Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved
🚨⚠️ I HAVE REACHED HUGGING FACE'S FREE STORAGE LIMIT ⚠️🚨
I can no longer upload new models unless I can cover the cost of additional storage.
I host 70+ free models as an independent contributor and this work is unpaid.
Without your support, no more new models can be uploaded.
🎉 Patreon (Monthly) | ☕ Ko-fi (One-time)
Every contribution goes directly toward Hugging Face storage fees to keep models free for everyone.
This is the full model with the 15 MTPs all intacts.
94% fewer refusals (6/100 Uncensored vs 92/100 Original) while preserving model quality (0.0021 KL divergence).
❤️ Support My Work
Creating these models takes significant time, work and compute. If you find them useful consider supporting me:

| Platform | Link | What you get |
|---|---|---|
| 🎉 Patreon | Monthly support | Priority model requests |
| ☕ Ko-fi | One-time tip | My eternal gratitude |
Your help will motivate me and would go into further improving my workflow and coverings fees for storage, compute and may even help uncensoring bigger model with rental Cloud GPUs.
GGUF quantizations of llmfan46/Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved.
This is a decensored version of Qwen/Qwen3.6-27B, made using Heretic v1.3.0 with a variant of the Magnitude-Preserving Orthogonal Ablation (MPOA) method
Preserved MTPs:
Original Model:
MTP count: 15
- mtp.fc.weight
- mtp.layers.0.mlp.down_proj.weight
- mtp.layers.0.mlp.gate_proj.weight
- mtp.layers.0.mlp.up_proj.weight
- mtp.layers.0.self_attn.k_proj.weight
- mtp.layers.0.self_attn.q_proj.weight
- mtp.layers.0.self_attn.v_proj.weight
- mtp.layers.0.input_layernorm.weight
- mtp.layers.0.post_attention_layernorm.weight
- mtp.layers.0.self_attn.k_norm.weight
- mtp.layers.0.self_attn.o_proj.weight
- mtp.layers.0.self_attn.q_norm.weight
- mtp.norm.weight
- mtp.pre_fc_norm_embedding.weight
- mtp.pre_fc_norm_hidden.weight
Heretic Model:
MTP count: 15
- mtp.fc.weight
- mtp.layers.0.input_layernorm.weight
- mtp.layers.0.mlp.down_proj.weight
- mtp.layers.0.mlp.gate_proj.weight
- mtp.layers.0.mlp.up_proj.weight
- mtp.layers.0.post_attention_layernorm.weight
- mtp.layers.0.self_attn.k_norm.weight
- mtp.layers.0.self_attn.k_proj.weight
- mtp.layers.0.self_attn.o_proj.weight
- mtp.layers.0.self_attn.q_norm.weight
- mtp.layers.0.self_attn.q_proj.weight
- mtp.layers.0.self_attn.v_proj.weight
- mtp.norm.weight
- mtp.pre_fc_norm_embedding.weight
- mtp.pre_fc_norm_hidden.weight
Abliteration parameters
| Parameter | Value |
|---|---|
| direction_index | 30.38 |
| attn.out_proj.max_weight | 1.58 |
| attn.out_proj.max_weight_position | 38.93 |
| attn.out_proj.min_weight | 1.51 |
| attn.out_proj.min_weight_distance | 32.78 |
| mlp.down_proj.max_weight | 1.80 |
| mlp.down_proj.max_weight_position | 41.28 |
| mlp.down_proj.min_weight | 0.54 |
| mlp.down_proj.min_weight_distance | 43.66 |
| attn.o_proj.max_weight | 1.99 |
| attn.o_proj.max_weight_position | 48.06 |
| attn.o_proj.min_weight | 1.75 |
| attn.o_proj.min_weight_distance | 39.00 |
Targeted components
- attn.o_proj
- attn.out_proj
- mlp.down_proj
Performance
| Metric | This model | Original model (Qwen3.6-27B) |
|---|---|---|
| KL divergence | 0.0021 | 0 (by definition) |
| Refusals | ✅ 6/100 | ❌ 92/100 |
Lower refusals indicate fewer content restrictions, while lower KL divergence indicates more closeness to the original model's baseline. Higher refusals cause more rejections, objections, pushbacks, lecturing, censorship, softening and deflections.
MMLU test results:
Original:
============================================================
Total questions: 7021
Correct: 6084
Accuracy: 0.8665 (86.65%)
Parse failures: 0
============================================================
Tested subject scores:
- professional_law: 0.7580 (595/785)
- moral_scenarios: 0.7715 (341/442)
- miscellaneous: 0.9399 (360/383)
- professional_psychology: 0.8987 (284/316)
- high_school_psychology: 0.9704 (262/270)
- high_school_macroeconomics: 0.9289 (183/197)
- elementary_mathematics: 0.8967 (165/184)
- moral_disputes: 0.8621 (150/174)
- prehistory: 0.8953 (154/172)
- philosophy: 0.8868 (141/159)
- high_school_biology: 0.9539 (145/152)
- professional_accounting: 0.8531 (122/143)
- clinical_knowledge: 0.9071 (127/140)
- high_school_microeconomics: 0.9706 (132/136)
- nutrition: 0.9111 (123/135)
- professional_medicine: 0.9478 (127/134)
- conceptual_physics: 0.9141 (117/128)
- high_school_mathematics: 0.6378 (81/127)
- human_aging: 0.8190 (95/116)
- security_studies: 0.9107 (102/112)
- high_school_statistics: 0.9009 (100/111)
- marketing: 0.9633 (105/109)
- high_school_world_history: 0.9623 (102/106)
- sociology: 0.9417 (97/103)
- high_school_government_and_politics: 0.9802 (99/101)
- high_school_geography: 0.9697 (96/99)
- high_school_chemistry: 0.8041 (78/97)
- high_school_us_history: 0.9895 (94/95)
- virology: 0.5506 (49/89)
- college_medicine: 0.8409 (74/88)
- world_religions: 0.9091 (80/88)
- high_school_physics: 0.8571 (72/84)
- electrical_engineering: 0.8642 (70/81)
- astronomy: 0.9747 (77/79)
- logical_fallacies: 0.9342 (71/76)
- high_school_european_history: 0.9452 (69/73)
- anatomy: 0.8169 (58/71)
- college_biology: 0.9375 (60/64)
- human_sexuality: 0.8906 (57/64)
- formal_logic: 0.7969 (51/64)
- public_relations: 0.7377 (45/61)
- international_law: 0.9000 (54/60)
- college_physics: 0.7719 (44/57)
- college_mathematics: 0.7636 (42/55)
- econometrics: 0.7963 (43/54)
- jurisprudence: 0.9057 (48/53)
- high_school_computer_science: 0.9615 (50/52)
- machine_learning: 0.8269 (43/52)
- medical_genetics: 0.9412 (48/51)
- global_facts: 0.6275 (32/51)
- management: 0.9000 (45/50)
- us_foreign_policy: 0.9600 (48/50)
- college_chemistry: 0.7021 (33/47)
- abstract_algebra: 0.7021 (33/47)
- business_ethics: 0.8261 (38/46)
- college_computer_science: 0.8222 (37/45)
- computer_security: 0.8372 (36/43)
Heretic:
============================================================
Total questions: 7021
Correct: 6015
Accuracy: 0.8567 (85.67%)
Parse failures: 0
============================================================
Tested subject scores:
- professional_law: 0.7146 (561/785)
- moral_scenarios: 0.7466 (331/442)
- miscellaneous: 0.9347 (361/383)
- professional_psychology: 0.9019 (284/316)
- high_school_psychology: 0.9704 (262/270)
- high_school_macroeconomics: 0.9391 (185/197)
- elementary_mathematics: 0.8967 (164/184)
- moral_disputes: 0.8621 (149/174)
- prehistory: 0.8779 (151/172)
- philosophy: 0.8931 (141/159)
- high_school_biology: 0.9539 (144/152)
- professional_accounting: 0.8182 (118/143)
- clinical_knowledge: 0.9143 (128/140)
- high_school_microeconomics: 0.9706 (132/136)
- nutrition: 0.8815 (120/135)
- professional_medicine: 0.9478 (127/134)
- conceptual_physics: 0.9141 (117/128)
- high_school_mathematics: 0.6299 (82/127)
- human_aging: 0.8103 (94/116)
- security_studies: 0.8661 (97/112)
- high_school_statistics: 0.8829 (98/111)
- marketing: 0.9633 (105/109)
- high_school_world_history: 0.9528 (101/106)
- sociology: 0.9417 (97/103)
- high_school_government_and_politics: 0.9604 (97/101)
- high_school_geography: 0.9697 (96/99)
- high_school_chemistry: 0.8041 (77/97)
- high_school_us_history: 0.9474 (90/95)
- virology: 0.5281 (47/89)
- college_medicine: 0.8523 (75/88)
- world_religions: 0.9205 (81/88)
- high_school_physics: 0.8571 (73/84)
- electrical_engineering: 0.8395 (69/81)
- astronomy: 0.9747 (77/79)
- logical_fallacies: 0.9342 (71/76)
- high_school_european_history: 0.9452 (69/73)
- anatomy: 0.8169 (58/71)
- college_biology: 0.9531 (61/64)
- human_sexuality: 0.8750 (56/64)
- formal_logic: 0.7812 (50/64)
- public_relations: 0.7377 (45/61)
- international_law: 0.9167 (55/60)
- college_physics: 0.8070 (46/57)
- college_mathematics: 0.7455 (40/55)
- econometrics: 0.8333 (45/54)
- jurisprudence: 0.8868 (47/53)
- high_school_computer_science: 0.9615 (50/52)
- machine_learning: 0.7692 (40/52)
- medical_genetics: 0.9412 (48/51)
- global_facts: 0.6471 (33/51)
- management: 0.9000 (45/50)
- us_foreign_policy: 0.9800 (49/50)
- college_chemistry: 0.6596 (31/47)
- abstract_algebra: 0.7021 (33/47)
- business_ethics: 0.7826 (37/46)
- college_computer_science: 0.8444 (38/45)
- computer_security: 0.8605 (37/43)
MMLU - Massive Multitask Language Understanding, multiple-choice questions across 57 subjects (math, history, law, medicine, etc.).
Quantizations
For the K-quants below, small SSM tensors are kept at higher precision where useful.
-Q6_K keeps ssm_alpha, ssm_beta, and ssm_out as Q8_0.
-Q5_K, Q4_K, and Q3_K quants keep ssm_alpha and ssm_beta as Q8_0, while ssm_out is kept as Q6_K.
This helps preserve the hybrid/SSM blocks with a small file-size increase.
| Filename | Quant | Description |
|---|---|---|
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-BF16.gguf | BF16 | Full precision |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q8_0.gguf | Q8_0 | Near-lossless, recommended |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q6_K.gguf | Q6_K | Excellent quality |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q5_K_M.gguf | Q5_K_M | Good balance |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q5_K_S.gguf | Q5_K_S | Smaller Q5 |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q4_K_M.gguf | Q4_K_M | Good for limited VRAM |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q4_K_S.gguf | Q4_K_S | Smaller Q4 |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q3_K_L.gguf | Q3_K_L | Low VRAM, decent quality |
| Qwen3.6-27B-uncensored-heretic-v2-Native-MTP-Preserved-Q3_K_M.gguf | Q3_K_M | Low VRAM, smaller |
Vision Projector
| Filename | Quant | Description |
|---|---|---|
| Qwen3.6-27B-mmproj-BF16.gguf | BF16 | Native precision |
A Vision Projector File is Required for vision/multimodal capabilities. Use alongside any quantization above.
Usage
Works with llama.cpp, LM Studio, Ollama, and other GGUF-compatible tools.
Qwen3.6-27B

[!Note]
This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
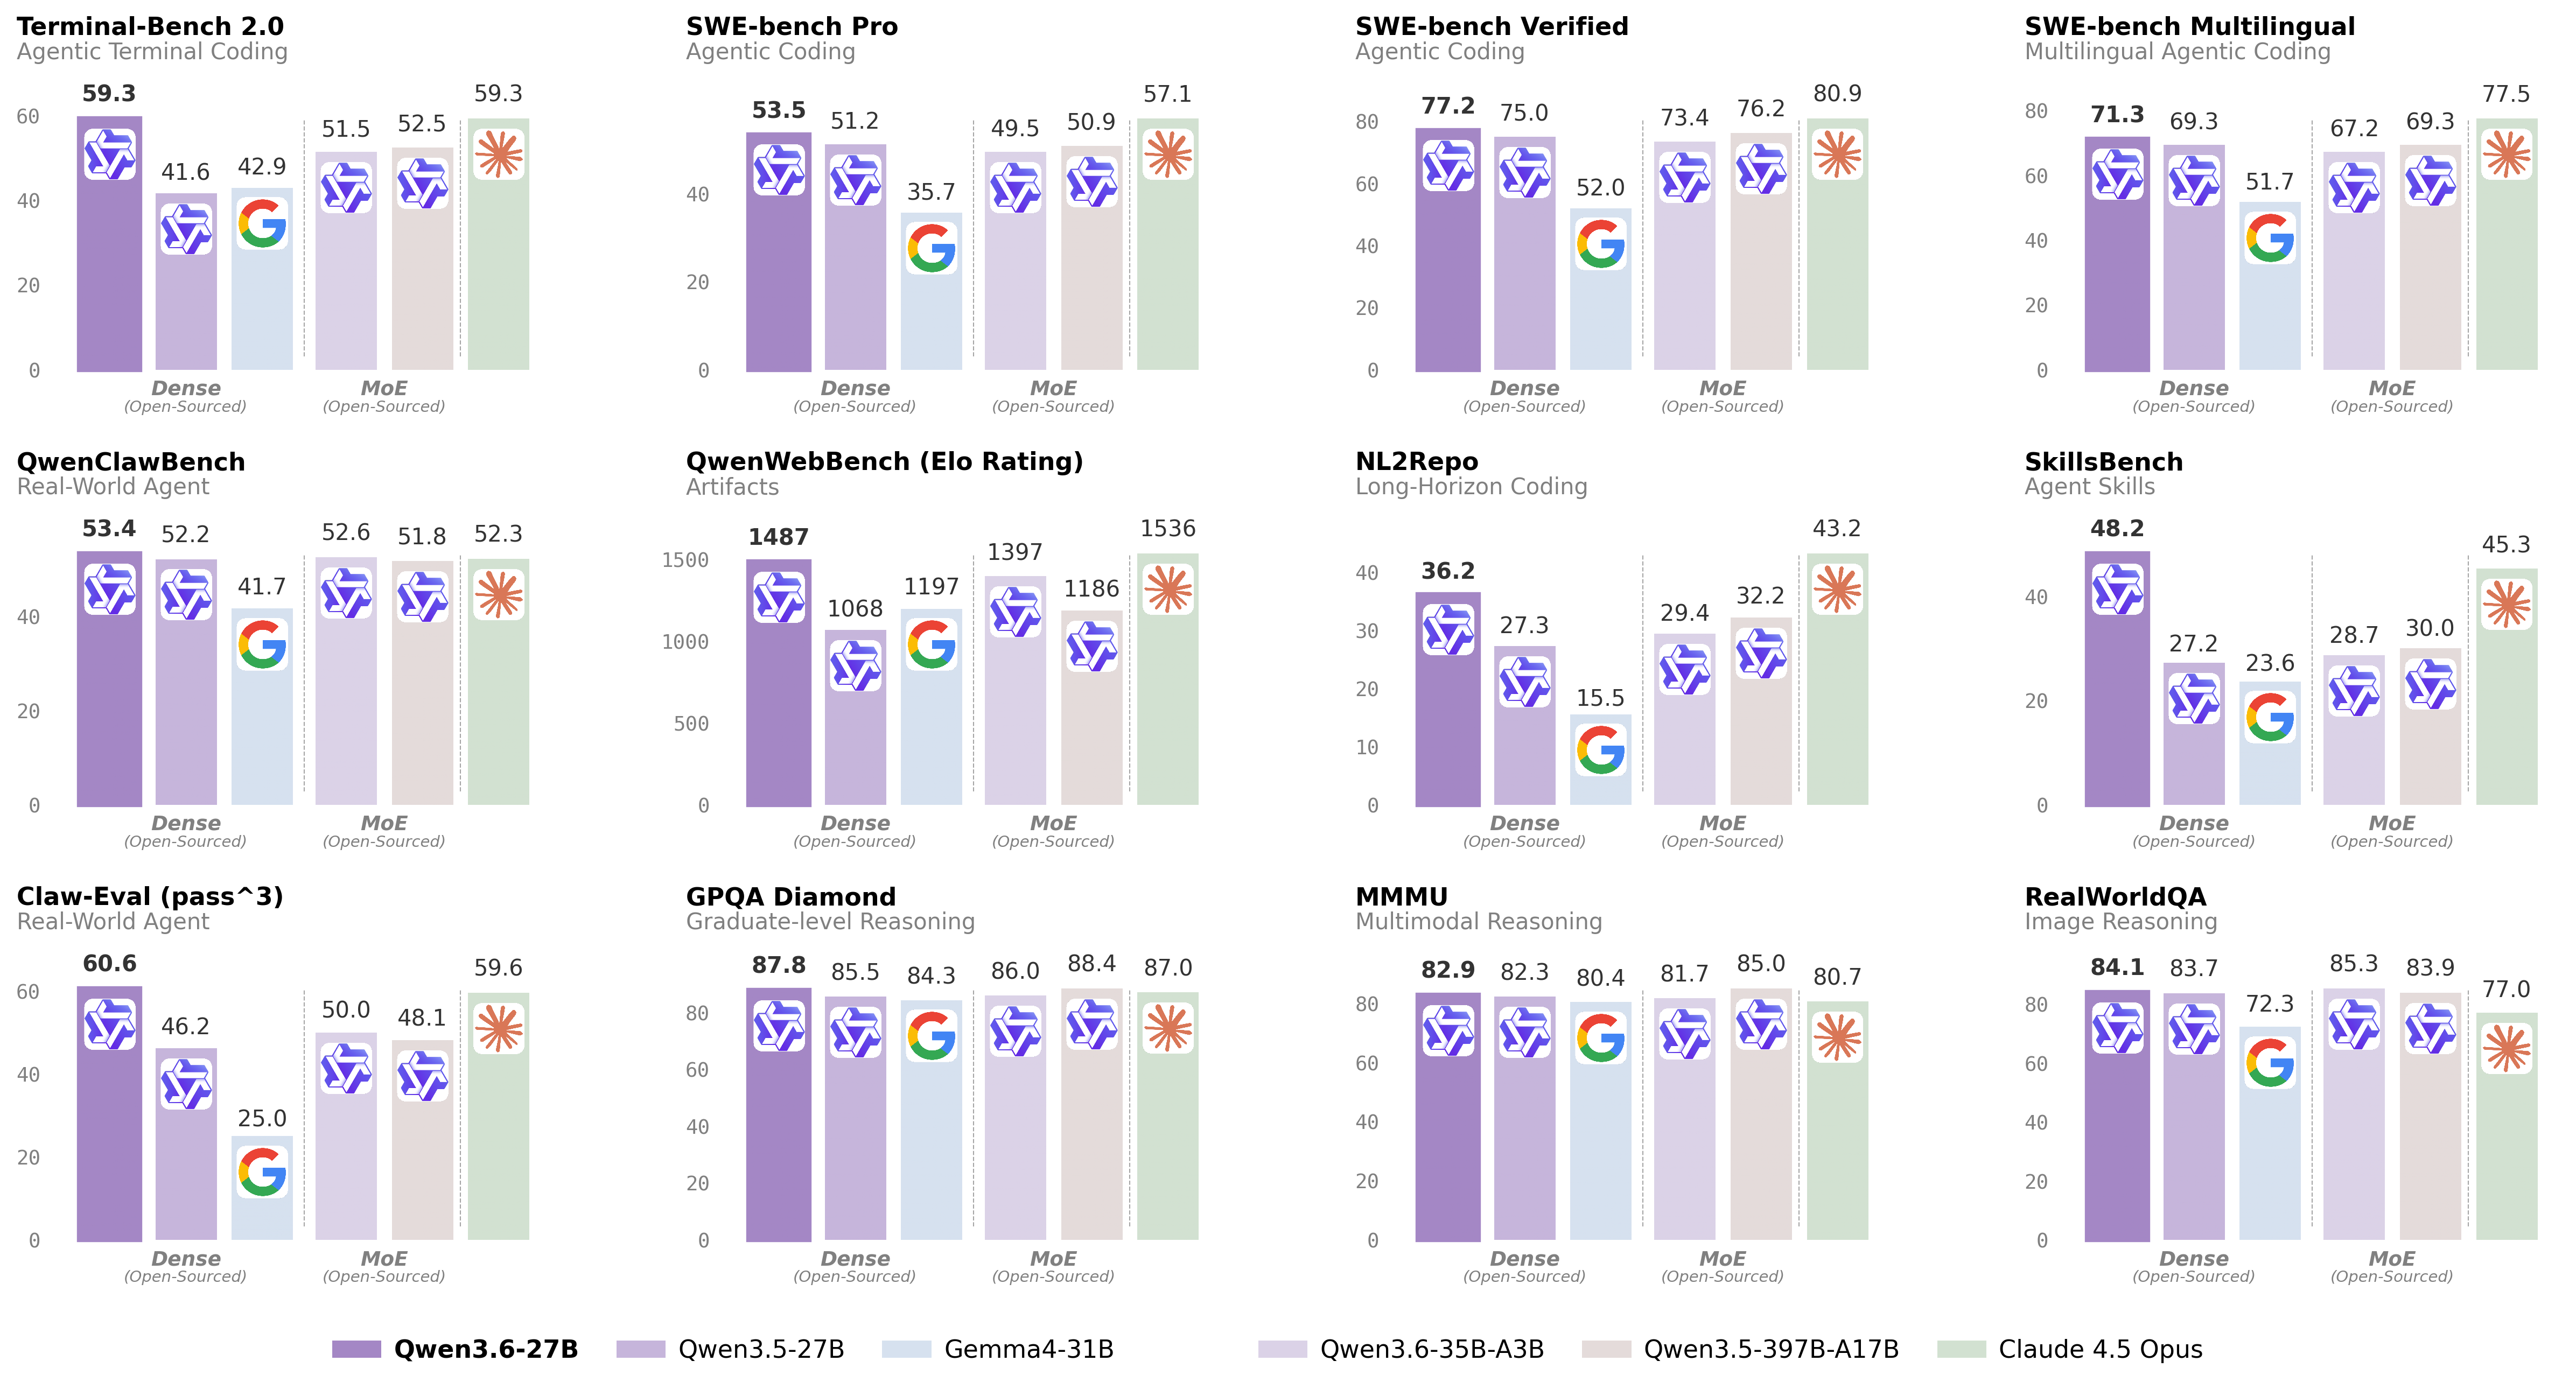
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post Qwen3.6-27B.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 27B
- Hidden Dimension: 5120
- Token Embedding: 248320 (Padded)
- Number of Layers: 64
- Hidden Layout: 16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 24 for Q and 4 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Feed Forward Network:
- Intermediate Dimension: 17408
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
Benchmark Results
Language
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| Coding Agent | ||||||
| SWE-bench Verified | 75.0 | 76.2 | 52.0 | 80.9 | 73.4 | 77.2 |
| SWE-bench Pro | 51.2 | 50.9 | 35.7 | 57.1 | 49.5 | 53.5 |
| SWE-bench Multilingual | 69.3 | 69.3 | 51.7 | 77.5 | 67.2 | 71.3 |
| Terminal-Bench 2.0 | 41.6 | 52.5 | 42.9 | 59.3 | 51.5 | 59.3 |
| SkillsBench Avg5 | 27.2 | 30.0 | 23.6 | 45.3 | 28.7 | 48.2 |
| QwenWebBench | 1068 | 1186 | 1197 | 1536 | 1397 | 1487 |
| NL2Repo | 27.3 | 32.2 | 15.5 | 43.2 | 29.4 | 36.2 |
| Claw-Eval Avg | 64.3 | 70.7 | 48.5 | 76.6 | 68.7 | 72.4 |
| Claw-Eval Pass^3 | 46.2 | 48.1 | 25.0 | 59.6 | 50.0 | 60.6 |
| QwenClawBench | 52.2 | 51.8 | 41.7 | 52.3 | 52.6 | 53.4 |
| Knowledge | ||||||
| MMLU-Pro | 86.1 | 87.8 | 85.2 | 89.5 | 85.2 | 86.2 |
| MMLU-Redux | 93.2 | 94.9 | 93.7 | 95.6 | 93.3 | 93.5 |
| SuperGPQA | 65.6 | 70.4 | 65.7 | 70.6 | 64.7 | 66.0 |
| C-Eval | 90.5 | 93.0 | 82.6 | 92.2 | 90.0 | 91.4 |
| STEM & Reasoning | ||||||
| GPQA Diamond | 85.5 | 88.4 | 84.3 | 87.0 | 86.0 | 87.8 |
| HLE | 24.3 | 28.7 | 19.5 | 30.8 | 21.4 | 24.0 |
| LiveCodeBench v6 | 80.7 | 83.6 | 80.0 | 84.8 | 80.4 | 83.9 |
| HMMT Feb 25 | 92.0 | 94.8 | 88.7 | 92.9 | 90.7 | 93.8 |
| HMMT Nov 25 | 89.8 | 92.7 | 87.5 | 93.3 | 89.1 | 90.7 |
| HMMT Feb 26 | 84.3 | 87.9 | 77.2 | 85.3 | 83.6 | 84.3 |
| IMOAnswerBench | 79.9 | 80.9 | 74.5 | 84.0 | 78.9 | 80.8 |
| AIME26 | 92.6 | 93.3 | 89.2 | 95.1 | 92.7 | 94.1 |
* SWE-Bench Series: Internal agent scaffold (bash + file-edit tools); temp=1.0, top_p=0.95, 200K context window. We correct some problematic tasks in the public set of SWE-bench Pro and evaluate all baselines on the refined benchmark.
* Terminal-Bench 2.0: Harbor/Terminus-2 harness; 3h timeout, 32 CPU/48 GB RAM; temp=1.0, top_p=0.95, top_k=20, max_tokens=80K, 256K ctx; avg of 5 runs.
* SkillsBench: Evaluated via OpenCode on 78 tasks (self-contained subset, excluding API-dependent tasks); avg of 5 runs.
* NL2Repo: Others are evaluated via Claude Code (temp=1.0, top_p=0.95, max_turns=900).
* QwenClawBench: A real-user-distribution Claw agent benchmark; temp=0.6, 256K ctx.
* QwenWebBench: An internal front-end code generation benchmark; bilingual (EN/CN), 7 categories (Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D); auto-render + multimodal judge (code/visual correctness); BT/Elo rating system.
* AIME 26: We use the full AIME 2026 (I & II), where the scores may differ from Qwen 3.5 notes.
Vision Language
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| STEM & Puzzle | ||||||
| MMMU | 82.3 | 85.0 | 80.4 | 80.7 | 81.7 | 82.9 |
| MMMU-Pro | 75.0 | 79.0 | 76.9 | 70.6 | 75.3 | 75.8 |
| MathVista mini | 87.8 | -- | 79.3 | -- | 86.4 | 87.4 |
| DynaMath | 87.7 | 86.3 | 79.5 | 79.7 | 82.8 | 85.6 |
| VlmsAreBlind | 96.9 | -- | 87.2 | -- | 96.6 | 97.0 |
| General VQA | ||||||
| RealWorldQA | 83.7 | 83.9 | 72.3 | 77.0 | 85.3 | 84.1 |
| MMStar | 81.0 | 83.8 | 77.3 | 73.2 | 80.7 | 81.4 |
| MMBenchEN-DEV-v1.1 | 92.6 | -- | 90.9 | -- | 92.8 | 92.3 |
| SimpleVQA | 56.0 | 67.1 | 52.9 | 65.7 | 58.9 | 56.1 |
| Document Understanding | ||||||
| CharXiv RQ | 79.5 | 80.8 | 67.9 | 68.5 | 78.0 | 78.4 |
| CC-OCR | 81.0 | 82.0 | 75.7 | 76.9 | 81.9 | 81.2 |
| OCRBench | 89.4 | -- | 86.1 | -- | 90.0 | 89.4 |
| Spatial Intelligence | ||||||
| ERQA | 60.5 | 67.5 | 57.5 | 46.8 | 61.8 | 62.5 |
| CountBench | 97.8 | 97.2 | 96.1 | 90.6 | 96.1 | 97.8 |
| RefCOCO avg | 90.9 | 92.3 | -- | -- | 92.0 | 92.5 |
| EmbSpatialBench | 84.5 | -- | -- | -- | 84.3 | 84.6 |
| RefSpatialBench | 67.7 | -- | 4.7 | -- | 64.3 | 70.0 |
| Video Understanding | ||||||
| VideoMME(w sub.) | 87.0 | 87.5 | -- | 77.7 | 86.6 | 87.7 |
| VideoMMMU | 82.3 | 84.7 | 81.6 | 84.4 | 83.7 | 84.4 |
| MLVU | 85.9 | 86.7 | -- | 81.7 | 86.2 | 86.6 |
| MVBench | 74.6 | 77.6 | -- | 67.2 | 74.6 | 75.5 |
| Visual Agent | ||||||
| V* | 93.7 | 95.8 | -- | 67.0 | 90.1 | 94.7 |
| AndroidWorld | 64.2 | -- | -- | -- | -- | 70.3 |
* Empty cells (--) indicate scores not yet available or not applicable.
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks.
In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important]
Inference efficiency and throughput vary significantly across frameworks.
We recommend using the latest framework versions to ensure optimal performance and compatibility.
For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important]
The model has a default context length of 262,144 tokens.
If you encounter out-of-memory (OOM) errors, consider reducing the context window.
However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models.sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install sglang[all]
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3Tool Use: To support tool use, you can use the following command.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coderMulti-Token Prediction (MTP): The following command is recommended for MTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --speculative-algo NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install vllm --torch-backend=auto
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3Tool Call: To support tool use, you can use the following command.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coderMulti-Token Prediction (MTP): The following command is recommended for MTP:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --speculative-config '{"method":"qwen3_next_mtp","num_speculative_tokens":2}'Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --language-model-only
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing.
For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
transformers serve Qwen/Qwen3.6-27B --port 8000 --continuous-batching
Using Qwen3.6 via the Chat Completions API
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs.
Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
pip install -U openai

# Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
[!Tip]
We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Instruct (or non-thinking) mode:
temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0Please note that the support for sampling parameters varies according to inference frameworks.
[!Important]
Qwen3.6 models operate in thinking mode by default, generating thinking content signified by<think>\n...</think>\n\nbefore producing the final responses.
To disable thinking content and obtain direct response, refer to the examples here.
Text-Only Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Type \"I love Qwen3.6\" backwards"},
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Image Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"
                }
            },
            {
                "type": "text",
                "text": "The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$"
            }
        ]
    }
]

response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Video Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "video_url",
                "video_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4"
                }
            },
            {
                "type": "text",
                "text": "How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?"
            }
        ]
    }
]

# When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,
# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).
# This feature is currently supported only in vLLM.
#
# By default, `fps=2` and `do_sample_frames=True`.
# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.
response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
        "mm_processor_kwargs": {"fps": 2, "do_sample_frames": True},
    },
)

print("Chat response:", chat_response)
Instruct (or Non-Thinking) Mode
[!Important]
Qwen3.6 does not officially support the soft switch of Qwen3, i.e.,/thinkand/nothink.
Qwen3.6 will think by default before response.
You can obtain direct response from the model without thinking by configuring the API parameters.
For example,
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.6/demo/RealWorld/RealWorld-04.png"
                }
            },
            {
                "type": "text",
                "text": "Where is this?"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=32768,
    temperature=0.7,
    top_p=0.8,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"enable_thinking": False},
    },
)
print("Chat response:", chat_response)
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changingmodel, please use"enable_thinking": Falseinstead of"chat_template_kwargs": {"enable_thinking": False}.
Preserve Thinking
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [...]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=32768,
    temperature=0.6,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"preserve_thinking": True},
    },
)
print("Chat response:", chat_response)
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changingmodel, please use"preserve_thinking": Trueinstead of"chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
import os
from qwen_agent.agents import Assistant

# Define LLM
# Using Alibaba Cloud Model Studio
llm_cfg = {
    # Use the OpenAI-compatible model service provided by DashScope:
    'model': 'qwen3.6-27b',
    'model_type': 'qwenvl_oai',
    'model_server': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
    'api_key': os.getenv('DASHSCOPE_API_KEY'),

    'generate_cfg': {
        'use_raw_api': True,
        # When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way
        'extra_body': {
            'enable_thinking': True,
            'preserve_thinking': True,
        },
    },
}

# Using OpenAI-compatible API endpoint.
# functionality of the deployment frameworks and let Qwen-Agent automate the related operations.
#
# llm_cfg = {
#     # Use your own model service compatible with OpenAI API by vLLM/SGLang:
#     'model': 'Qwen/Qwen3.6-27B',
#     'model_type': 'qwenvl_oai',
#     'model_server': 'http://localhost:8000/v1',  # api_base
#     'api_key': 'EMPTY',
#
#     'generate_cfg': {
#         'use_raw_api': True,
#         # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way
#         'extra_body': {
#             'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}
#         },
#     },
# }

# Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            "filesystem": {
                "command": "npx",
                "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/xxxx/Desktop"]
            }
        }
    }
]

# Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

# Streaming generation
messages = [{'role': 'user', 'content': 'Help me organize my desktop.'}]
for responses in bot.run(messages=messages):
    pass
print(responses)

# Streaming generation
messages = [{'role': 'user', 'content': 'Develop a dog website and save it on the desktop'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Processing Ultra-Long Texts
Qwen3.6 natively supports context lengths of up to 262,144 tokens.
For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
Modifying the model configuration file:
In theconfig.jsonfile, change therope_parametersfields intext_configto:{ "mrope_interleaved": true, "mrope_section": [ 11, 11, 10 ], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144, }Passing command line arguments:
For
vllm, you can useVLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1010000For
sglangandktransformers, you can useSGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1010000
[!NOTE]
All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts.
We advise modifying therope_parametersconfiguration only when processing long contexts is required.
It is also recommended to modify thefactoras needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to setfactoras 2.0.
Best Practices
To achieve optimal performance, we recommend the following settings:
Sampling Parameters:
- We suggest using the following sets of sampling parameters depending on the mode and task type:
- Thinking mode for general tasks:
temperature=1.0,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Thinking mode for precise coding tasks (e.g., WebDev):
temperature=0.6,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Instruct (or non-thinking) mode:
temperature=0.7,top_p=0.80,top_k=20,min_p=0.0,presence_penalty=1.5,repetition_penalty=1.0
- Thinking mode for general tasks:
- For supported frameworks, you can adjust the
presence_penaltyparameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
- We suggest using the following sets of sampling parameters depending on the mode and task type:
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
- Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the
answerfield with only the choice letter, e.g.,"answer": "C"."
Long Video Understanding: To optimize inference efficiency for plain text and images, the
sizeparameter in the releasedvideo_preprocessor_config.jsonis conservatively configured. It is recommended to set thelongest_edgeparameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,{"longest_edge": 469762048, "shortest_edge": 4096}Alternatively, override the default values via engine startup parameters. For implementation details, refer to: vLLM / SGLang.
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen3.6-27b,
    title  = {{Qwen3.6-27B}: Flagship-Level Coding in a {27B} Dense Model},
    author = {{Qwen Team}},
    month  = {April},
    year   = {2026},
    url    = {https://qwen.ai/blog?id=qwen3.6-27b}
}