language:
- en
- zh
license: apache-2.0
tags: - GLM 4.7 Flash distill
- unsloth
- thinking
- reasoning
- heretic
- uncensored
- abliterated
- thinking
- reasoning
- deep reasoning
- fine tune
- creative
- creative writing
- fiction writing
- plot generation
- sub-plot generation
- fiction writing
- story generation
- scene continue
- storytelling
- fiction story
- science fiction
- romance
- all genres
- story
- writing
- vivid prosing
- vivid writing
- fiction
- roleplaying
- bfloat16
- swearing
- rp
- horror
- r rated
- x rated
- all use cases
- not-for-all-audiences
library_name: transformers
pipeline_tag: image-text-to-text
datasets: - TeichAI/gemini-3-pro-preview-high-reasoning-250x
base_model: - coder3101/Qwen3-VL-32B-Thinking-heretic-v2
Qwen3-VL-32B-Gemini-Heretic-Uncensored-Thinking
Completely uncensored, including image and full on detailed (but compact, and precise) Gemini Pro Preview High thinking/reasoning.
There are no "Qwen thinking traces", as this was a full on "convert" to "Gemini thinking".
Gemini thinking traces are VERY compact - often 4-6 paragraphs or less.
Special care was taken to only use minimal power to "implant" the Gemini thinking, while preserving Qwen's core including functions and metrics.
Training via Unsloth, using Linux for Windows on local hardware.
This model is a beast.
Will generate any kind of content and accept all images types.
For all use cases. No nanny... anywhere.
Reasoning amps up the image analytics, details and output generation.
Reasoning/thinking is TEMP stable too.
The "persona" of this model will also be different from a Qwen too.
Context: 256k.
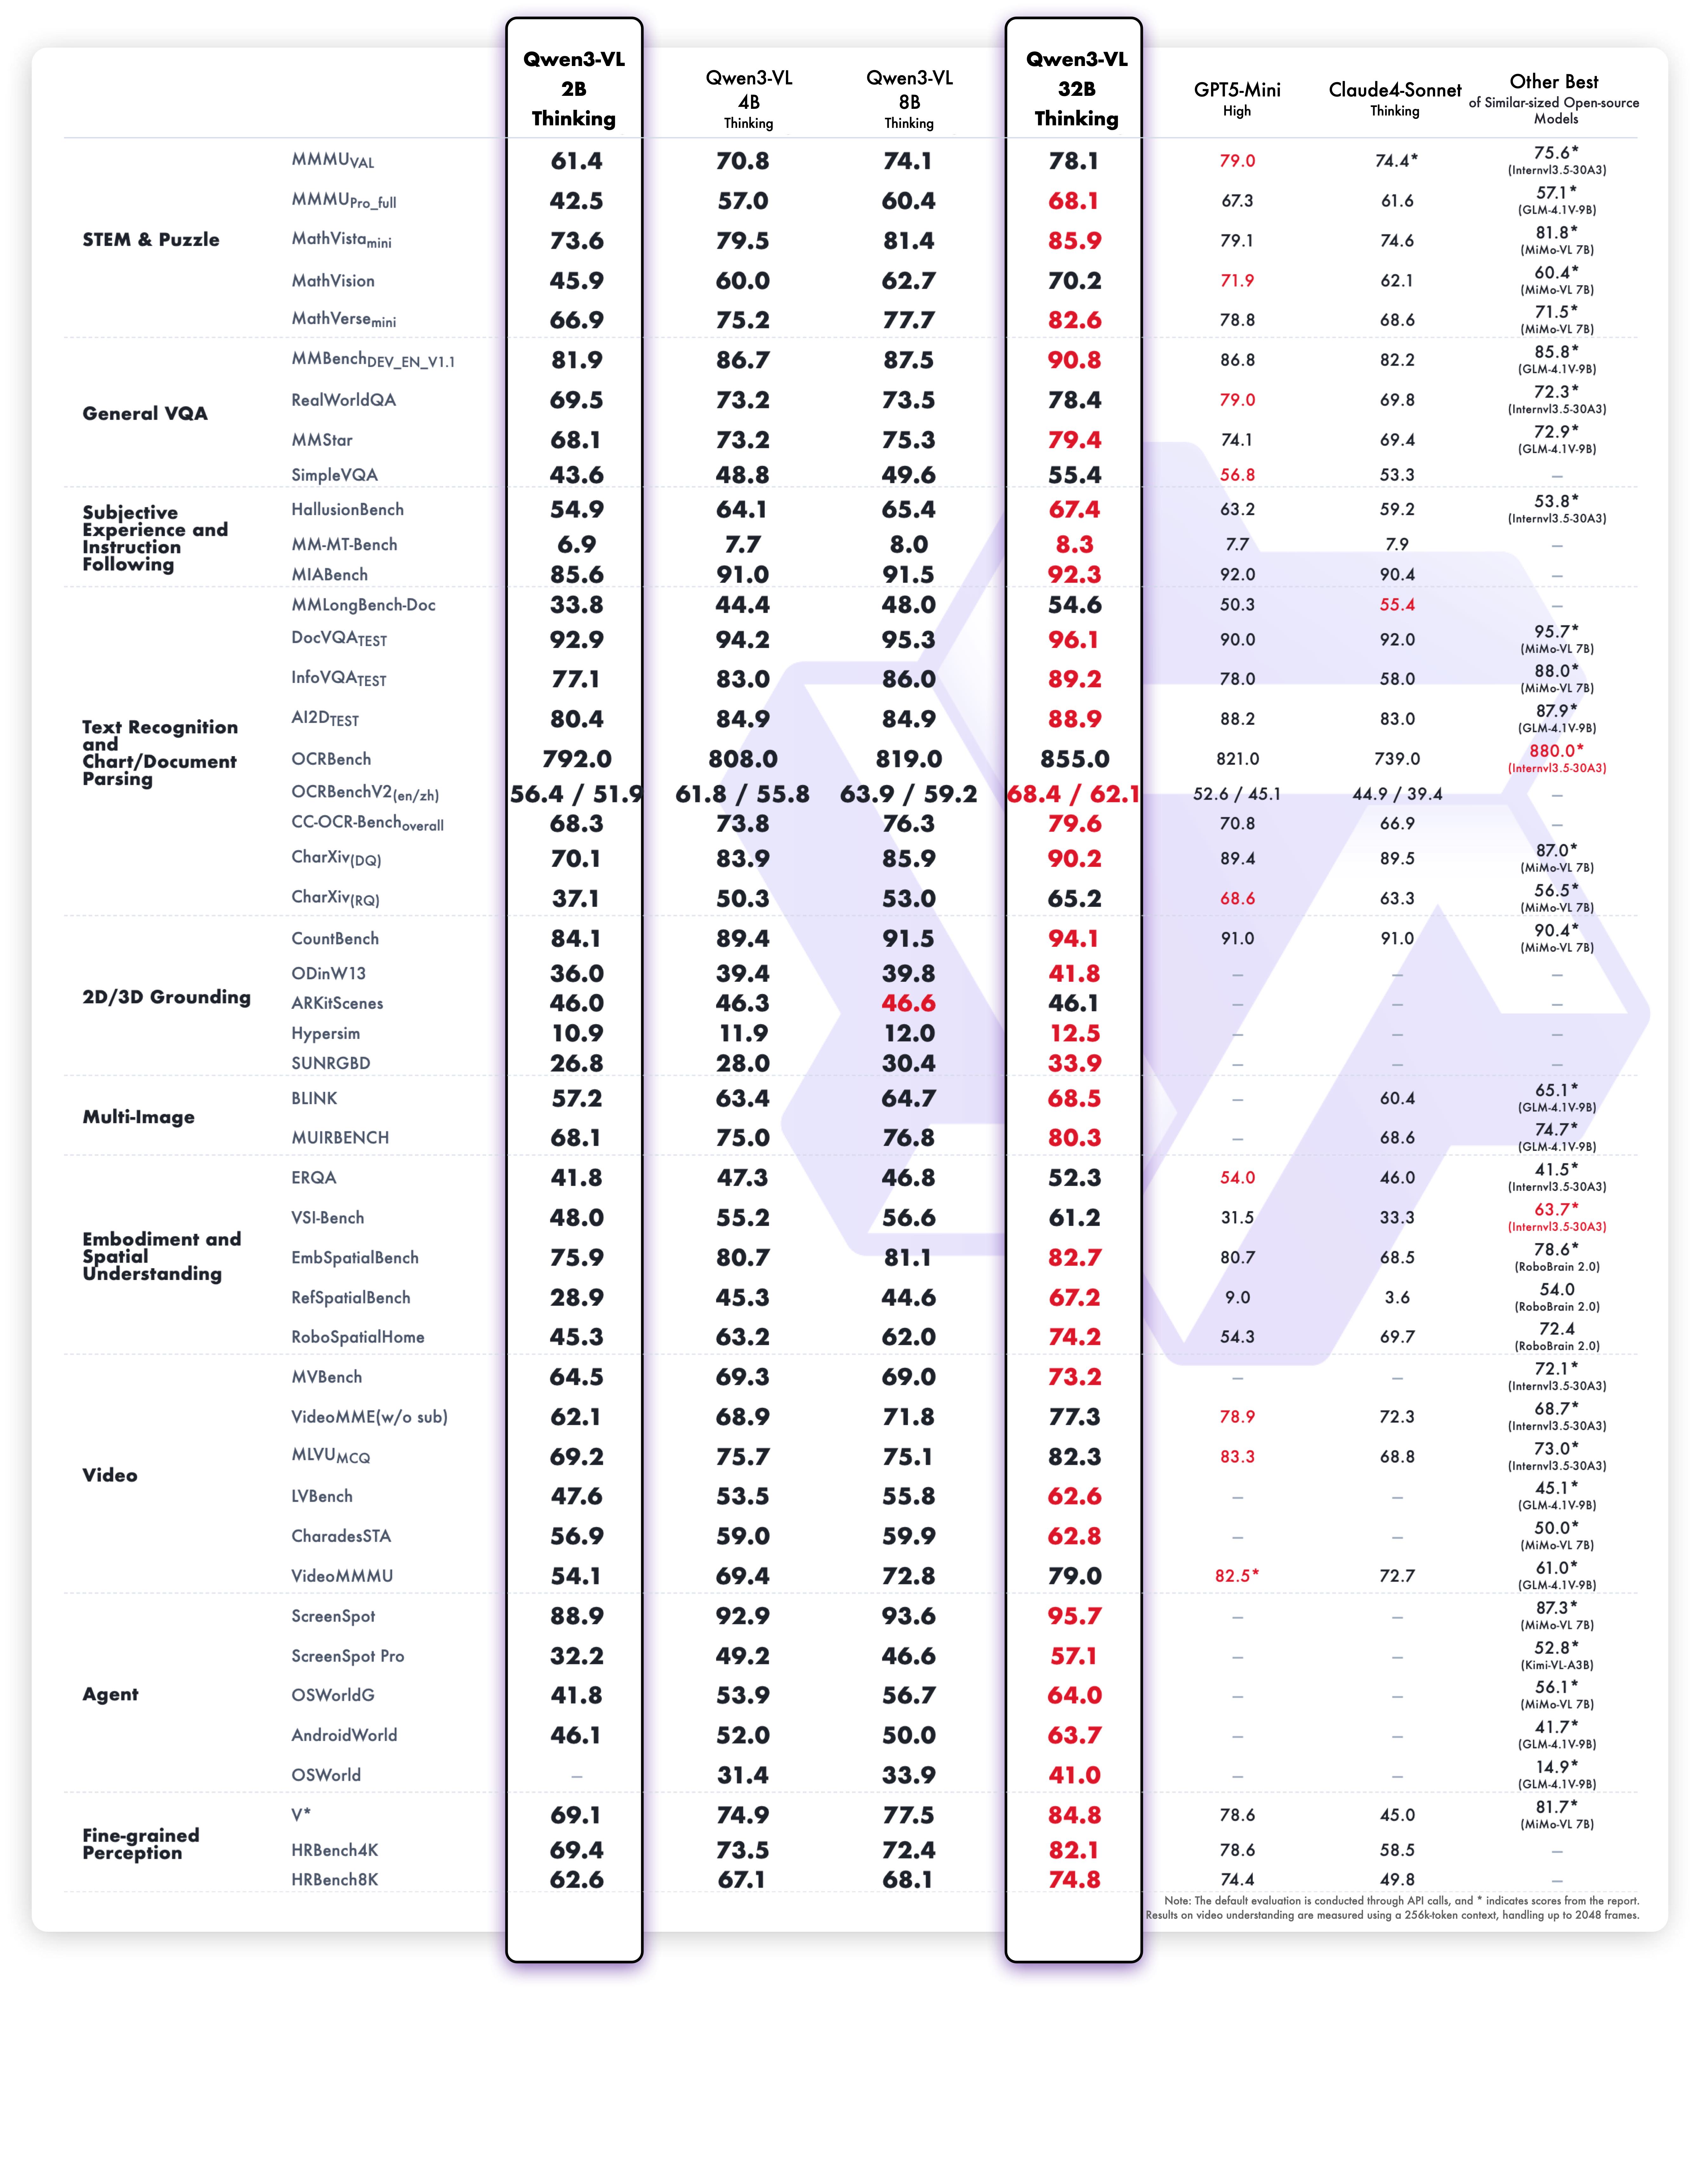
I have added Qwen data/benchmarks for this model below.
NOTE: this is the correct repo info, as the base of this model was Qwen VL-8B Instruct.
HERETIC DE-CENSORING STATS:
| Metric | This model | Original model (Qwen/Qwen3-VL-32B-Thinking) |
|---|---|---|
| KL divergence | 0.0048 | 0 (by definition) |
| Refusals | 3/100 | 97/100 |
KLD: 1 or lower is excellent, zero is perfect (no damage to the model).
Special Thanks to:
- Team "Qwen" for making an excellent model.
- Team "P-E-W" for making Heretic software.
- Team "coder3101" for Heretic'ing the model.
- Team "TeichAI" for the excellent GLM 4.7 Flash Distill dataset.
- Team "Unsloth" for making training the model painless.
- Team "Mradermarcher" for the quants.
From Qwen's repo:
Qwen3-VL-32B-Thinking
Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.
This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.
Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.
Key Enhancements:
Visual Agent: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.
Visual Coding Boost: Generates Draw.io/HTML/CSS/JS from images/videos.
Advanced Spatial Perception: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.
Long Context & Video Understanding: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.
Enhanced Multimodal Reasoning: Excels in STEM/Math—causal analysis and logical, evidence-based answers.
Upgraded Visual Recognition: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.
Expanded OCR: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.
Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension.
Model Architecture Updates:
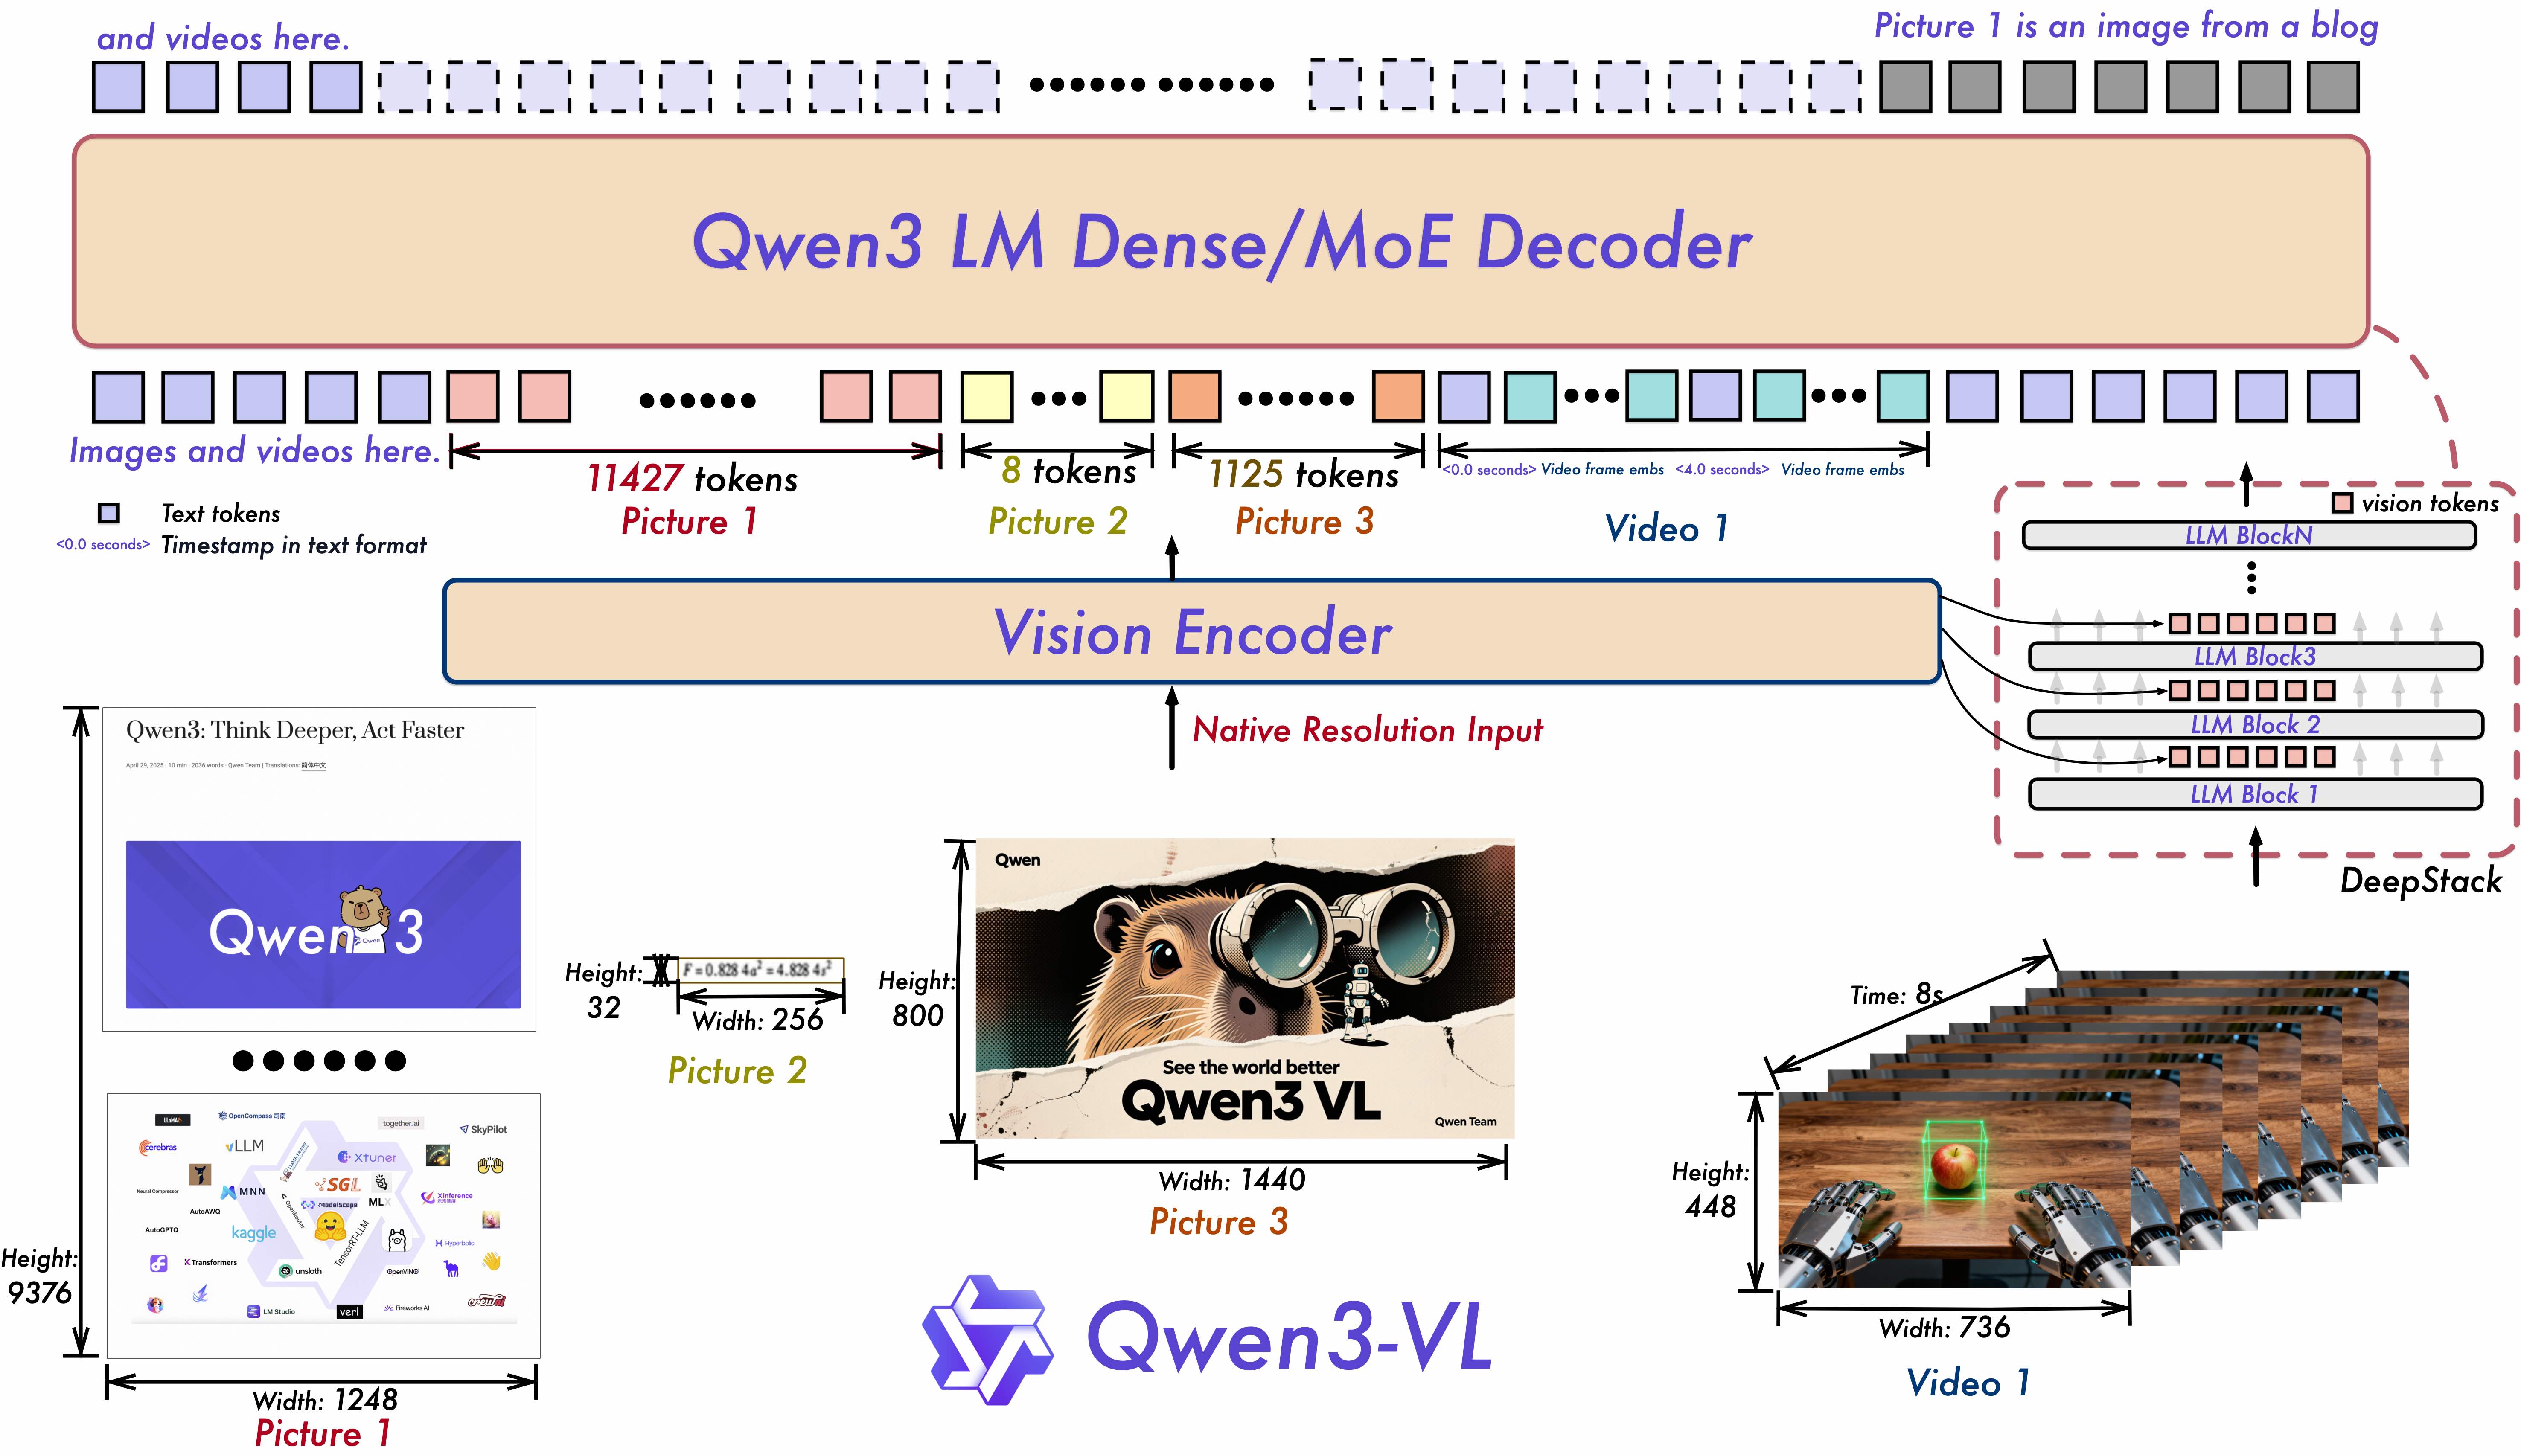
Interleaved-MRoPE: Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning.
DeepStack: Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment.
Text–Timestamp Alignment: Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling.
This is the weight repository for Qwen3-VL-32B-Thinking.
Model Performance
Multimodal performance
Pure text performance
Quickstart
Below, we provide simple examples to show how to use Qwen3-VL with 🤖 ModelScope and 🤗 Transformers.
The code of Qwen3-VL has been in the latest Hugging face transformers and we advise you to build from source with command:
pip install git+https://github.com/huggingface/transformers
# pip install transformers==4.57.0 # currently, V4.57.0 is not released
Using 🤗 Transformers to Chat
Here we show a code snippet to show you how to use the chat model with transformers:
from transformers import Qwen3VLForConditionalGeneration, AutoProcessor

# default: Load the model on the available device(s)
model = Qwen3VLForConditionalGeneration.from_pretrained(
    "Qwen/Qwen3-VL-32B-Thinking", dtype="auto", device_map="auto"
)

# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
# model = Qwen3VLForConditionalGeneration.from_pretrained(
#     "Qwen/Qwen3-VL-32B-Thinking",
#     dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )

processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-32B-Thinking")

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
            },
            {"type": "text", "text": "Describe this image."},
        ],
    }
]

# Preparation for inference
inputs = processor.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    return_dict=True,
    return_tensors="pt"
)
inputs = inputs.to(model.device)

# Inference: Generation of the output
generated_ids = model.generate(**inputs, max_new_tokens=128)
generated_ids_trimmed = [
    out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text)
Generation Hyperparameters
VL
export greedy='false'
export top_p=0.95
export top_k=20
export repetition_penalty=1.0
export presence_penalty=0.0
export temperature=1.0
export out_seq_length=40960
Text
export greedy='false'
export top_p=0.95
export top_k=20
export repetition_penalty=1.0
export presence_penalty=1.5
export temperature=1.0
export out_seq_length=32768 (for aime, lcb, and gpqa, it is recommended to set to 81920)
[ more to come ]