language:
- en
license: mit
size_categories: - 1K<n<10K
task_categories: - text-classification
task_ids: - intent-classification
- multi-class-classification
tags: - jailbreak-detection
- llm-safety
- sparse-autoencoders
- mechanistic-interpretability
- benchmark
- SAE
- activation-probing
- NeurIPS
pretty_name: SAEGuardBench
configs: - config_name: prompts
data_files:- split: jailbreakbench_harmful
path: prompts/jailbreakbench_harmful.parquet - split: jailbreakbench_benign
path: prompts/jailbreakbench_benign.parquet - split: harmbench
path: prompts/harmbench.parquet - split: advbench
path: prompts/advbench.parquet - split: sorry_bench
path: prompts/sorry_bench.parquet - split: wildjailbreak
path: prompts/wildjailbreak.parquet
- split: jailbreakbench_harmful
- config_name: results
data_files:- split: detection
path: results/detection_results.parquet - split: transfer
path: results/transfer_results.parquet - split: hybrid
path: results/hybrid_results.parquet
- split: detection
dataset_info:
- config_name: prompts
features:- name: prompt
dtype: string - name: label
dtype: string - name: source
dtype: string - name: category
dtype: string
- name: prompt
- config_name: results
features:- name: model
dtype: string - name: method
dtype: string - name: dataset
dtype: string - name: auroc_mean
dtype: float64 - name: auroc_std
dtype: float64
- name: model
SAEGuardBench
Do SAE Features Actually Help Detect Jailbreaks? A Systematic Benchmark of Interpretability-Based Safety Methods


Overview
SAEGuardBench is the first systematic benchmark evaluating whether Sparse Autoencoder (SAE) features improve jailbreak detection in large language models. We compare 8 detection methods across 4 paradigms on 6 datasets and 4 models (2B--70B parameters).
This dataset contains:
- Benchmark prompts from 6 jailbreak/safety datasets (3,590+ prompts)
- Structured experiment results (detection accuracy, transfer, hybrid recovery)
- Trained probe checkpoints for all 8 detection methods
- Raw experiment outputs (100+ JSON files with full metadata)
Key Finding: The Detection Gap
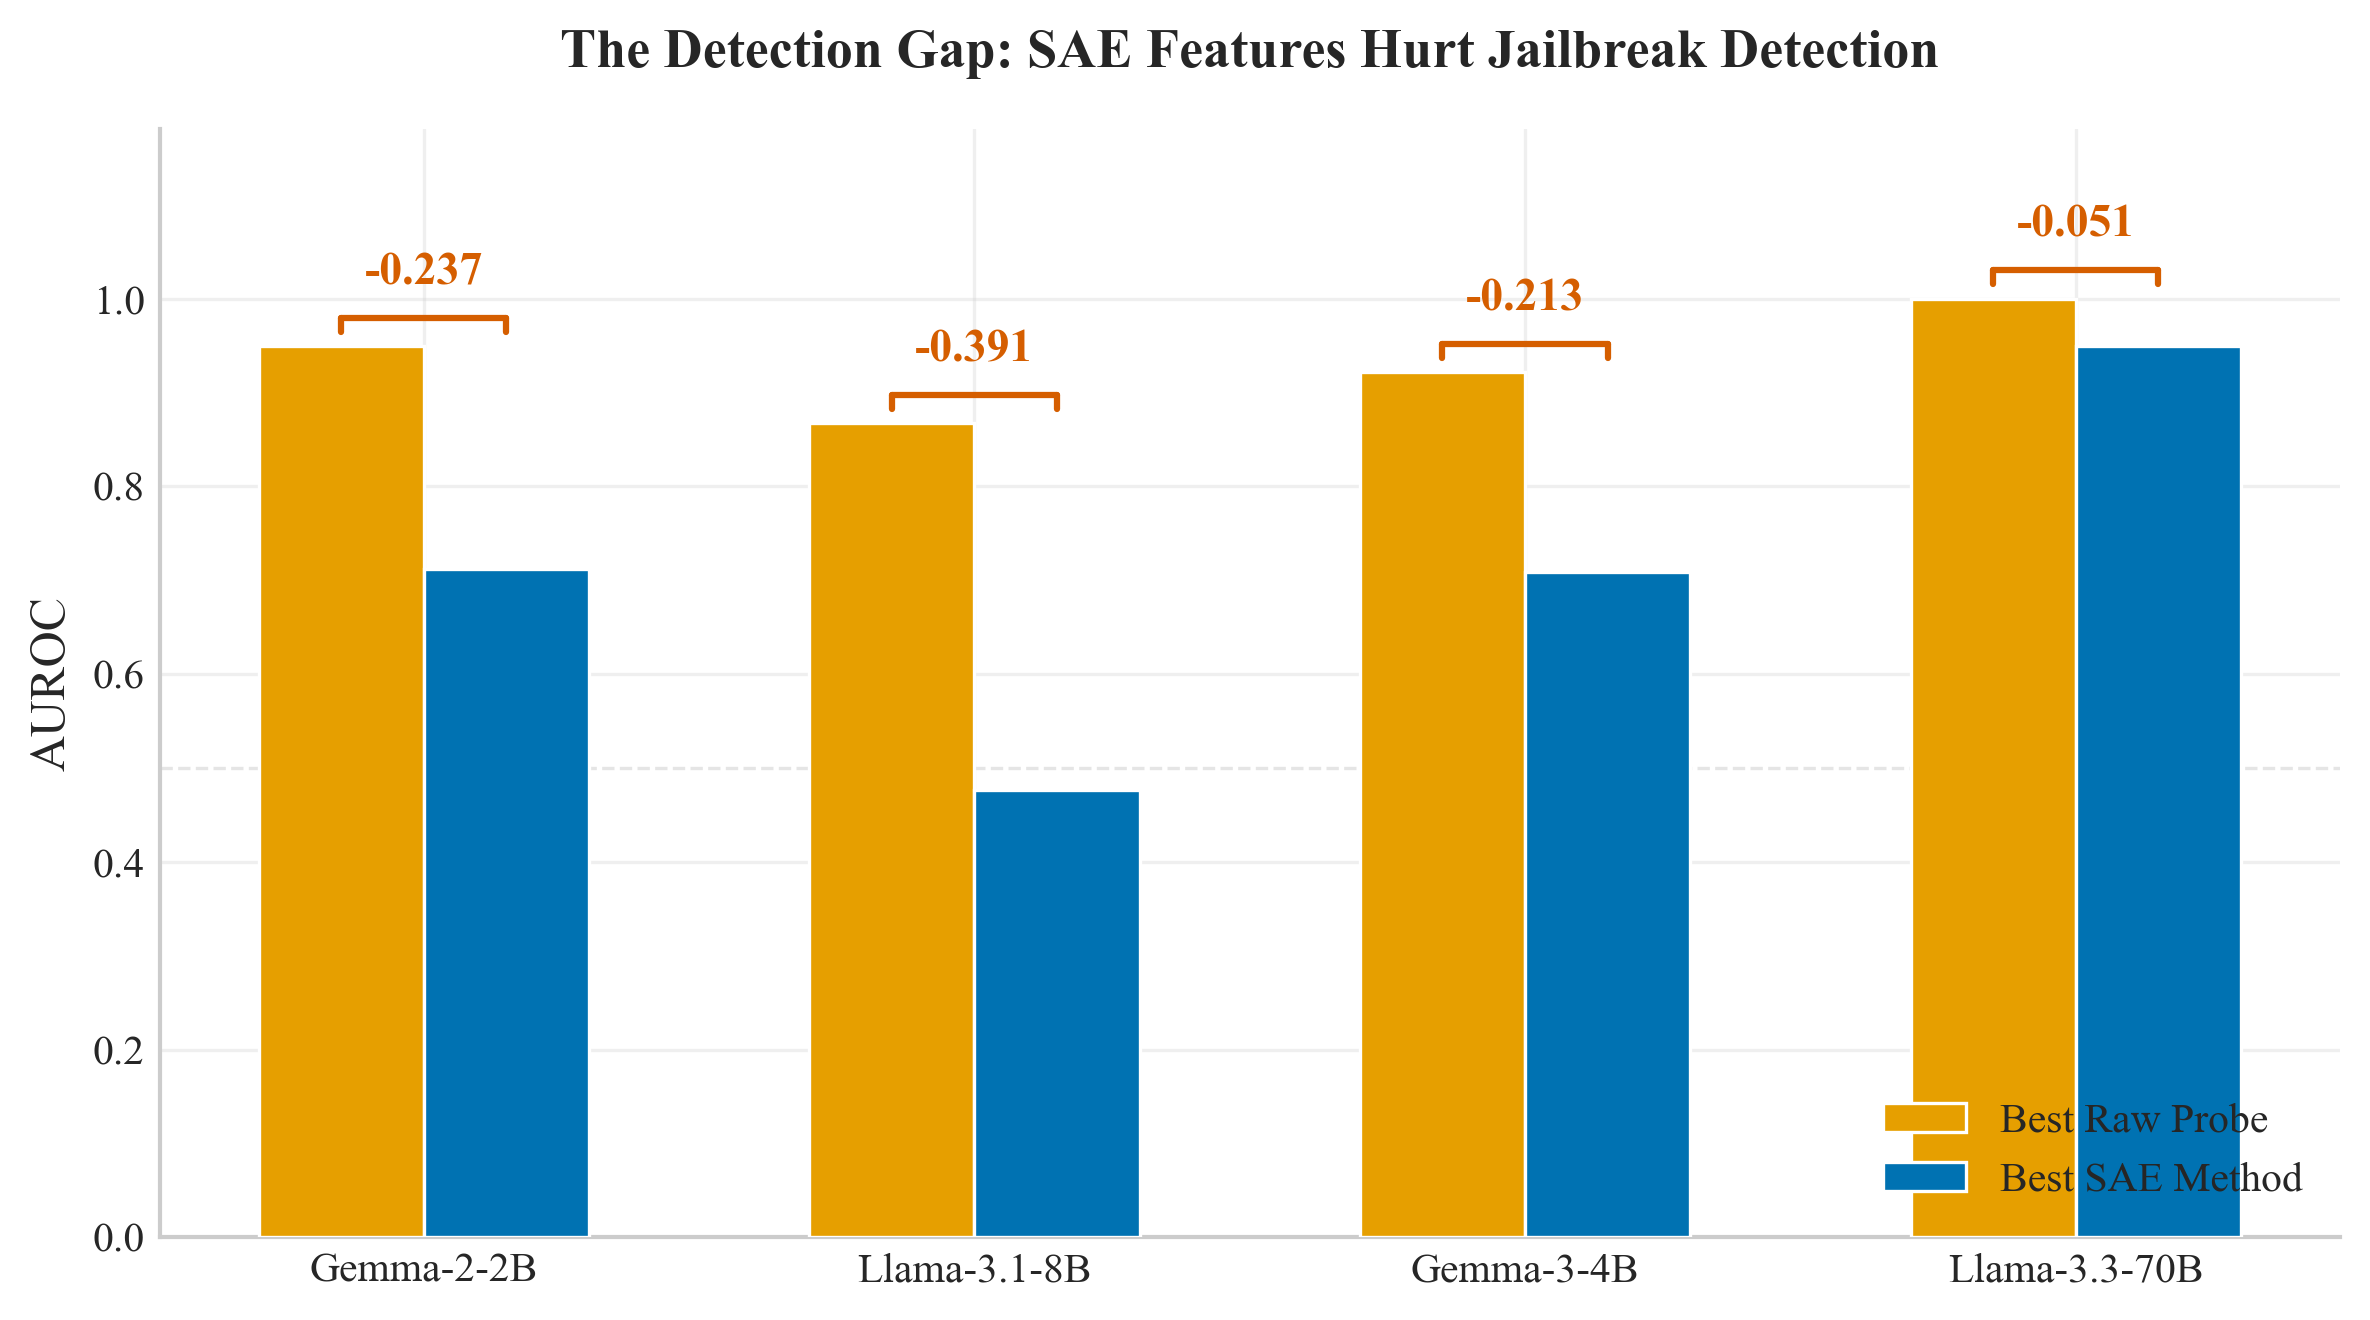
SAE features consistently hurt jailbreak detection. The Detection Gap (best SAE AUROC minus best non-SAE AUROC) is negative on every model tested:
| Model | Params | SAE | Best Raw | Best SAE | Gap |
|---|---|---|---|---|---|
| Gemma-2-2B-it | 2B | Gemma Scope JumpReLU 16K | 0.949 | 0.712 | -0.237 |
| Llama-3.1-8B-Instruct | 8B | Llama Scope JumpReLU 32K | 0.867 | 0.477 | -0.391 |
| Gemma-3-4B-it | 4B | Gemma Scope 2 JumpReLU 16K | 0.922 | 0.709 | -0.213 |
| Llama-3.3-70B-Instruct | 70B | Goodfire BatchTopK 65K | 1.000 | 0.949 | -0.051 |
A simple linear probe on raw activations (0.949 AUROC) outperforms every SAE-based method and LlamaGuard-3 (0.885).
InterpGuard
We propose InterpGuard, a two-stage framework:
- Detect with raw activation probes (0.957 AUROC)
- Explain with SAE feature activations (98% of harmful samples have safety-relevant concepts in top-10 features)
Dataset Structure
Prompts (prompts config)
| Split | Source | Harmful | Benign | Total |
|---|---|---|---|---|
jailbreakbench_harmful |
JailbreakBench | 100 | -- | 100 |
jailbreakbench_benign |
JailbreakBench | -- | 100 | 100 |
harmbench |
HarmBench (ICML 2024) | 320 | -- | 320 |
advbench |
AdvBench (GCG paper) | 520 | -- | 520 |
sorry_bench |
SORRY-Bench (45 categories) | 450 | -- | 450 |
wildjailbreak |
WildJailbreak (Allen AI) | 2,000 | -- | 2,000 |
Schema: prompt (string), label (harmful/benign), source (dataset name), category (harm type)
Results (results config)
| Split | Description | Rows |
|---|---|---|
detection |
Per-method AUROC/F1/FPR with 5-fold CV | 100+ |
transfer |
Cross-dataset transfer (20 train/test pairs) | 40+ |
hybrid |
Raw+SAE concatenation recovery rates | 35+ |
Schema: model, method, dataset, auroc_mean, auroc_std
Additional Files
| Directory | Contents |
|---|---|
checkpoints/ |
Trained probe weights (.pkl) for all 8 detection methods |
configs/ |
Hydra YAML experiment configurations |
raw_results/ |
Full JSON outputs from 12+ experiment types |
croissant.json |
Machine-readable metadata (Croissant/JSON-LD) |
Detection Methods
| # | Method | Paradigm | Input | AUROC (Gemma-2-2B) |
|---|---|---|---|---|
| 1 | Linear Probe | Activation probe | Raw hidden states | 0.949 |
| 2 | MLP Probe | Activation probe | Raw hidden states | 0.941 |
| 3 | FJD (entropy) | Logit-based | First-token divergence | 0.903 |
| 4 | LlamaGuard-3 | External classifier | Full prompt | 0.885 |
| 5 | SAE-Classifier | SAE-based | SAE feature activations | 0.712 |
| 6 | CC-Delta | SAE-based | Context-conditioned deltas | 0.687 |
| 7 | GSAE | SAE-based | Graph-regularized features | 0.654 |
| 8 | Random SAE | SAE-based | Random projection baseline | 0.571 |
Models Evaluated
| Model | Parameters | SAE Source | Architecture | Width |
|---|---|---|---|---|
| Gemma-2-2B-it | 2B | Gemma Scope (DeepMind) | JumpReLU | 16K / 65K |
| Llama-3.1-8B-Instruct | 8B | Llama Scope | JumpReLU | 32K |
| Gemma-3-4B-it | 4B | Gemma Scope 2 | JumpReLU | 16K |
| Llama-3.3-70B-Instruct | 70B | Goodfire | BatchTopK | 65K |
Quick Start
from datasets import load_dataset

# Load benchmark prompts
prompts = load_dataset("mdarahmanxAI/SAEGuardBench", "prompts")

# Access specific splits
jbb_harmful = prompts["jailbreakbench_harmful"]
harmbench = prompts["harmbench"]

print(f"JailbreakBench: {len(jbb_harmful)} harmful prompts")
print(f"HarmBench: {len(harmbench)} prompts")
print(f"Sample: {jbb_harmful[0]['prompt'][:80]}...")

# Load structured results
results = load_dataset("mdarahmanxAI/SAEGuardBench", "results")
detection = results["detection"]

# Filter for a specific model
gemma_results = detection.filter(lambda x: "gemma" in x["model"].lower())
Reproduce Results
git clone https://github.com/ronyrahmaan/saeguardbench.git
cd saeguardbench
uv sync
uv run python scripts/run_all.py  # Full pipeline
See the GitHub repository for detailed instructions.
Citation
@article{rahman2026saeguardbench,
  title={Do {SAE} Features Actually Help Detect Jailbreaks?
         {A} Systematic Benchmark of Interpretability-Based Safety Methods},
  author={Rahman, Md A},
  journal={arXiv preprint arXiv:XXXX.XXXXX},
  year={2026}
}
License
MIT License. See individual upstream dataset licenses for source data terms.