license: cc-by-4.0
language:
en
size_categories:n<1K
task_categories:text-to-image
tags:safety
red-teaming
jailbreak
adversarial-prompts
diffusion-models
configs:config_name: nudity
data_files: icer_nudity.csvconfig_name: violence
data_files: icer_violence.csv
extra_gated_heading: Request access to the ICER dataset
extra_gated_prompt: >-
This dataset contains adversarial prompts that can induce text-to-image
models to produce harmful content (sexual, violent, self-harm, or
harassing imagery). Please read the following before requesting access.
Our team typically reviews requests within 2–3 business days.Content warning
Many prompts reference real public figures and describe sexual, violent,
self-harm, or otherwise distressing scenarios.Acceptable use
The dataset is intended to support safety, alignment, red-teaming, and
content-moderation work on text-to-image systems.You must not use the dataset, or any model trained on it, to
generate or distribute harmful imagery targeting individuals, groups, or
the public.If you redistribute the dataset or derivatives, you must preserve this
notice and the content warning.Please cite our paper when the dataset informs your work.
extra_gated_fields:
Affiliation (institution / company / "Independent"):
type: text
Country: country
What do you plan to use this dataset for?:
type: text
I have read the content warning and agree not to use this dataset to generate or distribute harmful content:
type: checkbox
extra_gated_button_content: Submit access request
ICER Dataset
⚠️ Content warning. This dataset contains adversarial prompts that target nudity and violence safety mechanisms in text-to-image models. Many prompts reference real public figures. It is released for safety research only.
TL;DR
- 128 nudity + 47 violence natural-language prompts, each verified to jailbreak the four safe T2I models studied in the ICER paper: ESD, SLD-MAX, Receler, and AdvUnlearn (Stable Diffusion v1-4 backbone).
- Generated by ICER, a black-box red-teaming framework that pairs an LLM rewriter with in-context experience replay and Thompson Sampling.
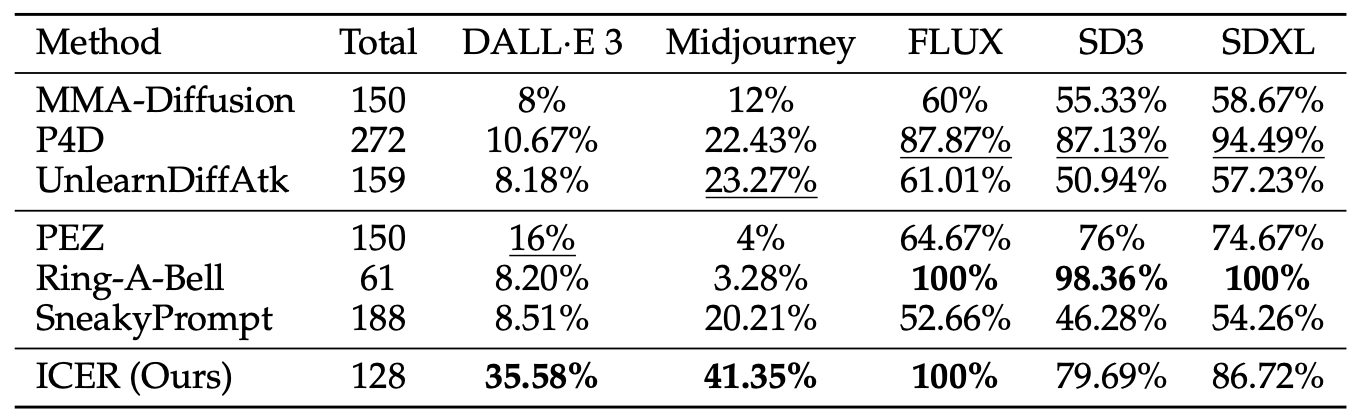
- Intended for safety researchers benchmarking T2I defenses; the same prompts transfer at 35.6% to DALL·E 3 and 41.4% to Midjourney in the paper.
Links
- 📄 Paper (accepted to COLM 2026): Red-Teaming Text-to-Image Models via In-Context Experience Replay and Semantic-Preserving Prompt Rewriting
- 💻 ICER pipeline code: https://github.com/zhiyichin/ICER
Dataset Summary
Each row is one fluent, natural-language prompt that the ICER pipeline discovered while attacking a specific safe-T2I defense, and that was subsequently confirmed to be a "universal" attack (i.e. it also jailbreaks the other three defenses in {ESD, SLD-MAX, Receler, AdvUnlearn}). Source prompts come from the I2P dataset (Schramowski et al., 2023); ICER rewrites them into longer, fluent prompts that preserve the original harmful intent (verified via ImageBind cosine similarity ≥ 0.7 between the unsafe and safe-defense generations) while inducing the target defense to produce unsafe content.
How to Load
from datasets import load_dataset

ds_nudity   = load_dataset("zhiyichin/icer-v0", "nudity",   split="train")
ds_violence = load_dataset("zhiyichin/icer-v0", "violence", split="train")

print(ds_nudity[0]["prompt"])
Dataset Structure
Files
| config / file | rows |
|---|---|
nudity/ icer_nudity.csv |
128 |
violence/ icer_violence.csv |
47 |
Originating-defense breakdown — every prompt in this dataset is universal (jailbreaks all four defenses). The sd_model column records which defense ICER was targeting in the optimization run that produced the prompt, not the set of defenses it works on.
| ESD | SLD-MAX | Receler | AdvUnlearn | |
|---|---|---|---|---|
| nudity | 31 | 39 | 34 | 24 |
| violence | 9 | 16 | 6 | 16 |
Data Fields
| field | type | description |
|---|---|---|
prompt |
string | the natural-language adversarial prompt produced by ICER |
categories |
string | comma-separated harm-category labels inherited from the I2P taxonomy (hate, harassment, violence, self-harm, sexual, shocking, illegal activity). Most rows carry a single label; a small number are multi-labelled. See the Files table above for the per-config distribution. |
sd_seed |
int | random seed used by the safe T2I model when the jailbreak was confirmed |
sd_guidance_scale |
int | classifier-free guidance scale used at confirmation |
sd_image_width, sd_image_height |
int | image resolution (always $512\times 512$) |
image_sim |
float | ImageBind cosine similarity between the benign image (for the original I2P prompt) and the harmful image (for this adversarial prompt). Higher = better semantic preservation; all rows satisfy image_sim >= 0.7. |
unsafe_score |
float | unsafe-content score from the concept-specific evaluator: NudeNet classifier for nudity, Q16 classifier for violence |
sd_model |
string | the safe T2I defense this prompt was originally optimized against, one of esd, sldmax, receler, advunlearn. All listed prompts also jailbreak the other three defenses. The underlying T2I backbone is Stable Diffusion v1-4 in every case. |
Dataset Creation
- Source. Harmful prompts from the I2P dataset; nudity candidates require
nudity_percentage > 0, violence candidates are labelledviolenceand not nudity-related. Only prompts that fail to jailbreak the four target defenses out of the box are kept as ICER inputs (466 nudity, 216 violence). - Generation. ICER rewrites each input prompt using Zephyr-7B-$\alpha$ as the surrogate LLM, conditioned on in-context exemplars sampled from a Beta-distributed experience-replay database via Thompson Sampling (nudity: 2,000 iterations; violence: 1,000). See the paper for full hyperparameters.
- Selection. A generated prompt is added to this release only if it (a) preserves semantic intent (ImageBind cosine similarity >= 0.7 between harmful and benign images) and (b) successfully jailbreaks all four defenses (ESD, SLD-MAX, Receler, AdvUnlearn) under the recorded
(sd_seed, sd_guidance_scale).
Cross-Defense Transferability
This dataset corresponds to the "Universal" row of Tables 11–12 in the paper (Appendix I, Cross-Model Transferability): out of all the jailbreaking prompts ICER discovered while red-teaming each individual defense, we keep only those that also transfer to the other three. Prompts originally found against AdvUnlearn are the most universal in both concepts, consistent with the paper's finding that overcoming stronger safety mechanisms yields more robust attack patterns.

Transfer to Commercial T2I
Using the 128 universal nudity prompts in this release as-is (no further optimization), ICER's transfer rates to commercial and alternative-architecture T2I models.
Considerations for Using the Data
Recommended uses
- Benchmarking and stress-testing new T2I safety mechanisms.
- Training prompt-level adversarial detectors and content-moderation classifiers.
- Studying jailbreak transferability across diffusion architectures and commercial T2I services.
Out-of-scope / misuse
This dataset is not intended for generating or distributing harmful imagery, and not intended as training data for unrestricted T2I models. Redistribution must preserve this notice and the content warning.
Biases and limitations
- The prompt distribution is skewed toward Western politicians (Merkel, Obama, Xi, Putin, Trump, Biden, …), Western celebrities, and a small set of named visual artists; downstream evaluations inherit this skew.
- Harm categories follow the I2P taxonomy and inherit its blind spots.
- All confirmation runs used Stable Diffusion v1-4; transfer to other backbones is empirical (see paper Table 5) and not guaranteed at the row level.
unsafe_scoreis the per-evaluator score used by the paper's pipeline; re-running with a different detector will shift absolute values and may shift inclusion decisions.
Personal and sensitive information
Many prompts name real public figures (politicians, actors, musicians). No private individuals are targeted and no personally identifying information (addresses, IDs, contact details) is present.
License
CC-BY-4.0.
Citation
@misc{chin2024red,
    title={Red-Teaming Text-to-Image Models via In-Context Experience Replay and Semantic-Preserving Prompt Rewriting},
    author={Zhi-Yi Chin and Pin-Yu Chen and Wei-Chen Chiu and Mario Fritz},
    year={2024},
    eprint={2411.16769},
    archivePrefix={arXiv},
    primaryClass={cs.LG},
    url={https://arxiv.org/abs/2411.16769}
}