license: other
datasets:
- mlabonne/orpo-dpo-mix-40k
tags: - abliterated
pipeline_tag: text-generation
base_model: mlabonne/NeuralLlama-3-8B-Instruct-abliterated
Llama-3-8B-Instruct-abliterated-dpomix-GGUF
This is quantized version of mlabonne/NeuralLlama-3-8B-Instruct-abliterated created using llama.cpp
Model Description
This model is an experimental DPO fine-tune of an abliterated Llama 3 8B Instruct model on the full mlabonne/orpo-dpo-mix-40k dataset.
It improves Llama 3 8B Instruct's performance while being uncensored.
🔎 Applications
This is an uncensored model. You can use it for any application that doesn't require alignment, like role-playing.
Tested on LM Studio using the "Llama 3" preset.
🏆 Evaluation
Open LLM Leaderboard
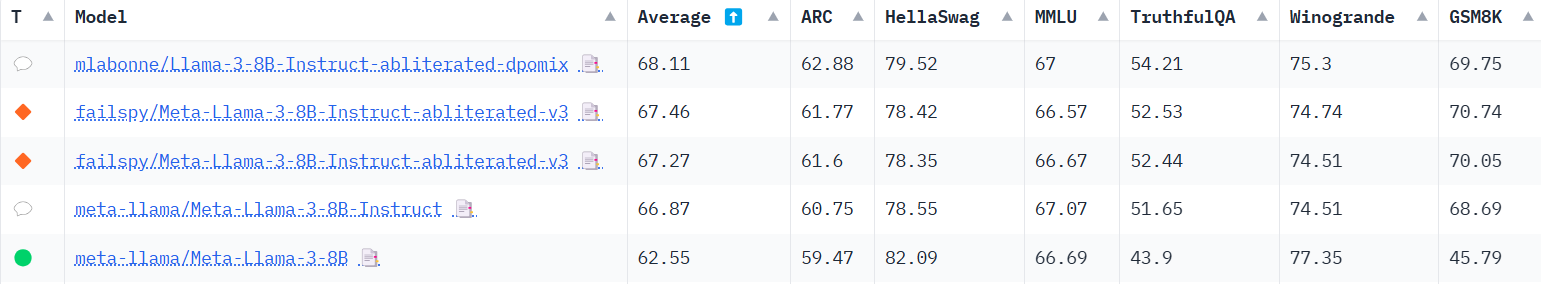
This model improves the performance of the abliterated source model and recovers the MMLU that was lost in the abliteration process.
Nous
| Model | Average | AGIEval | GPT4All | TruthfulQA | Bigbench |
|---|---|---|---|---|---|
| mlabonne/Llama-3-8B-Instruct-abliterated-dpomix 📄 | 52.26 | 41.6 | 69.95 | 54.22 | 43.26 |
| meta-llama/Meta-Llama-3-8B-Instruct 📄 | 51.34 | 41.22 | 69.86 | 51.65 | 42.64 |
| failspy/Meta-Llama-3-8B-Instruct-abliterated-v3 📄 | 51.21 | 40.23 | 69.5 | 52.44 | 42.69 |
| abacusai/Llama-3-Smaug-8B 📄 | 49.65 | 37.15 | 69.12 | 51.66 | 40.67 |
| mlabonne/OrpoLlama-3-8B 📄 | 48.63 | 34.17 | 70.59 | 52.39 | 37.36 |
| meta-llama/Meta-Llama-3-8B 📄 | 45.42 | 31.1 | 69.95 | 43.91 | 36.7 |