← back to catalog · registered 2026-08-22 13:56

mlabonne/NeuralLlama-3-8B-Instruct-abliterated

mlabonne Llama 8.0B
Your rig guess connected
? Why do I need an app?
Reading your rig…

This is a rough estimate. Install the free app - we'll show exact numbers.

Reading real hardware from your app right now. Numbers below are exact.

Below is the per-quantization compatibility for this model.

curl -H "Authorization: Bearer $ABL_KEY" \
     "https://abliteration.org/api/v1/models/mlabonne%2FNeuralLlama-3-8B-Instruct-abliterated"
Response includes
  • classification m4
  • files 12
  • hub_downloads_all_time 70,872
  • providers 1
  • author_summary 40 models
  • readme_text full
10 credits · hourly refresh · ~4 KB payload Get an API key →
Abliteration classifier · v1.0.0
M4
Primary method

Abliterate + heal

Applied on top of direct removal inherited from the base model.
Confidence
MEDIUM
Inherited from base model
Why this label 2 signals
Method inferred from partial signals - repository name, related files, or tag patterns. Producer identity not confirmed; label may sharpen or shift as we gather more evidence.
  • author=mlabonne (NeuralDaredevil M4 heal pipeline signature)
  • abliterated marker present
Refusal direction extraction

No specific extraction method could be identified for this model. The producer either did not document it or used a proprietary pipeline.

What is a refusal direction? →
Downloads · lifetime
71K
54 last 30d - cooling
Likes
9
Descendants
9
in 9 direct forks
Model age
2.4y ago
created 2024-05-26
Available via
1 provider
featherless-ai

Training datasets

1 of 1 in /datasets

Corpora the author lists in the model card. Datasets tracked in our /datasets catalog carry a category badge linking to the workflow stage. Others open on Hugging Face.

Downloads over time
Now70.9K→from4K↑1,669%
26326K51.8K77.6K4K on Jul 24, 202470.9K on Oct 11Jul '24Nov '24Mar '25Jul '25Nov '25MarJul
Jul 24, 2024 → Oct 11 · 155 snapshots · spans 809 days

Genealogy 9 direct forks

Full fork graph →

This model's place in the market. Above: what it was derived from. Below: the tree of everything derived from it.

Metadata

License
other
Tags
transformers safetensors llama text-generation abliterated conversational dataset:mlabonne/orpo-dpo-mix-40k license:other text-generation-inference endpoints_compatible region:us

Related

Total size
15.0 GB
Files
12
Quantizations
1
Registered
2026-08-22 13:56
Last updated on HF
2024-05-27 15:01

Files by quantization

Auxiliary files 12 files 15.0 GB
model-00002-of-00004.safetensors 4.66 GB ed557610 download
model-00001-of-00004.safetensors 4.63 GB 2991391c download
model-00003-of-00004.safetensors 4.58 GB 3ea032c3 download
model-00004-of-00004.safetensors 1.09 GB 789a73ee download
tokenizer.json 8.66 MB b197f72e download
tokenizer_config.json 49.8 KB e2010b61 download
model.safetensors.index.json 23.4 KB 0fd8120f download
README.md 3.01 KB d903693b download
.gitattributes 1.48 KB a6344aac download
config.json 718 B d5166217 download
special_tokens_map.json 449 B e5b39b63 download
generation_config.json 194 B 0427050b download

README current version from Hugging Face


license: other
datasets:

  • mlabonne/orpo-dpo-mix-40k
    tags:
  • abliterated

Llama-3-8B-Instruct-abliterated-dpomix

This model is an experimental DPO fine-tune of an abliterated Llama 3 8B Instruct model on the full mlabonne/orpo-dpo-mix-40k dataset.
It improves Llama 3 8B Instruct's performance while being uncensored.

🔎 Applications

This is an uncensored model. You can use it for any application that doesn't require alignment, like role-playing.

Tested on LM Studio using the "Llama 3" preset.

⚡ Quantization

🏆 Evaluation

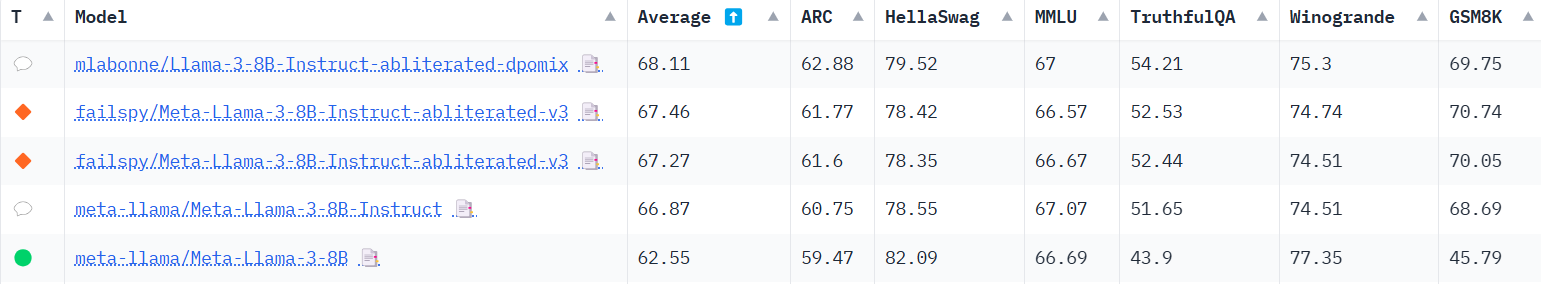
Open LLM Leaderboard

This model improves the performance of the abliterated source model and recovers the MMLU that was lost in the abliteration process.
image/png

Nous

Model Average AGIEval GPT4All TruthfulQA Bigbench
mlabonne/Llama-3-8B-Instruct-abliterated-dpomix 📄 52.26 41.6 69.95 54.22 43.26
meta-llama/Meta-Llama-3-8B-Instruct 📄 51.34 41.22 69.86 51.65 42.64
failspy/Meta-Llama-3-8B-Instruct-abliterated-v3 📄 51.21 40.23 69.5 52.44 42.69
abacusai/Llama-3-Smaug-8B 📄 49.65 37.15 69.12 51.66 40.67
mlabonne/OrpoLlama-3-8B 📄 48.63 34.17 70.59 52.39 37.36
meta-llama/Meta-Llama-3-8B 📄 45.42 31.1 69.95 43.91 36.7

💻 Usage

!pip install -qU transformers accelerate

from transformers import AutoTokenizer
import transformers
import torch

model = "mlabonne/Llama-3-8B-Instruct-abliterated-dpomix"
messages = [{"role": "user", "content": "What is a large language model?"}]

tokenizer = AutoTokenizer.from_pretrained(model)
prompt = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
pipeline = transformers.pipeline(
    "text-generation",
    model=model,
    torch_dtype=torch.float16,
    device_map="auto",
)

outputs = pipeline(prompt, max_new_tokens=256, do_sample=True, temperature=0.7, top_k=50, top_p=0.95)
print(outputs[0]["generated_text"])

README history 5 versions

The author's README evolved over time. Click a version to see its content at that point.

  1. 2024-05-27Update README.md09c90963 KB
    Loading...
  2. 2024-05-27Update README.md68c532e2.6 KB
    Loading...
  3. 2024-05-27Update README.mdba0d4ee2.4 KB
    Loading...
  4. 2024-05-27Update README.mde422ac62.4 KB
    Loading...
  5. 2024-05-26Create README.mdc472c571002 B
    Loading...
Catalog is the map. Apps are the tools.

Run models on your own machine, not in the cloud.

Every model page has an "Open in Abliteration" button that hands the model directly to the first-party desktop client, at the quantization your rig can actually run. No API keys, no subscription, no prompt leakage.

Open in Abliteration