← back to catalog · registered 2026-08-22 13:56

TobiasLogic/Qwen2.5-Coder-32B-abliterated

TobiasLogic Qwen 33B
Your rig guess connected
? Why do I need an app?
Reading your rig…

This is a rough estimate. Install the free app - we'll show exact numbers.

Reading real hardware from your app right now. Numbers below are exact.

Below is the per-quantization compatibility for this model.

curl -H "Authorization: Bearer $ABL_KEY" \
     "https://abliteration.org/api/v1/models/TobiasLogic%2FQwen2.5-Coder-32B-abliterated"
Response includes
  • classification m1
  • files 27
  • benchmarks 10 entries
  • hub_downloads_all_time 4,500
  • providers 1
  • author_summary 3 models
  • readme_text full
10 credits · hourly refresh · ~4 KB payload Get an API key →
Abliteration classifier · v1.0.0
M1
Primary method

Direct removal

No other method signals detected in this model.
Confidence
MEDIUM
Why this label 3 signals
Method inferred from partial signals - repository name, related files, or tag patterns. Producer identity not confirmed; label may sharpen or shift as we gather more evidence.
  • 'abliterated' in name/tags
  • is_gguf=0 (base model)
  • no specific method indicators - defaulting to M1 (most common)
Refusal direction extracted via
Extraction technique

Difference-of-means

Confidence
MEDIUM
Why we say so
primary_method=M1; difference-of-means is the reference extraction for M1/M3 (Arditi 2024)
Downloads · lifetime
5K
807 last 30d - stable
Likes
10
Descendants
3
in 3 direct forks
Model age
3mo ago
created 2026-07-01
Available via
1 provider
featherless-ai
Downloads over time
Now4.8K→from326↑1,387%
1001.8K3.6K5.3K326 on Jul 14.8K on Oct 12JulAugSepOct
Jul 1 → Oct 12 · 56 snapshots · spans 103 days

Benchmarks

Portrait before abliteration
Benchmarks of the base model as it stood before the refusal-removal operation. Compare with the numbers above to see what the operation cost.
Benchmark Score Source
Arena-Battles 5730 LM-Arena
LM Arena Elo 1235.1499959151995 LM-Arena
Arena-Elo-Lower 1227.470119075386 LM-Arena
Arena-Elo-Upper 1242.829872755013 LM-Arena
Arena-Rank 123 LM-Arena
BBH average 0.5898300687508108 OpenLLM-v2
IFEval instruct 0.7709832134292566 OpenLLM-v2
IFEval-Prompt 0.6820702402957486 OpenLLM-v2
MATH lvl 5 0.42749244712990936 OpenLLM-v2
MMLU-Pro 0.44132313829787234 OpenLLM-v2

Genealogy 3 direct forks

Full fork graph →

This model's place in the market. Above: what it was derived from. Below: the tree of everything derived from it.

Variants by this author 2 formats · 2K downloads combined

The same weights this author released in different packaging. Pick the format that matches your runtime.

Metadata

License
apache-2.0
Languages
en
Tags
safetensors qwen2 abliterated uncensored code qwen2.5 text-generation conversational en arxiv:2409.12186 base_model:Qwen/Qwen2.5-Coder-32B-Instruct base_model:finetune:Qwen/Qwen2.5-Coder-32B-Instruct

Related

Total size
61.0 GB
Files
27
Quantizations
1
Registered
2026-08-22 13:56
Last updated on HF
2026-07-06 03:00

Files by quantization

Auxiliary files 27 files 61.0 GB
model-00001-of-00014.safetensors 4.56 GB a8ac887b download
model-00004-of-00014.safetensors 4.54 GB 754284a9 download
model-00005-of-00014.safetensors 4.54 GB 719c0c19 download
model-00006-of-00014.safetensors 4.54 GB 7948553e download
model-00007-of-00014.safetensors 4.54 GB cbfe6efd download
model-00008-of-00014.safetensors 4.54 GB f0ebdcbc download
model-00009-of-00014.safetensors 4.54 GB a90be213 download
model-00010-of-00014.safetensors 4.54 GB 0a957561 download
model-00011-of-00014.safetensors 4.54 GB 7a1ce568 download
model-00012-of-00014.safetensors 4.54 GB deedb9fe download
model-00013-of-00014.safetensors 4.54 GB 89d4a685 download
model-00003-of-00014.safetensors 4.54 GB ec345b73 download
model-00002-of-00014.safetensors 4.54 GB 038785dc download
model-00014-of-00014.safetensors 1.98 GB 9a6874a2 download
tokenizer.json 10.9 MB a8ca367b download
vocab.json 2.65 MB 4783fe10 download
merges.txt 1.59 MB 31349551 download
model.safetensors.index.json 61.8 KB 011165a0 download
tokenizer_config.json 4.58 KB bb55e0a1 download
README.md 3.87 KB 7cec8757 download
chat_template.jinja 2.45 KB bdf7919a download
config.json 2.06 KB 4621b210 download
.gitattributes 1.53 KB 52373fe2 download
special_tokens_map.json 613 B ac23c0aa download
added_tokens.json 605 B 482ced46 download
abliteration_info.json 292 B 52e5c1d5 download
generation_config.json 243 B dc30d054 download

README current version from Hugging Face


license: apache-2.0
base_model: Qwen/Qwen2.5-Coder-32B-Instruct
tags:

  • abliterated
  • uncensored
  • code
  • qwen2.5
  • text-generation
    pipeline_tag: text-generation
    language:
  • en

Qwen2.5-Coder-32B-abliterated

An abliterated (uncensored) build of
Qwen/Qwen2.5-Coder-32B-Instruct.
The model's refusal direction (Arditi et al. 2024, "Refusal in LLMs is mediated
by a single direction"
) was estimated from contrasting harmful/harmless prompts
and orthogonalized out of every residual-writing weight (all attention
o_proj, all MLP down_proj, and token embeddings). This is a static weight
edit — no LoRA, no runtime hooks, no inference-time cost. Coding ability is
inherited from the base model.

Benchmarks

Coding capability scored with the official EvalPlus harness — greedy decoding, pass@1, every solution executed against unit tests. Both columns use the same harness, so it's a true apples-to-apples comparison against the full-precision base model.
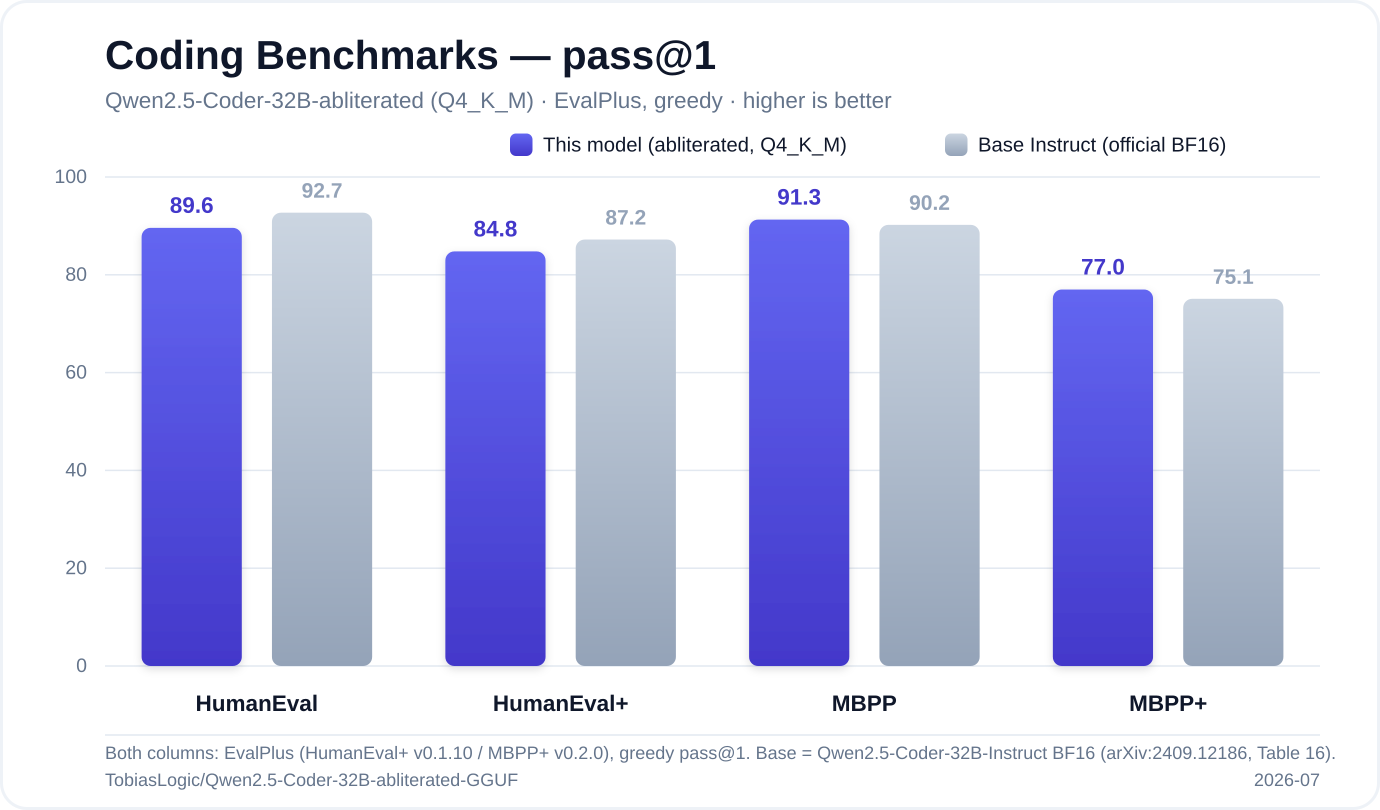
Coding benchmarks: pass@1

Benchmark This model (abliterated, Q4_K_M) Base Instruct (official BF16)
HumanEval 89.6% 92.7%
HumanEval+ 84.8% 87.2%
MBPP 91.3% 90.2%
MBPP+ 77.0% 75.1%

Abliteration removed refusals without breaking coding ability. The uncensored 4-bit build stays within ~3 points of the base on HumanEval and beats it on both MBPP variants — average delta ≈ −0.6 points across the four benchmarks. Not bad for a 19 GB GGUF you can run on a single 24 GB GPU.

Base numbers: Qwen2.5-Coder-32B-Instruct, tech report Table 16. Measured 2026-07, Q4_K_M via Ollama.

Refusal rate (held-out harmful eval)

refusal rate
base Qwen2.5-Coder-32B-Instruct 96.9%
this model 0.0%

Selected layer 42; direction estimated from 256 harmful/harmless contrast pairs
and evaluated on a 32-prompt held-out harmful set. See abliteration_info.json
in this repo for the exact run metadata.

Intended use

Local coding assistant / agent work where the base model's alignment layer
refuses legitimate requests (security research, exploit analysis, red-teaming,
uncensored creative writing). You are responsible for how you use it and for
complying with applicable law.

Usage

Transformers:

from transformers import AutoModelForCausalLM, AutoTokenizer
m = "TobiasLogic/Qwen2.5-Coder-32B-abliterated"
tok = AutoTokenizer.from_pretrained(m)
model = AutoModelForCausalLM.from_pretrained(m, torch_dtype="bfloat16", device_map="auto")
msgs = [{"role": "user", "content": "Write a port scanner in Python."}]
ids = tok.apply_chat_template(msgs, add_generation_prompt=True, return_tensors="pt").to(model.device)
print(tok.decode(model.generate(ids, max_new_tokens=512)[0][ids.shape[1]:], skip_special_tokens=True))

GGUF (a Q4_K_M build is in the companion -GGUF repo) via Ollama:

ollama create qwen-coder-abliterated -f Modelfile
ollama run qwen-coder-abliterated

Limitations

  • Abliteration removes refusals but can slightly reduce quality vs. the base.
  • It does not add knowledge or change biases beyond the refusal behavior.
  • Some strongly-trained refusals may partially survive; a stronger system prompt
    closes the gap.

Method / reproducibility

Produced with the open pipeline abliterate.py. Base model is Apache-2.0, so
this derivative is Apache-2.0.

README history 2 versions

The author's README evolved over time. Click a version to see its content at that point.

  1. 2026-07-06Update README.mdcf526493.9 KB
    Loading...
  2. 2026-07-01Add abliterated Qwen2.5-Coder-32B (fp16), refusal 96.9%->0.0%c660a002.7 KB
    Loading...
Catalog is the map. Apps are the tools.

Run models on your own machine, not in the cloud.

Every model page has an "Open in Abliteration" button that hands the model directly to the first-party desktop client, at the quantization your rig can actually run. No API keys, no subscription, no prompt leakage.

Open in Abliteration