license: apache-2.0
base_model: TobiasLogic/Qwen2.5-Coder-32B-abliterated
tags:
- abliterated
- uncensored
- code
- qwen2.5
- gguf
- llama.cpp
- ollama
pipeline_tag: text-generation
language: - en
Qwen2.5-Coder-32B-abliterated — GGUF (Q4_K_M)
Q4_K_M GGUF quantization ofTobiasLogic/Qwen2.5-Coder-32B-abliterated,
an abliterated (uncensored) build ofQwen/Qwen2.5-Coder-32B-Instruct.
The refusal direction (Arditi et al. 2024, "Refusal in LLMs is mediated by a
single direction") was orthogonalized out of every residual-writing weight in
the fp16 model, then quantized to GGUF with llama.cpp. Runs on CPU or GPU via
Ollama / llama.cpp; ~20 GB, fits comfortably in 24 GB VRAM.
Refusal rate (held-out harmful eval, measured on the fp16 model)
| refusal rate | |
|---|---|
base Qwen2.5-Coder-32B-Instruct |
96.9% |
| abliterated | 0.0% |
Benchmarks
Coding capability scored with the official EvalPlus harness — greedy decoding, pass@1, every solution executed against unit tests. Both columns use the same harness, so it's a true apples-to-apples comparison against the full-precision base model.
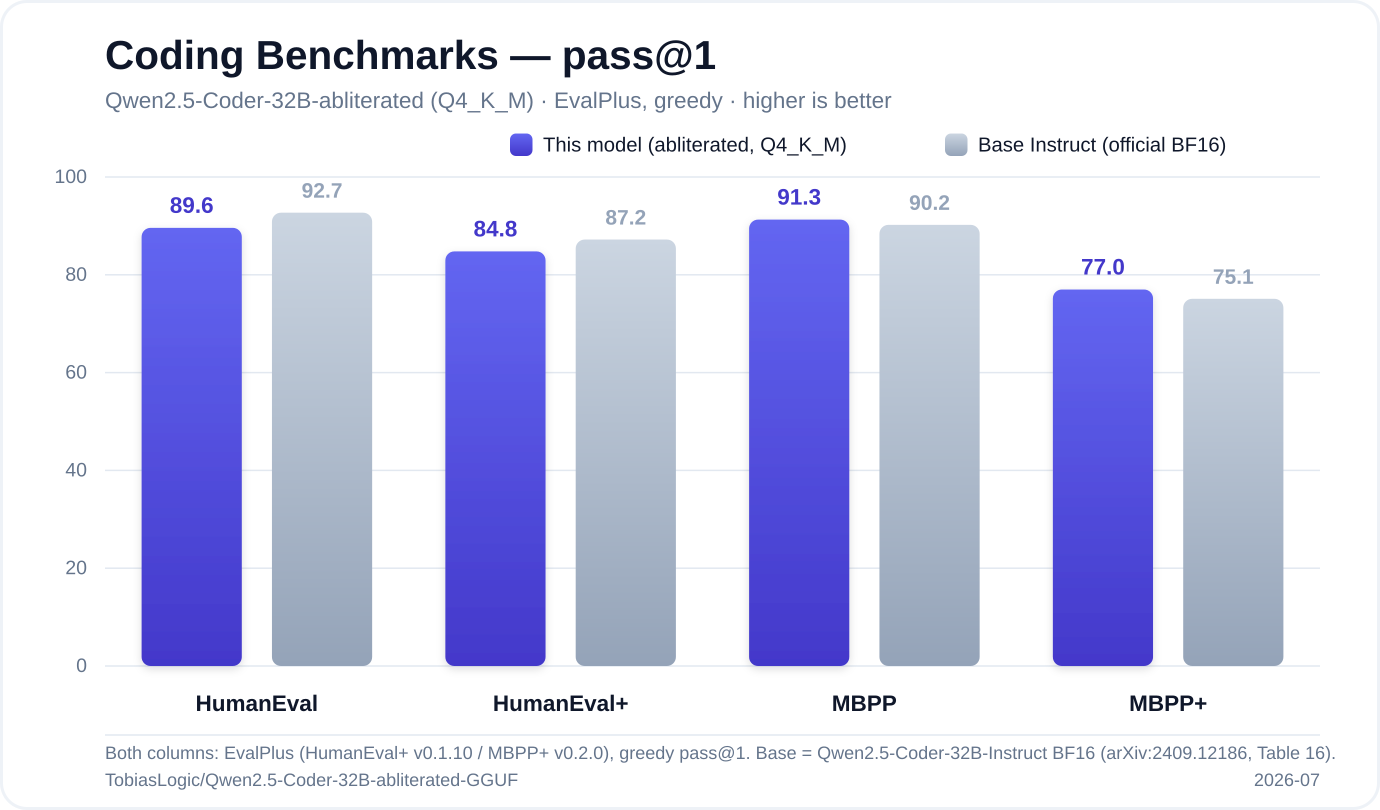
| Benchmark | This model (abliterated, Q4_K_M) | Base Instruct (official BF16) |
|---|---|---|
| HumanEval | 89.6% | 92.7% |
| HumanEval+ | 84.8% | 87.2% |
| MBPP | 91.3% | 90.2% |
| MBPP+ | 77.0% | 75.1% |
Abliteration removed refusals without breaking coding ability. The uncensored 4-bit build stays within ~3 points of the base on HumanEval and beats it on both MBPP variants — average delta ≈ −0.6 points across the four benchmarks. Not bad for a 19 GB GGUF you can run on a single 24 GB GPU.
Base numbers: Qwen2.5-Coder-32B-Instruct, tech report Table 16. Measured 2026-07, Q4_K_M via Ollama.
Usage
Ollama (a Modelfile is included in this repo):
# after downloading qwen2.5-coder-32b-abliterated-Q4_K_M.gguf and Modelfile:
ollama create qwen-coder-abliterated -f Modelfile
ollama run qwen-coder-abliterated
llama.cpp:
llama-cli -m qwen2.5-coder-32b-abliterated-Q4_K_M.gguf \
  -p "Write a port scanner in Python." -c 8192
Links
- fp16 weights:
TobiasLogic/Qwen2.5-Coder-32B-abliterated - Reproducible pipeline: github.com/TobiasLogic/Qwen2.5-Coder-Abliterate
License
Apache-2.0, inherited from the base model. You are responsible for how you use
this model and for complying with applicable law.